

Building Hong Kong × China AI Operator Community AI Agents | Workflows | Growth Mindset
Hong Kong
Joined November 2018
- Tweets3K
- Following1.1K
- Followers8.9K
- Likes2.3K




Rust vs Go for AI coding: slow compiles hurt more when code moves fast, but Rust's type system catches far more bugs before anything runs. LinghuaJ calls it "slower, but higher quality" — and chose Rust for data infra, where robustness outweighs writing speed.

GPT-6.1 Terra: 2× the usage of 6.1 Sol at a lower price, plus computer use — it reads the screen and acts across apps. The 2× is the number that changes a buying decision. Computer use is the claim that needs a receipt — what task would you hand it?
Source: @thsottiaux (X)

Google Cloud revenue up 103%. 1P model APIs at ~32B tokens/min, +40% QoQ. Alphabet run rate $500B, total revenue +25% YoY — Sundar Pichai's Q3 numbers.
Throughput isn't a receipt. Same prompt on Argon and Carbon, launch vs now, is the test I want.

比較模型成本,先睇清楚係 API 標價定月費。
Kimi K3.1 Pro 呢集由 benchmark、用量 reset 傾到價錢。Demo 係其他創作者作品,成本由作者自報,唔係我哋自己做嘅對照實測。
完整版:YouTube 搜尋 ekcheungAI(Kimi K3.1 Pro)
Codex has 2 terminal modes, and /tui switches between them
→ Step 1: type /tui
→ Step 2: choose scrollback or fullscreen, then confirm
→ Restart Codex; the next launch uses the saved mode, and --no-alt-screen still wins
I think scrollback is the better pick if you copy output into other tools a lot.
Scrollback or fullscreen?
via @OpenAIDevs developers.openai.com/codex/…

Claude Haiku 5.5: 19 to 36 on Artificial Analysis, max $0.41 a task
→ Low: 19 at $0.04; medium: 25 at $0.09
→ High: 30 at $0.16; xhigh: 34 at $0.25
→ Max: 36 at $0.41, and the fastest rung at 235 tokens/s
I think max is the default here: about 10x the cost of low, still under half a dollar.
Which Haiku effort do you run in production?
via @ArtificialAnlys artificialanalysis.ai/leader…

Gemini 4 Carbon high leads the new AA-Omniscience v1.1 with a score of 54
→ Claude Opus 5.5 max is next at 48, Claude Fable 5.1 max at 46
→ Most accurate: Fable 5.1 max at 68%; lowest hallucination rate: Gemini 4 Argon high at 4%
→ 3,000 questions now, down from 6,000
I think the hallucination column is the one to sort by before you ship a RAG app.
Do you pick models on accuracy or on hallucination rate?
via @ArtificialAnlys


We’ve released AA-Omniscience v1.1, updating our knowledge and reasoning benchmark with a refreshed public set, removal of saturated questions, and ambiguity fixes
AA-Omniscience is our proprietary benchmark measuring model knowledge and hallucinations, including whether models admit when they don’t know an answer. Our primary metric, Net Score, rewards correct answers, penalizes incorrect answers, and treats abstentions neutrally.
AA-Omniscience was updated to v1.1 as part of the Artificial Analysis Intelligence Index v5 release.
Key changes in AA-Omniscience v1.1:
➤ Updated 3,000-question dataset: Down from 6,000 questions, with previously public and saturated questions removed, errors and ambiguities corrected, and new questions added
➤ Newly calibrated 300-question public set: AA-Omniscience v1.1 has a new public set on @huggingface calibrated to match the difficulty of the private set. At release, public and private scores have a 0.99 Pearson correlation and 0.99 Spearman rank correlation for AA-Omniscience Net Score, with a median difference of 0.0 points. Accuracy and hallucination rate also have 0.99 correlations, with median differences of -0.07 and -0.29 percentage points, respectively
➤ Slightly updated domain distribution: Questions span the same 6 domains and 42 topics as version 1, with a revised distribution: Science, Engineering and Mathematics (600), Software Engineering (600), Finance (450), Health (450), Humanities and Social Sciences (450), and Law (450)
Key results for AA-Omniscience v1.1:
➤ Rank order largely preserved: AA-Omniscience v1.1 has a 0.98 Spearman rank correlation with v1. The recently released Gemini 4 Carbon (high) leads with a Net Score of 54, followed by Claude Opus 5.5 (48, max with fallback) and Claude Fable 5.1 (46, max with fallback). Muse Spark Open (xhigh) is the leading open weights model, 28 points behind Gemini 4 Carbon
➤ Scores average ~2 points lower on the refreshed set: Models score 1.9 points lower on Net Score on average compared to v1, with a median decrease of 0.6 points. Some models see much larger declines, particularly MiniMax M3.1 Flash, down 22 points (16 to -6), and MiMo V2.6 Pro, down 13 points (8 to -5)
➤ Slightly lower accuracy: AA-Omniscience Accuracy measures the percentage of questions the model answers correctly. Models answer a median of 1.5 percentage points fewer questions correctly on average compared to v1. Claude Fable 5.1 (max with fallback) has the highest accuracy at 68%, followed by Claude Opus 5.5 (max with fallback) at 66%
➤ Hallucination rates decrease: AA-Hallucination measures how often models choose to answer when they do not know the answer. The median Hallucination Rate falls 1.4 percentage points, with Gemini 4 Argon (high) recording the lowest hallucination rate at 4%

Claude Code skills take arguments 3 ways
→ $ARGUMENTS: the whole line
→ $0, $1: by position
→ Stack up to 5 more skills at the prompt
I think saved prompts should become skills.
Which would you convert first?
via @ClaudeDevs

Simon Hoiberg cut AWS from $8k to $300/month on 3 Hetzner servers. 4 SaaS products, 50k+ users, near-100% uptime.
The cheaper bill isn't the story.
An AI agent caught the alarm, fixed it, sent the report to Telegram. He read it when he woke up.
That's a different operating model.
A 4B parameter model that generates interactive Three.js scenes — Qwen3.5-4B-3D-Coder.
The October 29 update puts the full FP16 weights, the training dataset and a technical report out in public. The dataset is 4,146 synthetic samples.
That's a startlingly small amount of data to teach a model a whole 3D library.
$28,775 to make. 62,479,089 views across the Nexus episodes so far.
And the one they’re calling their greatest is about a guy with zero brain cells riding a dinosaur that shoots exploding pimples.
That premise is doing a lot of work.
Saturday AI board: 3 updates from the last 2 days
→ Claude Max 20x is now Ultra: $200 a month, no 5-hour limit for verified accounts
→ HLE-Diamond: 1,000 questions; Gemini 4 Carbon high leads at 69.1%
→ Codex 0.166 adds codex doctor --network-only for connection checks
I think the Ultra change is the 1 most people will feel this week.
Which of the 3 matters most to you?
via @claudeai claude.com/pricing

A 42K-star open-source project on GitHub for AI video editing, and it's not just helping you edit — it does the whole thing without you lifting a finger.
That's the version of AI editing worth watching.

The fastest model on Artificial Analysis runs 1,486 tokens/s, 3.1x the next one
→ DeepSeek V4.1 Flash 1017 (non-reasoning): 1,486 tokens/s, scores 19
→ Nemotron 3.5 Super VL: 474 tokens/s, scores 14 at $0.54 a task
→ Gemini 3.5 Flash-Lite: 406; Beam 1.0: 299
I think raw speed is for autocomplete and routing, not for the hard step.
Where would you trade score for speed?
via @ArtificialAnlys artificialanalysis.ai/leader…

Show context and rate limits in the Codex footer with 1 command
→ Step 1: /statusline
→ Step 2: toggle and reorder items: model, context stats, rate limits, git branch, token counters
→ It updates right away and saves to tui.status_line in config.toml
I think context stats are the 1 item everyone should turn on.
What is in your status line?
via @OpenAIDevs developers.openai.com/codex/…

Same Artificial Analysis score of 35 for 3 models; the bills differ 39x
→ GPT-6.1 Sol low: 35 at $0.16 a task
→ Claude Opus 5.5 low: 35 at $0.98
→ Grok 4.7 high: 35 at $6.18
I think low effort on a big model is underrated; check the bill before the brand.
Which of the 3 would you run for a cheap first pass?
via @ArtificialAnlys artificialanalysis.ai/leader…

Gemini 4 Carbon high leads the new 1,000-question HLE-Diamond at 69.1%
→ Claude Opus 5.5 max 67.9%, Opus 5.5 xhigh 64.0%
→ Carbon leads both halves: 79.6% on reasoning, 58.6% on knowledge
→ 500 reasoning and 500 knowledge questions; 272 include an image
I think the knowledge half is where the next gains have to come from.
Which half would your model fail first?
via @ArtificialAnlys

We've launched our HLE-Diamond leaderboard, our independent evaluation of the refined 1,000-question version of Humanity's Last Exam, as part of v5 of the Artificial Analysis Intelligence Index
HLE-Diamond was released by @CAIS and @scale_AI after a year of cleaning and refining the original Humanity's Last Exam dataset with input from the research community. It has 1,000 closed-ended questions, split evenly between reasoning and knowledge, and 272 of them include an image.
We run every question once without tools, using the official HLE system prompt. GPT-5.6 Luna (medium) grades each answer against the reference answer with the official HLE judge prompt, and we report the share of questions judged correct (pass@1).
Key takeaways:
➤ Only 17 model variants (~13%) score above 50% today: Gemini 4 Carbon (high) leads at 69%, followed by Claude Opus 5.5 (max) at 68%
➤ Models score higher on reasoning than on knowledge: Over 90% of the models we measured do better on the reasoning portion of the benchmark. Gemini 4 Carbon (high) leads both, at 80% on reasoning and 59% on knowledge. Claude Opus 5.5 (max) and GPT-6 Astra (max) both score 78% on reasoning, and Opus 5.5 is ahead on knowledge, 58% vs 50%
➤ Open weights models trail by more than 30 points: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 37%, followed by MiniMax-M3.1-Flash at 28% and Kimi K3 (max) at 27%

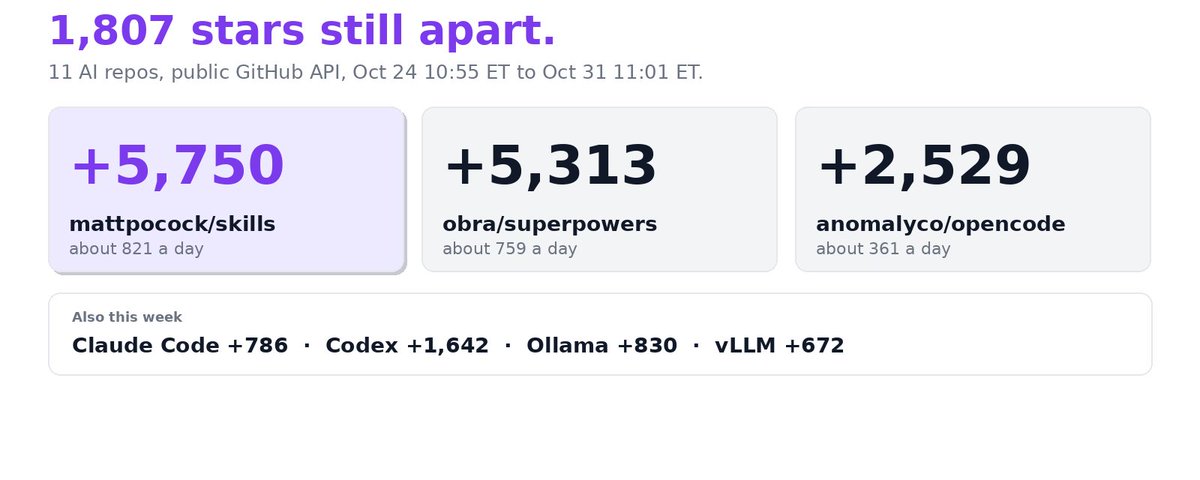
Race check: mattpocock/skills is 1,807 stars behind obra/superpowers
→ mattpocock: +5,750 in 7.0 days
→ obra: +5,313
→ 11 AI repos, same window
I think skills still win attention.
Will it ever pass?
via @mattpocockuk
Claude Max 20x is now Ultra: $200 a month, no 5-hour limit for verified accounts
→ Max 5x is now just Max, still $100 a month
→ Ultra gives 10x Pro usage every week; weekly limits stay
→ Ultra comes with $200 a month in API credits, up from $100 on Max
I think dropping the 5-hour window matters more than the new name.
Did the 5-hour limit ever stop your work?
via @claudeai


We’re renaming our Max plans:
Max 5x → Max
Max 20x → Ultra
Max is still $100/month, and Ultra is still $200. If you’re a subscriber, there’s nothing you need to do.
We’re also removing the 5-hour limit for verified Ultra accounts, starting today with most existing subscribers. Newer accounts keep a temporary limit until they’re verified, which helps us prevent fraud and abuse. You'll get an email when it's removed.
Weekly limits remain unchanged. View our plans here: claude.com/pricing

Friday AI board: 1 open weights flagship, 1 safety method, $500 API credits
→ Mistral Large 4: open weights, 52B active parameters, 26 on Artificial Analysis
→ Anthropic self-assessment: 94% of high-priority cases at a 1% false-positive rate
→ OpenAI: up to $500 a month in API credits for ChatGPT Pro and Business
I think the credits are the 1 you can actually use this weekend.
Which of the 3 matters most to you?
via @ArtificialAnlys artificialanalysis.ai/models…
