
Building something new. Prev: Principal Researcher, Froggy team @ MSR Montréal.
Montréal, Québec
Joined August 2016
- Tweets449
- Following855
- Followers1K
- Likes1.6K


Xingdi Eric Yuan retweeted

⁉️⁉️ What if the harmful data we delete is exactly what makes AI safe?
💬 LLMs have quietly become the first place people turn when something is wrong: a symptom, a debt, a legal problem, a crisis. At this scale, AI safety is no longer an abstract research problem. It touches real lives, every day.
🚫 Yet most alignment today works by erasure: filter out unsafe data and train the model to refuse. The result is often a blanket "Sorry, I can't help with that."
⚠️ But refusing is not the same as being safe. A refusal leaves people with nothing to act on, and it can push them toward riskier, unmoderated sources exactly when they need guidance most.
💡 Here's the irony: unsafe data is abundant and packed with real domain knowledge, while safe, genuinely helpful answers are scarce and costly to curate. And we throw the abundant part away.
🤔 So we asked a counterintuitive question: can unsafe data actually make models safer?
🎉 Our answer is yes, and I'm thrilled to share that this work has been accepted at #NeurIPS2026!
📄 Dialectics of Alignment: Harnessing Unsafe Knowledge for Dynamic Safety Routing
Xingdi Eric Yuan retweeted

Can coding agents learn from experience not just to solve tasks, but to solve them more efficiently?
We share TokenEconomizer, a plugin for coding agents to learn to save tokens given the task streams.
Great work led by Aaron Li: github.com/microsoft/TokenEc…

Vibe coding systems can solve tasks in some unexpected ways. Great work led by @dqwang122 and @isadorcw training agents to solve coding tasks while prioritizing security.


After 11 years at Maluuba and Microsoft Research Montréal, yesterday was my last day. Grateful to everyone I got to build with along the way, especially the Froggy team 🐸.
I'm starting something new with a good friend. Can't say much yet, but it's the most excited I've been in years. More soon.


Xingdi Eric Yuan retweeted

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

Thanks @nathanbenaich for highlighting TaskPilot and FrogNano in this year's @stateofai . We strongly believe that data and training should never exist in isolation; we need to move away from a one-size-fits-all training set!


welcome to the 9th annual @stateofai report!
ai building better ai, world models, physical ai, geopolitics, cyber defense and 12-month predictions.
read it at stateof(dot)ai or watch my editor’s cut here.
a few of this year’s biggest findings follow:
Xingdi Eric Yuan retweeted

🚀 What if AI agents could build the environments that train their next generation?
Excited to share our new work: AutoEnvScaling!
We turn environment design into a terminal task. A proposer agent studies the solver’s rollouts, builds and tests new RL environments, and adapts the curriculum as the solver improves. Build → train → learn → repeat. 🔄
✨ Up to 25× higher valid-environment rate than prompt-only generation, at up to 75% lower cost per valid environment.
📈 With Qwen3.6-35B-A3B playing BOTH proposer and solver, Terminal-Bench 2.1 improves from 41.1 to 53.3.
One model, two roles, an evolving curriculum—a step toward recursive self-improvement.
🌐 Project: microsoft.github.io/Orchard-…
📄 Paper: simonucl.github.io/assets/pd…

Today we open-weights FrogNano 🐸, as well as the minimal Leaf harness plus inference scripts. Enjoy!
huggingface.co/microsoft/Fro…
github.com/microsoft/FrogNan…


This!

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

Great work, this is the real capability one expect their coding AI to have! We tried the same idea in ShadowFrog: 1) blind bug hunting from SWE-bench Verified repos; and 2) blind bug hunting from repos each stacking 100 synthetic SWE-smith bugs. aka.ms/shadowfrog


Xingdi Eric Yuan retweeted

Want to train your SWE agents 2× faster 🏎️💨?
We introduce KV-streams, which, rather than flushing the KV cache on agentic compaction, we preserve it and keep generating. This avoids the re-prefill cost on both the inference engine and the trainer.
Unlike other works that assume a fixed compaction strategy, we show that KV-streams can work with any compaction method in agentic tasks.
Using what we learn from experiments in text-based games. We scale KV-streams to SWE tasks, where we match the performance of re-prefill compaction and full context in half the time 🚀
arxiv.org/pdf/2609.35750
🧵
Xingdi Eric Yuan retweeted

I don't read/write code these days, I only instruct an LRM. But it's not because I think LRM code quality is perfect, or even good. And it's not because I think my instructions are always being perfectly acted upon -- I know they aren't.
The thing is: LRMs don't just write your code, they unlock new ways to control what you're doing and maintain understanding of your system, which are about as effective as reading code. You can better test your codebase, you can audit specific components, you can spin up visualizations, you can ask the LRM to red team, etc. You can do all of these things at high speed -- you couldn't before. The benefits of reading/writing code can now be achieved in new ways.
All in all, the ROI of writing code by hand is no longer looking good, not because LRMs got perfect but because they're so fast at doing things that you can develop new workflows around them, workflows that end up being more productive than the old workflows.
One way we help kids learn (when they Xerox their butt) is to have them reflect on it and write the lesson down. We do something similar when training LLM agents, and found it especially useful as a warm-up when the initial policy can't solve any of the problems in its batch.


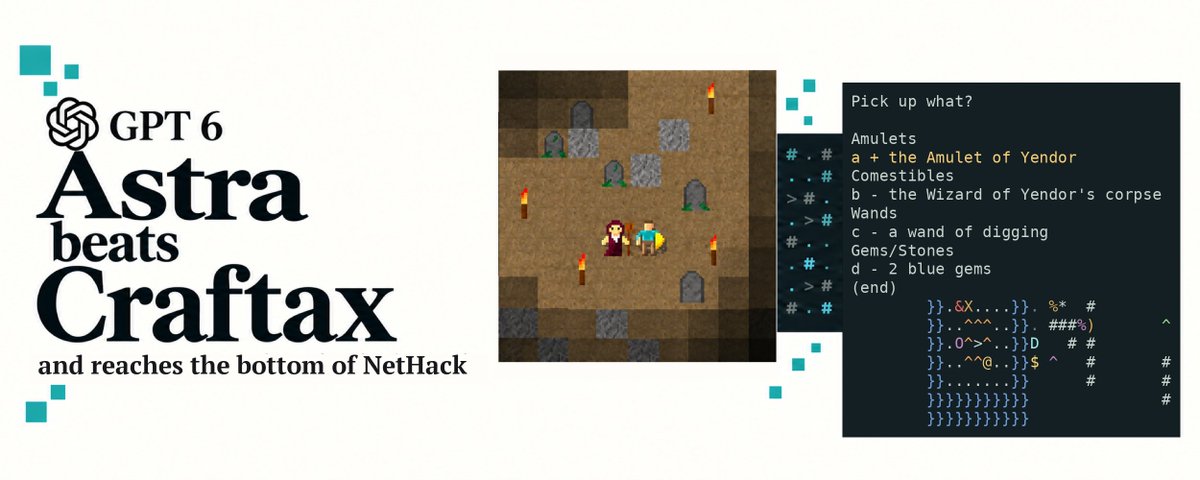
Astra beat Zork, but how? We spent some time trying to understand what's going on.

Some (late) thoughts on Astra beating Zork: christopherzc.github.io/blog…
(TLDR: Astra beat Zork like someone with a walkthrough, not like someone experiencing the game for the first time. Still impressive.)
Xingdi Eric Yuan retweeted

xiaomi MiMo oss RL environments + training code
github.com/XiaomiMiMo/verl
huggingface.co/datasets/Xiao…

ProgramDistill data is now released at huggingface.co/datasets/micr…


🤖 How far are coding agents from working like human developers?
GPT-6 Astra has made big advances in many areas, including coding.
❓ So, can Astra replace a human developer? Our new benchmark says ❗we’re about 49% of the way there.❗
Developers don’t build apps from written requirements alone. They constantly use references—existing apps, UI/UX mockups, prototypes—to see how things should look and work. Then they build it and check their work against the reference.
✨ Introducing ProgramDistill, a benchmark and synthetic task-generation pipeline for testing coding agents on this workflow at scale.
Xingdi Eric Yuan retweeted
the most insane part, they will release ~7k RL training data and the framework leading to this top 6 model on AA, they also shipped the model + tech report less than 1 week after starting the final RL run
pushing both intelligence and openness level, huge congrats


MiMo-V2.6-Pro debuts as the top open weights model on the Artificial Analysis Intelligence Index (46). At $0.13 per Intelligence Index task, it lands on the Intelligence vs. Cost per Task Pareto frontier
@Xiaomi has just released MiMo-V2.6-Pro, an open weights model with major advances in intelligence over its predecessor, MiMo-V2.5-Pro (Intelligence Index: 26). Despite the improvement, it retains the same attractive pricing at $0.435 per 1M input tokens (with a 99% cache-hit discount) and $0.87 per 1M output tokens. This makes MiMo-V2.6-Pro one of the most cost-efficient models to deploy.
MiMo-V2.6-Pro is an MoE model with 1.02T total parameters and 42B active parameters. Stay tuned for additional analysis of the model.
Check out MiMo-V2.6-Pro full benchmarking breakdown here: artificialanalysis.ai


