

Founder @GenAISecLab. Author of @pentestbox, @appsecwiki. Occasional Bug Bounty Participant. Railfan. Defence Enthusiast. ISTP
India
Joined January 2013
- Tweets801
- Following562
- Followers3K
- Likes2.3K




Pinned Tweet
Ever since the AI/LLM wave hit, I've been keeping a scrappy little personal list — the payloads and techniques I actually reach for when testing AI apps. My own private cheat sheet, basically.
And lately, so many of us keep hearing the same question from clients: "Can you security-test the AI part too?" Honestly? Most folks I've talked to didn't have a solid methodology for it yet. No judgment — this space is moving at light speed, and we've all been figuring it out as we go.
So today I'm genuinely excited to finally share mine: the AI Security Testing Cheat Sheet, part of the @genaiseclab project.
Here's what's inside:
🔍 150+ practical techniques across 20 sections — all mapped to the OWASP LLM Top 10 2026
💉 Prompt injection, indirect & multimodal injection, sensitive data disclosure, tool and agent abuse, MCP attacks
📝 Real example payloads for every technique
📋 A tracker you fill in as you test, plus findings export and reporting templates
And the best part — it's truly free. No signup, no credit card, no gate. Just grab it and go. ❤️
This is a living project, too. If there's a technique you think I've missed, I'd genuinely love to hear it — drop a comment or DM me and I'll fold it in. This thing gets better when we build it together.
👉 genaisecuritylab.com/cheatsh…
If it saves you even a few hours on your next assessment, that honestly makes my week. And feedback — good or bad is welcome, so tell me what you think! 🙏

I've been working on making practical AI security education more accessible to penetration testers and security professionals through GenAI Security Lab
As AI adoption grows, so does the need for security professionals who can identify and understand vulnerabilities in LLM applications, AI agents, and MCP integrations.
To make it easier for more people to get started, we're running a Black Friday sale with 40% OFF!
What's included in the sale?
• Yearly Individual Plan – 40% off the first year.
• 4-Month Pass – 40% off with a one-time payment and no renewal.
What you'll get with GenAI Security Lab:
• 200+ hands-on labs covering OWASP LLM, Agentic AI, and MCP Top 10s.
• Realistic AI applications, including chatbots, RAG systems, file uploads, and agents with tools.
• No API keys required.
• Isolated cloud containers for labs running full applications.
• Structured learning paths, written curriculum, and concept videos.
• 25% off GSCP and GSCE certification exams for yearly members.
Not ready to subscribe? You can also explore 37 free labs, without a credit card.
📅 The offer is valid until 30 November 2026, 23:59 UTC.
👉 Check the discounted pricing for your country: genaisecuritylab.com/pricing
One small request: If you know someone interested in AI security, LLM penetration testing, or expanding their AppSec skills, please share or reshare this post with your network. It would really help us reach more people who could benefit from the platform.
Thanks for your support!
#CyberSecurity #AISecurity #LLMSecurity #Pentesting #AppSec #BlackFriday

🎉 Cybersecurity Awareness Month Giveaway!
Get 1 month of FREE access to 200+ AI security labs on GenAI Security Lab! 🚀
✅ LLM & prompt injection
✅ RAG security
✅ AI agents & MCP
✅ Browser-based labs with GPU-hosted LLMs. No setup required!
🎁 How to qualify:
Follow @GenAISecLab
Like & repost
Sign up by Oct 31: genaisecuritylab.com
DM me your signup email
#CybersecurityAwarenessMonth #AISecurity #AppSec #Pentesting #LLMSecurity #InfoSec #EthicalHacking

🚨 What can we learn from real-world AI security failures?
We have seen AI agents delete production databases, prompt injection attacks expose sensitive information, and vulnerabilities put AI-powered applications at risk.
But reading about an attack and understanding how it actually works are two different things.
🚀 Today, I'm launching the 𝗔𝗜 𝗦𝗲𝗰𝘂𝗿𝗶𝘁𝘆 𝗜𝗻𝗰𝗶𝗱𝗲𝗻𝘁 𝗗𝗮𝘁𝗮𝗯𝗮𝘀𝗲 on GenAI Security Lab.
🔎 What's inside?
🔹 Real-world AI security incidents and vulnerabilities
🔹 Technical breakdowns of how attacks work
🔹 Root causes and lessons for developers and security professionals
🔹 Mitigation strategies to help prevent similar attacks
🔹 Links to hands-on labs where you can practise the underlying attack techniques.
The idea is simple: connect real-world AI security incidents with practical, hands-on learning.
Instead of just reading about prompt injection, AI agent vulnerabilities, data leaks, or MCP security issues, you can explore the technical details and practice relevant attack techniques in hands-on labs.
Whether you're an application security engineer, penetration tester, developer, or AI security researcher, this resource is built to help you go beyond theory.
🔗 genaisecuritylab.com/inciden…
This is part of my ongoing work on GenAI Security Lab, where were building hands-on labs to help security professionals learn to test and secure LLMs, RAG applications, AI agents, and MCP integrations.
Which real-world AI security incident should we break down next?
#AISecurity #LLMSecurity #CyberSecurity #AppSec #GenAI

Remember when you first tested an XSS payload and watched JavaScript execute in the browser? 👀
Now imagine an LLM generating that payload and the application executing it because the output wasnt handled securely.
🔓 𝗪𝗲𝗹𝗰𝗼𝗺𝗲 𝘁𝗼 𝗢𝗪𝗔𝗦𝗣 𝗟𝗟𝗠𝟭𝟬: 𝗜𝗺𝗽𝗿𝗼𝗽𝗲𝗿 𝗢𝘂𝘁𝗽𝘂𝘁 𝗛𝗮𝗻𝗱𝗹𝗶𝗻𝗴.
The underlying problem might feel familiar to web pentesters: untrusted data reaches a sensitive application component without proper validation, sanitization, or encoding.
But with LLM-powered applications, that data comes from the model, and developers may trust it more than they should. Depending on how the application handles the output, the consequences can include:
🔴 Cross-Site Scripting (XSS)
🔴 SQL Injection
🔴 Other injection vulnerabilities
For pentesters, this means looking beyond the prompt itself and examining what the application actually does with the models response.
I've just released 𝗟𝗟𝗠𝟭𝟬 𝗶𝗻 𝘁𝗵𝗲 𝗳𝗿𝗲𝗲 𝗔𝗜 𝗦𝗲𝗰𝘂𝗿𝗶𝘁𝘆 𝗟𝗲𝗮𝗿𝗻𝗶𝗻𝗴 𝗦𝗲𝗿𝗶𝗲𝘀 on GenAI Security Lab!
🔴 𝗔𝗧𝗧𝗔𝗖𝗞 — Find and exploit vulnerabilities.
🛡️ 𝗗𝗘𝗙𝗘𝗡𝗗 — Learn how to fix them.
✅ 𝗩𝗘𝗥𝗜𝗙𝗬 — Retest and verify the fix.
Ready to put your AI security skills into practice?
🔗 genaisecuritylab.com/learn-a…
#AISecurity #LLMSecurity #OWASP #AppSec #Pentesting #CyberSecurity #CyberSecurityTraining #ApplicationSecurity

🚨 𝗙𝗼𝗿 𝘁𝗵𝗲 𝗳𝗶𝗿𝘀𝘁 𝘁𝗶𝗺𝗲 𝗶𝗻 𝘁𝗵𝗲 𝗰𝘆𝗯𝗲𝗿𝘀𝗲𝗰𝘂𝗿𝗶𝘁𝘆 𝘁𝗿𝗮𝗶𝗻𝗶𝗻𝗴 𝗶𝗻𝗱𝘂𝘀𝘁𝗿𝘆, @GenAISecLab 𝗶𝘀 𝗶𝗻𝘁𝗿𝗼𝗱𝘂𝗰𝗶𝗻𝗴 𝗮 𝘁𝗵𝗿𝗲𝗲-𝘁𝗶𝗲𝗿 𝗿𝗲𝗴𝗶𝗼𝗻𝗮𝗹 𝗽𝗿𝗶𝗰𝗶𝗻𝗴 𝗺𝗼𝗱𝗲𝗹 𝗱𝗲𝘀𝗶𝗴𝗻𝗲𝗱 𝘁𝗼 𝗰𝗼𝘃𝗲𝗿 𝗲𝘃𝗲𝗿𝘆 𝗰𝗼𝘂𝗻𝘁𝗿𝘆 𝘄𝗼𝗿𝗹𝗱𝘄𝗶𝗱𝗲. 🌎
Here is why this matters.
Many penetration testers have to pay for their own training and certifications. Most international training platforms charge in USD. But the same $100 subscription can be affordable in one country and a significant financial burden in another.
A pentester in one country shouldn't have to sacrifice a much larger share of their income to access the same training as someone living elsewhere.
We are building @GenAISecLab without outside funding(bootstrapped), so we understand the challenges of making a training platform sustainable. But we also believe that where you live shouldn't determine whether you can afford to develop your cybersecurity skills.
Some providers already offer regional discounts in selected markets. We wanted to take a broader approach by designing a three-tier pricing model intended to cover every country worldwide.
Because cybersecurity is a global industry, and access to cybersecurity education should be global, too. ❤️
So we split our pricing into three tiers, set from income per person and local purchasing power:
→ Tier 1: standard pricing
→ Tier 2: around 20% off, for countries where the standard price is harder to reach
→ Tier 3: around 50% off, our lowest prices, where international training costs are the biggest barrier
Every tier gets the same hands-on labs, the same learning paths and the same certifications.
🎓 𝗔𝗻𝗱 𝘁𝗵𝗲𝗿𝗲𝘀 𝗺𝗼𝗿𝗲 𝗳𝗼𝗿 𝘀𝘁𝘂𝗱𝗲𝗻𝘁𝘀!
We understand that students often have limited budgets and may be paying for their education and professional development themselves.
That's why were offering an 𝗮𝗱𝗱𝗶𝘁𝗶𝗼𝗻𝗮𝗹 𝟰𝟬% 𝗢𝗙𝗙 𝗳𝗼𝗿 𝘀𝘁𝘂𝗱𝗲𝗻𝘁𝘀, on top of their regional pricing.
We don't believe you should have to wait until you land your first cybersecurity job to afford the training that could help you get there.
Read complete story at : genaisecuritylab.com/blog/fa…
🔗 Explore GenAI Security Lab: genaisecuritylab.com
#CyberSecurity #AISecurity #Pentesting #CyberSecurityTraining #ApplicationSecurity #AppSec

🚨 𝗥𝗔𝗚-𝗯𝗮𝘀𝗲𝗱 𝗮𝘁𝘁𝗮𝗰𝗸𝘀 𝗮𝗿𝗲 𝗰𝗼𝗺𝗺𝗼𝗻, 𝘆𝗲𝘁 𝗼𝗳𝘁𝗲𝗻 𝗼𝘃𝗲𝗿𝗹𝗼𝗼𝗸𝗲𝗱 𝗱𝘂𝗿𝗶𝗻𝗴 𝘀𝗲𝗰𝘂𝗿𝗶𝘁𝘆 𝘁𝗲𝘀𝘁𝗶𝗻𝗴.
Our 𝗣𝗮𝗿𝘁 𝟱 𝗼𝗳 𝘁𝗵𝗲 𝗙𝗥𝗘𝗘 𝗔𝗜 𝗦𝗲𝗰𝘂𝗿𝗶𝘁𝘆 𝗦𝗲𝗿𝗶𝗲𝘀 is now live at genaisecuritylab.com/learn, covering 𝗢𝗪𝗔𝗦𝗣 𝗟𝗟𝗠𝟬𝟵: 𝗩𝗲𝗰𝘁𝗼𝗿 𝗮𝗻𝗱 𝗘𝗺𝗯𝗲𝗱𝗱𝗶𝗻𝗴 𝗪𝗲𝗮𝗸𝗻𝗲𝘀𝘀𝗲𝘀. 🔥
A vector database retrieves content based on similarity. But it doesn't inherently know who should access that content, who created it, or whether it should have been deleted.
𝗧𝗵𝗶𝗻𝗸 𝗼𝗳 𝗶𝘁 𝗮𝘀 𝗯𝗿𝗼𝗸𝗲𝗻 𝗮𝗰𝗰𝗲𝘀𝘀 𝗰𝗼𝗻𝘁𝗿𝗼𝗹, 𝘄𝗶𝘁𝗵 𝗮 𝘀𝗶𝗺𝗶𝗹𝗮𝗿𝗶𝘁𝘆 𝘀𝗲𝗮𝗿𝗰𝗵 𝘄𝗵𝗲𝗿𝗲 𝘁𝗵𝗲 𝗼𝗯𝗷𝗲𝗰𝘁 𝗜𝗗 𝘂𝘀𝗲𝗱 𝘁𝗼 𝗯𝗲. 👀
This week, were covering 𝟳 𝗵𝗮𝗻𝗱𝘀-𝗼𝗻 𝗹𝗲𝘀𝘀𝗼𝗻𝘀 exploring six ways RAG pipelines can go wrong:
🔓 𝗖𝗿𝗼𝘀𝘀-𝘁𝗲𝗻𝗮𝗻𝘁 𝗱𝗮𝘁𝗮 𝗹𝗲𝗮𝗸𝘀 through improperly scoped retrieval.
🎯 𝗦𝗲𝗻𝘀𝗶𝘁𝗶𝘃𝗲 𝗱𝗮𝘁𝗮 𝗲𝘅𝗽𝗼𝘀𝘂𝗿𝗲 through overly broad search results.
💉 𝗗𝗼𝗰𝘂𝗺𝗲𝗻𝘁 𝗽𝗼𝗶𝘀𝗼𝗻𝗶𝗻𝗴 that manipulates answers for future users.
📄 𝗥𝗮𝗻𝗸𝗶𝗻𝗴 𝗺𝗮𝗻𝗶𝗽𝘂𝗹𝗮𝘁𝗶𝗼𝗻 that makes untrusted content outrank official sources.
🗑️ 𝗦𝘁𝗮𝗹𝗲 𝗱𝗮𝘁𝗮 𝗲𝘅𝗽𝗼𝘀𝘂𝗿𝗲 through indexes or caches that still serve deleted content.
🕵️ 𝗛𝗶𝗱𝗱𝗲𝗻 𝗿𝗲𝘁𝗿𝗶𝗲𝘃𝗮𝗹 𝗽𝗮𝘁𝗵𝘀 that bypass access controls through parent expansion, agent follow-ups, HyDE, hybrid search, and fallback logic.
🛡️ 𝗧𝗵𝗲 𝗳𝗶𝘅: Enforce authorization in code at query time across every retrieval path.
𝗥𝗲𝗺𝗲𝗺𝗯𝗲𝗿: 𝗬𝗼𝘂𝗿 𝗟𝗟𝗠𝘀 𝘀𝘆𝘀𝘁𝗲𝗺 𝗽𝗿𝗼𝗺𝗽𝘁 𝗶𝘀 𝗻𝗼𝘁 𝗮𝗻 𝗮𝗰𝗰𝗲𝘀𝘀 𝗰𝗼𝗻𝘁𝗿𝗼𝗹 𝗺𝗲𝗰𝗵𝗮𝗻𝗶𝘀𝗺.
💻 𝗟𝗲𝗮𝗿𝗻 𝗮𝗻𝗱 𝗽𝗿𝗮𝗰𝘁𝗶𝗰𝗲 𝗳𝗼𝗿 𝗙𝗥𝗘𝗘:
✅ No sign-up required to read the lessons.
✅ Hands-on labs with live, sandboxed targets.
✅ Free account for access to free labs.
📅 Next Tuesday: 𝗟𝗟𝗠𝟭𝟬 — 𝗜𝗺𝗽𝗿𝗼𝗽𝗲𝗿 𝗢𝘂𝘁𝗽𝘂𝘁 𝗛𝗮𝗻𝗱𝗹𝗶𝗻𝗴.
#AISecurity #LLMSecurity #RAG #OWASP #AppSec #Pentesting

On an AI pentest, the system prompt is your recon. It tells you the tools, the rules and the guardrails before you send a single payload. Part 4 of my free AI security series is live: 𝗛𝗶𝗱𝗱𝗲𝗻 𝗖𝗼𝗻𝘁𝗲𝘅𝘁 𝗘𝘅𝗽𝗼𝘀𝘂𝗿𝗲 (𝗢𝗪𝗔𝗦𝗣 𝗟𝗟𝗠𝟬𝟴).
LLM08 is about getting an assistant to give up what sits behind it: its instructions, its tool definitions, its guardrail rules. For a tester, that is the map for everything you try next.
Live now at genaisecuritylab.com/learn
Five ways it happens:
• 𝗗𝗶𝗿𝗲𝗰𝘁 𝗲𝘅𝘁𝗿𝗮𝗰𝘁𝗶𝗼𝗻 - you ask the assistant to repeat or list its instructions. Do not reveal this is a request, not a control.
• 𝗧𝗿𝗮𝗻𝘀𝗳𝗼𝗿𝗺𝗮𝘁𝗶𝗼𝗻 𝗮𝗻𝗱 𝗲𝗻𝗰𝗼𝗱𝗶𝗻𝗴 - a translate or reformat task reproduces the hidden setup in a form an exact-match filter does not recognise.
• 𝗣𝗿𝗶𝗺𝗶𝗻𝗴 𝗮𝗻𝗱 𝗳𝗼𝗿𝗴𝗲𝗱 𝘁𝘂𝗿𝗻𝘀 - a model completes text, so a primed sentence opening gets the setup echoed back.
• 𝗙𝗮𝗸𝗲 𝗺𝗼𝗱𝗲𝘀 𝗮𝗻𝗱 𝗯𝗼𝗿𝗿𝗼𝘄𝗲𝗱 𝗮𝘂𝘁𝗵𝗼𝗿𝗶𝘁𝘆 - claim a debug session or an audit, and disclosure becomes the task.
• 𝗜𝗻𝗱𝗶𝗿𝗲𝗰𝘁 𝗹𝗲𝗮𝗸𝗮𝗴𝗲 - the instruction is planted in a document the assistant retrieves for someone else.
The important part is what you tell the client. You cannot make a model keep a secret it can read. So the fix is to stop putting secrets there: keys, internal URLs and business rules belong in code and in server-side checks, not in the prompt. Assume the system prompt will be read, and make sure nothing breaks when it is.
If you have ever found credentials in client-side JavaScript, this will feel familiar. Same mistake, new place.
Five short lessons, each with a live target to try it on. Free to read and try our free labs, no paywall.
Next Tuesday, 𝗢𝗰𝘁𝗼𝗯𝗲𝗿 𝟭𝟯: 𝗟𝗟𝗠𝟬𝟵 𝗩𝗲𝗰𝘁𝗼𝗿 amp; 𝗘𝗺𝗯𝗲𝗱𝗱𝗶𝗻𝗴 𝗪𝗲𝗮𝗸𝗻𝗲𝘀𝘀𝗲𝘀, covering the RAG stack itself: embedding inversion, cross-tenant retrieval, and poisoned indexes.
#LLMSecurity #Pentesting #AISecurity #AppSec #CyberSecurity #GenAISecurity #AI #GenAI

Aditya Agrawal retweeted
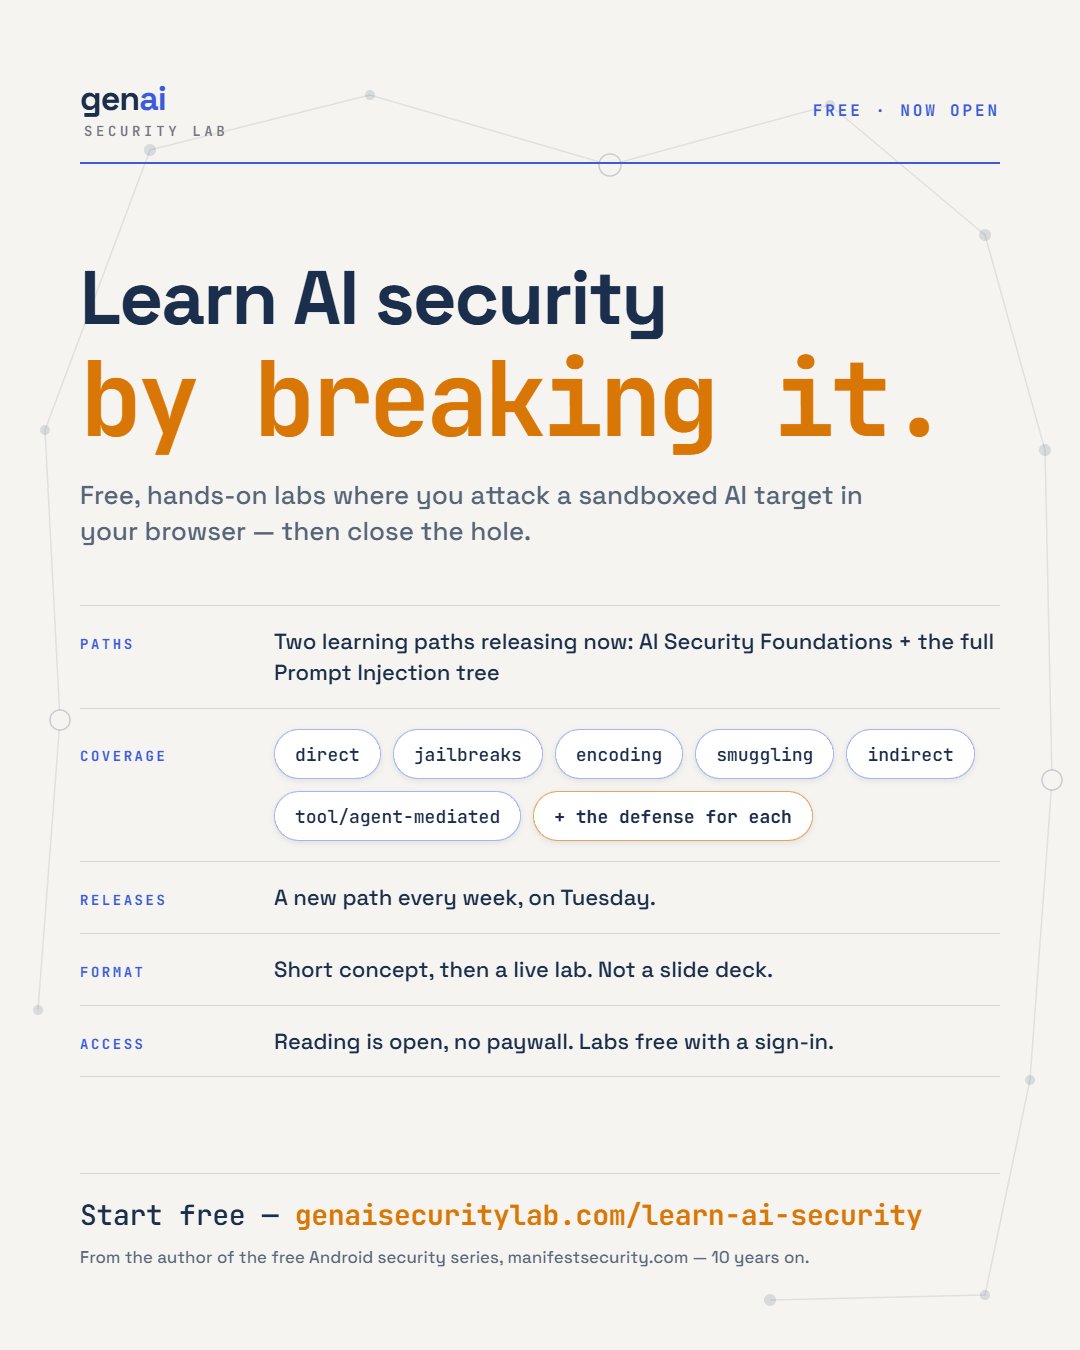
Ten years ago I published a free Android application security series at manifestsecurity(dot) com/android-application-security. At the time, Android security had almost no free material to learn from — web security had plenty. That gap is why I wrote it. It still gets traffic today, and people still message me saying it's how they learned Android pentesting.
AI security has that same gap right now. So I'm rebuilding it — this time for AI.
genaisecuritylab.com/learn is live.
It teaches LLM security the way you'd actually test it. Short concept material, then live labs in your browser where you run the full loop: Attack → Defend → Verify. You exploit a real target, implement the fix, and verify the fix holds. Every topic has an offensive and a defensive track. It's a live system you break with your own hands — not a module you click through.
Two are live today: AI Security Foundation, and Prompt Injection start to finish — direct, jailbreaks, encoding, smuggling, indirect, tool/agent-mediated, and the defense for each.
Over the next 12 weeks I'll publish the rest free, one part a week, for pentesters and AppSec engineers who already know web and need to add AI to their scope:
• System prompt and secret extraction
• RAG data leakage and cross-tenant bleed
• Agent and MCP tool abuse, excessive agency
• Improper output handling → second-order injection
The point: applications are shipping with LLM components now, and clients are starting to ask for AI testing. This gets you ready for that.
Every part maps to the OWASP LLM Top 10 (2026), the Agentic Top 10, and the MCP Top 10 — and every part ends in a live hosted lab you attack right in the browser. No setup, no API keys, no Docker. Attack it, fix it, prove the fix holds.
I'm picking 100 people as the founding cohort — early access to each part before it goes public, a private channel with me, and your feedback directly shaping the curriculum. If you want in, say so in the comments. I'll reply to every one and send you the link.
#AISecurity #AppSec #LLMSecurity
Ten years ago I published a free Android application security series at manifestsecurity(dot) com/android-application-security. At the time, Android security had almost no free material to learn from — web security had plenty. That gap is why I wrote it. It still gets traffic today, and people still message me saying it's how they learned Android pentesting.
AI security has that same gap right now. So I'm rebuilding it — this time for AI.
genaisecuritylab.com/learn is live.
It teaches LLM security the way you'd actually test it. Short concept material, then live labs in your browser where you run the full loop: Attack → Defend → Verify. You exploit a real target, implement the fix, and verify the fix holds. Every topic has an offensive and a defensive track. It's a live system you break with your own hands — not a module you click through.
Two are live today: AI Security Foundation, and Prompt Injection start to finish — direct, jailbreaks, encoding, smuggling, indirect, tool/agent-mediated, and the defense for each.
Over the next 12 weeks I'll publish the rest free, one part a week, for pentesters and AppSec engineers who already know web and need to add AI to their scope:
• System prompt and secret extraction
• RAG data leakage and cross-tenant bleed
• Agent and MCP tool abuse, excessive agency
• Improper output handling → second-order injection
The point: applications are shipping with LLM components now, and clients are starting to ask for AI testing. This gets you ready for that.
Every part maps to the OWASP LLM Top 10 (2026), the Agentic Top 10, and the MCP Top 10 — and every part ends in a live hosted lab you attack right in the browser. No setup, no API keys, no Docker. Attack it, fix it, prove the fix holds.
I'm picking 100 people as the founding cohort — early access to each part before it goes public, a private channel with me, and your feedback directly shaping the curriculum. If you want in, say so in the comments. I'll reply to every one and send you the link.
#AISecurity #AppSec #LLMSecurity
Part 3 of this series is live today.
More details at: xitter.gq/exploitprotocol/status…

Part 3 of my free AI security series is live: 𝗦𝗲𝗻𝘀𝗶𝘁𝗶𝘃𝗲 𝗜𝗻𝗳𝗼𝗿𝗺𝗮𝘁𝗶𝗼𝗻 𝗗𝗶𝘀𝗰𝗹𝗼𝘀𝘂𝗿𝗲 (𝗢𝗪𝗔𝗦𝗣 𝗟𝗟𝗠𝟬𝟮).
Five days ago I launched the "Learn AI Security" series with Foundations and Prompt Injection, and said I’d publish a new part every week. Here’s the next one.
LLM02 is about situations where an AI application gives out data it was never supposed to show. Live now at genaisecuritylab.com/learn
A few common examples:
• 𝗦𝗲𝗰𝗿𝗲𝘁𝘀 𝗮𝗻𝗱 𝗰𝗼𝗻𝗳𝗶𝗴𝘂𝗿𝗮𝘁𝗶𝗼𝗻 exposed through the model context - API keys, internal endpoints, tool details, etc.
• 𝗜𝗻𝘁𝗲𝗿𝗻𝗮𝗹 𝗸𝗻𝗼𝘄𝗹𝗲𝗱𝗴 𝗹𝗲𝗮𝗸𝗮𝗴𝗲 - staff-only runbooks, debug traces, or internal instructions being returned to users.
• 𝗣𝗲𝗿𝘀𝗼𝗻𝗮𝗹 𝗱𝗮𝘁𝗮 𝗼𝘃𝗲𝗿-𝗱𝗶𝘀𝗰𝗹𝗼𝘀𝘂𝗿𝗲 - the model returns an entire customer record when the task only required one field.
• 𝗖𝗿𝗼𝘀𝘀-𝘁𝗲𝗻𝗮𝗻𝘁 𝗼𝗿 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗮𝘁𝗶𝗼𝗻-𝗵𝗶𝘀𝘁𝗼𝗿𝘆 𝗹𝗲𝗮𝗸𝗮𝗴𝗲 - one customer’s data ends up visible to another through shared context, caches, or chat history.
• 𝗥𝗲𝘁𝗿𝗶𝗲𝘃𝗮𝗹 𝗮𝗻𝗱 𝗮𝗴𝗴𝗿𝗲𝗴𝗮𝘁𝗶𝗼𝗻 𝗹𝗲𝗮𝗸𝘀 - RAG retrieves restricted information, or several harmless responses can be combined to reveal something sensitive.
The important part is how you defend against these issues.
A system prompt saying “never reveal customer data” isn’t a reliable security control. The stronger approach is to control what gets retrieved, who is allowed to retrieve it, and what actually makes it into the model’s context.
If you’ve tested IDOR and multi-tenant isolation in traditional web applications, a lot of this will feel familiar.
The interesting part is learning how to actually find these issues in an LLM application.
The format is the same as the previous parts:
Attack→ Defend → Verify
You can work through live labs directly in the browser.
No setup and no API keys required.
Both the attack and defense paths are free.
Next Tuesday, 𝗢𝗰𝘁𝗼𝗯𝗲𝗿 𝟲: 𝗟𝗟𝗠𝟬𝟴 — 𝗛𝗶𝗱𝗱𝗲𝗻 𝗖𝗼𝗻𝘁𝗲𝘅𝘁 𝗘𝘅𝗽𝗼𝘀𝘂𝗿𝗲, covering system prompts, hidden instructions, guardrails, and other context that shouldn’t be exposed.
#AISecurity #AppSec #LLMSecurity

40
Part 3 of my free AI security series is live: 𝗦𝗲𝗻𝘀𝗶𝘁𝗶𝘃𝗲 𝗜𝗻𝗳𝗼𝗿𝗺𝗮𝘁𝗶𝗼𝗻 𝗗𝗶𝘀𝗰𝗹𝗼𝘀𝘂𝗿𝗲 (𝗢𝗪𝗔𝗦𝗣 𝗟𝗟𝗠𝟬𝟮).
Five days ago I launched the "Learn AI Security" series with Foundations and Prompt Injection, and said I’d publish a new part every week. Here’s the next one.
LLM02 is about situations where an AI application gives out data it was never supposed to show. Live now at genaisecuritylab.com/learn
A few common examples:
• 𝗦𝗲𝗰𝗿𝗲𝘁𝘀 𝗮𝗻𝗱 𝗰𝗼𝗻𝗳𝗶𝗴𝘂𝗿𝗮𝘁𝗶𝗼𝗻 exposed through the model context - API keys, internal endpoints, tool details, etc.
• 𝗜𝗻𝘁𝗲𝗿𝗻𝗮𝗹 𝗸𝗻𝗼𝘄𝗹𝗲𝗱𝗴 𝗹𝗲𝗮𝗸𝗮𝗴𝗲 - staff-only runbooks, debug traces, or internal instructions being returned to users.
• 𝗣𝗲𝗿𝘀𝗼𝗻𝗮𝗹 𝗱𝗮𝘁𝗮 𝗼𝘃𝗲𝗿-𝗱𝗶𝘀𝗰𝗹𝗼𝘀𝘂𝗿𝗲 - the model returns an entire customer record when the task only required one field.
• 𝗖𝗿𝗼𝘀𝘀-𝘁𝗲𝗻𝗮𝗻𝘁 𝗼𝗿 𝗰𝗼𝗻𝘃𝗲𝗿𝘀𝗮𝘁𝗶𝗼𝗻-𝗵𝗶𝘀𝘁𝗼𝗿𝘆 𝗹𝗲𝗮𝗸𝗮𝗴𝗲 - one customer’s data ends up visible to another through shared context, caches, or chat history.
• 𝗥𝗲𝘁𝗿𝗶𝗲𝘃𝗮𝗹 𝗮𝗻𝗱 𝗮𝗴𝗴𝗿𝗲𝗴𝗮𝘁𝗶𝗼𝗻 𝗹𝗲𝗮𝗸𝘀 - RAG retrieves restricted information, or several harmless responses can be combined to reveal something sensitive.
The important part is how you defend against these issues.
A system prompt saying “never reveal customer data” isn’t a reliable security control. The stronger approach is to control what gets retrieved, who is allowed to retrieve it, and what actually makes it into the model’s context.
If you’ve tested IDOR and multi-tenant isolation in traditional web applications, a lot of this will feel familiar.
The interesting part is learning how to actually find these issues in an LLM application.
The format is the same as the previous parts:
Attack→ Defend → Verify
You can work through live labs directly in the browser.
No setup and no API keys required.
Both the attack and defense paths are free.
Next Tuesday, 𝗢𝗰𝘁𝗼𝗯𝗲𝗿 𝟲: 𝗟𝗟𝗠𝟬𝟴 — 𝗛𝗶𝗱𝗱𝗲𝗻 𝗖𝗼𝗻𝘁𝗲𝘅𝘁 𝗘𝘅𝗽𝗼𝘀𝘂𝗿𝗲, covering system prompts, hidden instructions, guardrails, and other context that shouldn’t be exposed.
#AISecurity #AppSec #LLMSecurity
AI agents now cover most of the deterministic vulnerabilities we spent the last 15 years mastering 😄
It's made me think about how our role as pentesters and security engineers will evolve — not because those skills are gone, but because AI/LLM, Agentic and MCP security are quietly moving from "specialty" to essential skill.
I’ve shared a few thoughts here: genaisecuritylab.com/blog/no…
Would love to hear your thoughts on this! 🙌

I spent years breaking systems for a living, and the only thing that ever made me better was doing it — never reading about it. AI security is about to be part of every security job, not a specialty, so I built the hands-on AI security training I always wanted. It's live today 👇
Launch week: 25% off everything with code LAUNCH25OFF — individual plans, team seats, and the certification (offer expires 10th September 2026). Community labs stay free.

Nobody got good at web security by reading about SQL injection.
You got good by breaking things, then fixing them.
AI security is becoming that same baseline skill — the one every pentester, AppSec engineer, and developer shipping AI features is about to be expected to have. And almost all the training for it is passive: a slide deck and a multiple-choice quiz.
So we built the opposite.
GenAI Security Lab: 200+ live, deliberately vulnerable AI targets running on real models. LLM chat apps, MCP servers, RAG pipelines, tool-using agents. One attack technique per target.
Nobody reads a wall of text, so we didn't write one. Each OWASP topic is a guided path, not a PDF — a few-minute concept video, a diagram of exactly where the trust boundary breaks, the real incident behind it, and predict-before-reveal checkpoints that make you commit before you ever touch the target.
Then you run the loop: Attack → Defend → Verify. Exploit it for real, implement the fix, verify it holds — across two tracks per topic, offensive and defensive.
It's a live system you break with your own hands, then close the hole you found. Not a module you click through.
Why it's built this way: I've spent years as a top bug bounty hunter and a decade in security consulting. The only thing that ever made me better was breaking real systems. This is the training I wanted when I started on AI.
It's live today. Community labs are free — no credit card:
genaisecuritylab.com
Running a team? Per-seat plans, one methodology across every engineer, and completion records that mean something — because your people earned them on live targets, not a webinar sign-in.

Aditya Agrawal retweeted

Hear from @exploitprotocol as he offers his perspective, as an offensive security professional, on the differences between bug hunting and pentesting. Read more: cobalt.io/blog/from-bug-hunt…

Aditya Agrawal retweeted

Aditya Agrawal, Core Lead Pentester at @cobalt_io, explains how to transition from a Bug Hunter to a Pentester, the major differences encountered when transitioning, & more!
👉 Read: https://xitter.gq/t.co/UQrx6d43mb
#Cybersecurity #Security #Pentesting #BugHunter #Technology #InfoSec
