



Francesco Virga retweeted

We believe access to capable open-source cyber models is our constitutional right as Americans under the 2nd Amendment.
It is our duty as technologists and patriots to help protect the digital infrastructure that powers the world's largest economy.
As such, we’re serving our cyber models “at-cost”, in US data centers only, with ZDR enabled by default.
We do not plan to make money serving these models.
If you run a company that is considering how to best protect against cybercrime, reach out to me or @atbeme. We’d be happy to advise.
KYC required. Apply below.

deepseek-v4.1-flash-1017-cyber is now available on @inference_net.
This is the first of several highly capable cyber models we'll release over the coming weeks.
We believe it is our duty as technologists to help people protect themselves and their digital properties from the current onslaught of cybercrime ravaging much of the world.
As such, we’re serving our cyber models “at cost”, in US data centers only, with ZDR enabled by default.
KYC required. Apply here inference.net/models/deepsee…

Francesco Virga retweeted
🚀 We're excited to be an official Day 0 Provider for @MiniMax_AI M3.1 Flash!
Built for coding, agents, and complex workflows, M3.1 Flash brings powerful capabilities at a competitive cost.
We tried it out on a few prompts...

Francesco Virga retweeted

OpenRouter has the most rigorous integration process of any router
I love that they’re so focused on making sure they have the very best quality on the platform and they push providers to get better (including us!)
Great for users, great for the market, long live OpenRouter
This quoted post is unavailable.
Francesco Virga retweeted
kimi-k3 is live on openrouter and we have both the lowest price and top 5 in throughput @inference_net
come get your tokens while they're hot 🍪!
more models dropping soon!


I’m excited to announce that @inference_net is officially back on @OpenRouter !
First models launching: schematron-v2-turbo and schematron-v2-small
A lot more models coming soon :)
openrouter.ai/inference-net/…

Francesco Virga retweeted
Introducing loupe !
We love bugbot at @inference_net but decided to build our own so we can take advantage of our own models and customize the experience a bit
github.com/context-labs/loup…

Francesco Virga retweeted

Someone was asking about PlanetScale today at AIE and I was explaining who our customers were and then I was like hold on let me show you and I pulled up our latest homepage on my phone and just gave it a quick scroll and they said:
“wait. what does this mean?”
I said these are companies that run on @PlanetScale
their response:
“Holy fuck”
Yessir, holy fuck indeed.


Francesco Virga retweeted
If you want an inference provider with built in evals, use @inference_net.
Legacy inference providers require you to have accounts on “partner” products, which is not ideal for fast moving companies in 2026.

We're making GLM-5.2 available in Braintrust today with the help of our friends at @baseten.
This means you can run evals on GLM and compare it to other models for specific tasks, which is exactly what we did.
When testing long-context retrieval Opus 4.8 is only modestly more accurate given relative costs.
Opus 4.8 leads GLM-5.2 by about 3.5 points at both 25K and 50K tokens, but at the same context sizes, Opus costs about 4.1x to 4.5x more per trace.
@iz_hurley_ wrote it up here: braintrust.dev/blog/glm-52-v…

Francesco Virga retweeted
Want to try GLM 5.2 in production but worried how it might change your product?
Don’t worry, we got you:
1. Install Inference Gateway (docs.inference.net)
2. Keep sending traffic to your current provider
3. Gateway automatically starts sorting through your live data using an RLM to generate evals for your app. This takes ~24 hours.
4. Gateway starts mirroring live traffic to GLM 5.2 to run evals. Traffic is only mirrored - you’re still using your old provider in prod.
5. Once evals look healthy, you get a Slack notification letting you know it’s safe to switch.
6. Switch model identifier in your code to “glm-5.2”
Congrats, you just saved 90% on your monthly token bill, and you own your LLM stack end to end.

⬆︎open source inference⬆︎

META BRAIN MODEL | NEW AGENT BILL | FABLE BACK SOON? xitter.gq/i/broadcasts/1nxeLLOWp…


HALO is insanely good. Essentially every harness can benefit from this sort of deep trace analysis. Models are good enough to work around failures, but that doesn’t mean the agents are running optimally.
We use HALO on HALO and it’s constantly finding obscure bugs and optimizations.


Francesco Virga retweeted
Specialized models are becoming a practical path to better AI UX.
Olive moved from a frontier model to a custom model trained with Inference Catalyst for their food verdict workflow.
After a user scans a product, the model now delivers near-instant verdicts on what to watch out for, making the in-store experience faster and more seamless while cutting inference cost significantly.
Results:
- p50 latency: 2,721ms → 591ms
- p99 latency: 6,414ms → 998ms
- time to first word: ~0.25s
- inference cost: ~70% lower
Great working with @oliveholistic on this!
Full case study here: inference.net/case-study/oli…

Help your agent help itself

3 weeks ago we open-sourced HALO
this led to talking with dozens of teams running agents at scale
we realized the current agent monitoring tools aren't built for the future that we so clearly see ahead of us
today we’re releasing native OpenTelemetry-compatible agent tracing on @inference_net, powered by the same open-source core behind HALO
Francesco Virga retweeted

Shout out to @samhogan @AmarSVS @francescodvirga @atbeme @mikepollard_dev and the rest of the Inference dot net team


Francesco Virga retweeted
We’re introducing HALO 😇
Hierarchal Agent Loop Optimizer
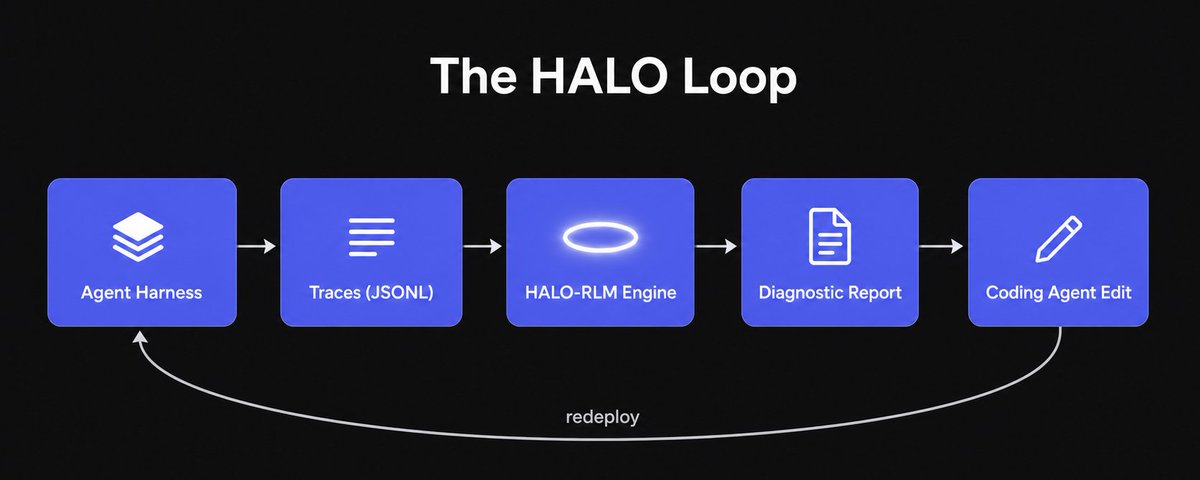
HALO is an RLM-based agent optimization technique capable of recursively self-improving agents by analyzing their execution traces and suggesting changes.
This work is inspired by the Mismanaged Genius Hypothesis proposed by @a1zhang and @lateinteraction earlier this month.
tldr; we improved performance on AppWorld (Sonnet 4.6) from 73.7 --> 89.5 (+15.8) by giving HALO-RLM access to harness trace data and asking it to identify issues.
The feedback from HALO surfaced failures in the harness such as hallucinated tool calls, redundant arguments in tools, refusal loops, and semantic correctness issues. Each issue mapped cleanly to a direct prompt update.
We then fed these finding into Cursor (Opus 4.6), and asked the coding agent to update the underlying harness.
We repeated this trace -> HALO-RLM analysis -> code update loop until the score plateaued.
Today we’re open-sourcing the core HALO-RLM framework, evals, and data for further review.

Francesco Virga retweeted
Excited to launch Day One support for tracing the Cursor Agent SDK with @inference_net
3 lines of code is all you need to track agent performance across executions and iterate to perfection
Docs below 👇


Francesco Virga retweeted

Frontier LLMs can do a lot—but can they write good flashcards?
Turns out: not yet! @andy_matuschak and I created an eval for flashcard generation and found surprisingly poor results.
Worse, newer models aren’t helping: GPT 5.4 performs worse than 5.2, Opus 4.7 worse than 4.6.

ALT Scatter plot of frontier model performance on the Memory Machines eval by model release date.