

Postdoc @ Meta FAIR
Turin
Joined March 2022
- Tweets187
- Following399
- Followers479
- Likes231






If you like recipes that scale without bells and whistles, and learn robust representations from images alone, check out our latest work!
Super happy to have contributed to this with such an amazing team!

Gabriele Trivigno retweeted

Very happy to share that I recently joined @Meta Superintelligence Labs, FAIR as a Research Scientist Intern on the Segment Anything team, based in New York 🗽
A big thanks to @kate_saenko_ and @nikhilaravi for this incredible opportunity!

Gabriele Trivigno retweeted

This paper went completely under the radar!
Meta researchers have developed a novel and simple self-supervised learning framework competitive with DINOv2 and DINOv3!
"Scalable Patch-Level Self-Supervised Learning"
The authors introduce JEM, a principled student-teacher method that learns to align patch representations across different views. Additionally, it incorporates explicit regularization to ensure representations are informative and prevent structural collapse.
The framework outperforms DINOv2 in a controlled setting on dense tasks, and even beats the DINOv3 checkpoint despite it being trained on 12x less data.

This week I'll be at #ECCV2026 in Malmö!
A few places to catch me:
- Thursday morning
at the Meta booth
- Friday at 11am: spotlight talk at the Meta booth on DINOv3 & CHMv2
- Friday at 4pm: presenting our “FoundYou” paper, poster #334
Come say hi if you’re around, or if you want to grab a coffee! 👋

Snap a photo of your favorite t-shirt. 👕
Now imagine Segment Anything 2 could scan through thousands of images, find the exact same t-shirt, and segment it every time it shows up.
We’re excited to share FoundYou: A Unified Model for Personalized Segmentation and Retrieval, accepted at #ECCV2026! 🎉
Check out FoundYou:
Code: github.com/ga1i13o/FoundYou
Paper: arxiv.org/abs/2608.29917v1
Try FoundYou yourself, to find your items within a db of 100M images:
gmberton.github.io/demos-url…
Gabriele Trivigno retweeted
Had so much fun at #CVPR2026! 🎉
Really happy to have presented two papers this year and discussed them with so many people.
Both projects came out of my time at @visinf, TU Darmstadt, last year. Very grateful to @stefanroth for hosting me and helping shape them from the beginning, and to all my co-authors for being part of this 😊

That’s a wrap for #CVPR2026 in Denver!
Despite it being my 5th CVPR, this one was a year of firsts:
• first time presenting an Oral paper
• first time presenting at a booth, with the DINO project at Meta
• first live demo
Grateful for the great conversations, feedback, and energy throughout the week!


Today!
I'm going to present MARCO in Oral Session 4D at 2 pm, and later at poster #20!
Don't miss it :)

✨#CVPR2026 Oral ✨
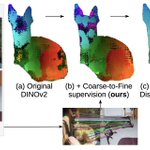
A tale of a failed experiment: what if you fine-tune DINOv2 on sparse keypoints, beat every benchmark, only to discover it performs worse than the original frozen model on novel keypoints?
🚀MARCO closes this gap: a unified model for generalisable correspondences
github.com/visinf/MARCO

Gabriele Trivigno retweeted
✨ #CVPR2026 Oral ✨
INSID3 turns a frozen DINOv3 into a training-free in-context segmenter across domains and granularities!
Excited to present our work today in Oral Session 4D (14:00–15:15). Come by our poster later if you’d like to chat:
📍 Poster #19
🕓 16:00–18:00
See you there!

Just landed in Denver for #CVPR2026! 🏔
Excited to present two oral papers:
📍 June 6, 14:00–15:15 — Oral Session 4D: Visual Segmentation
• INSID3: Training-Free In-Context Segmentation with DINOv3
• MARCO: Navigating the Unseen Space of Semantic Correspondence
Posters later that day, 16–18:
• #19 — INSID3
• #20 — MARCO
Also on June 4:
• MARCO @ Workshop on Image Matching
• INSID3 @ Workshop on Visual Concepts
And don’t miss our demo:
🗓 June 5, 16–18 — FoundYou
Happy to chat, come find us around! 👋


Gabriele Trivigno retweeted
✨#CVPR2026 Oral ✨
A tale of a failed experiment: what if you fine-tune DINOv2 on sparse keypoints, beat every benchmark, only to discover it performs worse than the original frozen model on novel keypoints?
🚀MARCO closes this gap: a unified model for generalisable correspondences
github.com/visinf/MARCO
What if a model could learn dense semantic matches from just a handful of annotated landmarks, while still generalizing to unseen keypoints and categories — and running 10× faster than diffusion-based approaches?
MARCO is selected as an Oral at #CVPR2026! A unified model for generalizable semantic correspondence, built on DINOv2⭐️
👉 Try our model: github.com/visinf/MARCO
3) To evaluate beyond standard benchmarks, we introduce a new benchmark with 62 novel categories from diverse domains, including animal species, furniture, and clothing, all unseen during training.
We also include novel keypoint annotations on known categories, increasing coverage (e.g., from 7 to 68 landmarks for human face)
This enables evaluation along two axes of generalization: to novel categories and to novel keypoints within known ones.
