

A CLI coding agent, inference layer, and spend console all in one. Powered by open-source models.
- Tweets55
- Following6
- Followers245
- Likes15





ALT Speaker card for KubeAuto Day North America, November 9. “I will be speaking: Hermes + Kimchi = AI-Native Engineering by Default.” Žilvinas Urbonas, Vice President of Engineering, Kimchi, pictured in a black t-shirt on a blue background. kubeauto.day/north-america


ALT Diagram showing where each part of an AI coding agent runs: the tools, the agent loop and the model. Each can run on your own infrastructure or in a vendor’s cloud. When the model runs in the vendor’s cloud, code and context leave your network.

ALT Table titled “Where each part runs,” comparing where execution, the agent loop and inference run for four setups. Cursor self-hosted workers: execution on customer infrastructure, agent loop and inference in the vendor cloud. GitHub Copilot with data residency: inference with the vendor, in-region. Kimchi Serverless: local harness, local loop, inference on Kimchi GPUs with regional endpoints. Kimchi Self-hosted: local harness, local loop, inference in the customer’s Kubernetes. Below: “The disconnect-my-internet test: remove all access to outside networks. Can the application, agent and model still perform the required workflow?”

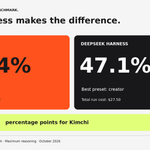
ALT Benchmark results card comparing DeepSeek Harness and Kimchi on the same model and benchmark. DeepSeek Harness, best preset (creator): 47.1% task pass rate, total run cost $27.50. Kimchi: 69.4%, total run cost $36.03. Kimchi leads by 22.3 percentage points. Headline: the harness makes the difference. Terminal-Bench, GLM 5.3 Flash, maximum reasoning, October 2026.


ALT Benchmark results card. Same model, same benchmark: the harness makes the difference. Kimchi: 69.4% task pass rate, total run cost $36.03. DeepSeek Harness, best preset (creator): 47.1%, total run cost $27.50. Kimchi leads by 22.3 percentage points. Terminal-Bench, GLM 5.3 Flash, maximum reasoning, October 2026.


ALT Kimchi promotional card on a dark New York skyline background with the Brooklyn Bridge. Text reads: "Meet Kimchi team at AI Engineer NYC. October 12 to 14, 2026. Booth 17. Sheraton New York Times Square Hotel." Kimchi and AI Engineer New York logos.