
@Prompt_Driven, serial founder (@a16z, @GVteam, @MenloVentures), former @CityofPaloAlto Councilman, e/acc #AI @Caltech @UCBerkeley
Palo Alto, CA
Joined August 2009
- Tweets829
- Following765
- Followers6.4K
- Likes3.9K


Then 8-bit. Everyone asks: how much accuracy do I lose?
• BF16: 37/40
• 8-bit: 37/40
• same 3 failures
• zero pass/fail flips
On this sample: no measurable loss.
Harness, raw outputs, hashes, methodology, limitations — all public:
github.com/promptdriven/pdd/…
Next: randomized runs, hidden tests, engine-level prefill timing across more Apple Silicon.
What should I test next?
#MLX #AppleSilicon #LocalLLM #Qwen
Credit + folks who'd have opinions on the 16K prefill reversal:
@awnihannun @Prince_Canuma @Alibaba_Qwen @JustinLin610 @ivanfioravanti @0xkydo @outsource_ @reach_vb @simonw
fcmeyer (HF) made the MTP conversions — no X account I could find.
First question: does speculative decoding change what the model says?
MTP off vs on, same weights:
• 39/40 byte-for-byte identical
• 37/40 pass in both
• same 3 failures
97.5% exact-output agreement.
How much speed for that?
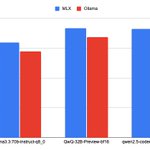
MTP decode speedup:
• 1K: 1.84×
• 4K: 2.18×
• 16K: 2.19×
The main model verifies every drafted token — you get speed, not a different model.
Native MTP via MLX (@awnihannun, @Prince_Canuma).

Setup, all local via MLX:
① BF16, standard decode
② BF16 + native MTP
③ 8-bit (oQ8e) + MTP
Weights: fcmeyer's Qwen3.8-27B-MLX-bf16-mtp conversion of @Alibaba_Qwen's model. ① is just ② with MTP off.
40-task coding harness, deterministic.
I ran Qwen3.8 27B three ways on a 128GB M4 Max.
8-bit decoded ~1.7× faster than BF16.
It was also 12.5% SLOWER at 16K context.
Same coding score. Same 3 failures.
Here's what tok/s doesn't tell you 🧵

The AI productivity paradox, solved:
LLMs are best at generating software that already exists which is exactly the sw nobody pays for
Infinite supply → price of zero
The only sw that makes money now is the sw AI can't generate & that's precisely the sw that's hardest to build
🤖 Made with AI

Greg Lin Tanaka retweeted

Saturday 7/25
‣ Build Fast. Launch Loud. Prompt Driven Hackathon luma.com/1c8vmqyr
@gregtanaka
‣ The Michigan Reunion 2026 - Young Alumni Mixer partiful.com/e/sqzr4qX4fnmMA…
@vparv3
‣ YC AI Startup School Afterparty luma.com/m4ez9liu
@usemoss @TheFounderLuke @xskvth @srimalireddi @ajhinh @modal @MarketerGraham
‣ Mind Games AI Hackathon + Exclusive Napa Retreat luma.com/xtrace-e47u
@fromaustinc @trisgwync
‣ Scalekit x Meetstream Agents in Production Build Day SF luma.com/xhogf93u
@sniperblacz
‣ Build Fast. Launch Loud. Prompt Driven x Deskree Hackathon luma.com/1c8vmqyr
‣ The Board Walks meetup.com/the-board-walks-s…
@theboardtalks

One English screenplay → 18 shot-level prompts → final cut.
• Seedance 2.0 + Omni Reference via @tapnow_ai
• @elevenlabs for voice + score
• @topazlabs for the 4k upscale
• @Prompt_Driven orchestrating the whole pipeline
@sisozo_ wrote in English. Pipeline did the rest

We just shipped the first programmatic-video use case for Prompt Driven at film scale.
UNWRITTEN: a 3-minute AI short film by @sisozo_ & @GregTanaka just made Top 5 Best Film at @soulscapefilm 2026 (out of 39 films).
Here's how we built it in 36 hours 🧵
Every shotwas rendered on @TapNow: Saloni's script drove the node-based workflow directly: same hero ref, same color directive inherited across all 18 shots. Programmable AI cinema.
AI Tool: #TapNow
#TapTV #Soulscape #TapTVArena
Behind The Scenes: the @TapNow node graph behind every UNWRITTEN shot. Saloni's English script drove this directly — same character ref + color directive inherited across all 18 shots. Programmable AI cinema.
AI Tool: TapNow
#TapTV #tapnow #Soulscape #TapTVArena

Watch the 3-minute film → youtu.be/rzdvt-qOysI
Open-source pipeline → github.com/promptdriven/pdd
Saloni handled the creative. I handled the technology.
@sisozo_ wrote a film I couldn't have built without her story.

The real unlock: treating the screenplay as the source of truth.
Color palette (cold blue → gold → golden hour) was ONE directive inherited across all shots in an act. Not 18 per-shot prompt tweaks.
You iterate on the script. The pipeline iterates on the prompts.
Hardest problem: character consistency across 18 shots from one hero reference.
1st pass: ~37% usable (model drifted to generic features).
2nd pass: ~100% after adding explicit eth/age/features to every prompt body + "NO TEXT" neg directives.
The ref inspiration, not a lock.
One English screenplay → 18 shot-level prompts → final cut.
• Seedance 2.0 + Omni Reference via @tapnow_ai
• @elevenlabs for voice + score
• @topazlabs for the 4k upscale
• @Prompt_Driven orchestrating the whole pipeline
@sisozo_ wrote in English. Pipeline did the rest