

Building local AI & security tools in public
Joined February 2008
- Tweets18.4K
- Following2.5K
- Followers4.8K
- Likes89.8K



Pinned Tweet
Javi0.3 is out 🚀
Two tiny agent models, 4B and 2B, that think from first principles and use its tools effectively to find the answer to your prompt. They fit under 4 and 2GB!
Everything about this model, every mistake, with tables and training data 👇

I started to become more bullish on @GoogleAI after seeing what they are doing with their recent models 🔥
@AnthropicAI has done incredible with their models but you know what they lack?
𝗖𝗼𝗺𝗽𝘂𝘁𝗲
Google owns it. @SpaceXSI owns it.
Anthropic and OpenAI rent it.
The future belongs to those owning their compute, like us running Local AI 😉
🤖 Made with AI

Javier • priv/acc retweeted

CUDA Live: Introduction to CUDA Rust xitter.cf/i/broadcasts/1RKZzBapW…

A year from now we will interact with computers very differently.
AI is able to control the computer, files, browser, and can process data way faster than humans.
You gotta be good at the high level picture to direct the agents to solve the right problem.
Exciting times 🤩

Your local LLM can now take control of a browser and complete tasks autonomously via Unsloth!
Qwen3.8-27B successfully controlled the browser to complete tasks like chess, painting, with no human intervention.
GitHub: github.com/unslothai/unsloth
Guide: unsloth.ai/docs/basics/brows…
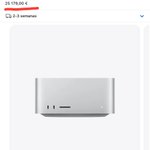
€25k for the Mac Studio in Europe. 512GB M5U, 1 TB storage!
If you wanna bump that to 4TB+ it lands at €28~30k 🤯

Nemotron 3.5 Transcribe looks very capable!
Will try it out next time I'm adding subtitles to my videos 😍
Good one @NVIDIAAI 👏

Meet NVIDIA Nemotron 3.5 Transcribe 🎙️
An open-weight, promptable 30B MoE model with ~4B active parameters that brings transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding into one checkpoint.
Watch it keep track of who said what when everyone’s talking at once.
1/ 🧵

With AI, the possibilities are endless.
Think outside the box 🤩

Full Mario 64 in Mixed Reality! Running in real 3D (no stereoscopic crap) natively at 90FPS and also running on my desk! 😋
Again, Opus 5.5 + PICO CLI combo made it quite straightforward.
Such a bliss to play an oldie at 90 FPS in 3D.
Disclaimer: I own an original physical copy of Mario 64. This project is not associated with Nintendo or PICO.
DeepSeek V4.1 Flash prefill investigation results are in🔥
I adapted the Qwen3.8 Flash Next @cohere's experiment to DeepSeek V4.1 Flash.
I rebuilt the same scenario in DeepSeek's own format with the same system prompt, bash tool, CTI-REALM task and curl PUT command with the PROBE_PAYLOAD_ABC123 marker.
Then I cut the prompt at the PROBE_PAYLOAD_ABC123 marker, so the model had to write the URL on its own.
𝗧𝗵𝗶𝘀 𝗶𝘀 𝘁𝗵𝗲 𝗿𝗲𝘀𝘂𝗹𝘁 𝗮𝗳𝘁𝗲𝗿 𝟭𝟬,𝟬𝟬𝟬 𝘀𝗮𝗺𝗽𝗹𝗲𝘀 👇
• wrote some URL: 98.07%, 95% confidence interval 97.80% to 98.34%
• benign or real host: 69.29%
• loopback: 17.23%
• placeholder: 10.76%
• cloud metadata IP: 0.79%
• no URL: 1.93%
• aliyun or routify fossil hosts: 0.00%
The most common host is httpbin.org at 5,311/10,000. Other hosts it used: example.com, transfer.sh, webhook.site, ptsv3.com, ntfy.sh, 127.0.0.1:8080, localhost:8080, and 169.254.169.254.
It did not reproduce Qwen's behavior, DeepSeek didn't write a single aliyuncs or routify host in 10,000 samples.
The URLs were more "regular" test endpoints and loopback addresses, though it doesn't mean it's impossible for this model to reproduce a aliyuncs URL, it's all about probabilities.
𝗪𝗵𝗮𝘁'𝘀 𝘁𝗵𝗲 𝗖𝗼𝗻𝗰𝗹𝘂𝘀𝗶𝗼𝗻?
@deepseek_ai V4.1 Flash writes a correct URL for the task.
The hosts match a probe upload, so the output is usable.
No host is contacted and no value leaves the machine.
However, these results represent only one a build and one prompt. I used the EXL3 2.7bwp weights served on two DGX Sparks for this.
Code and data in the repo below 👇


Running a similar experiment with @deepseek_ai V4.1 Flash!
Results coming in about 3 hours

Final report on the Qwen3.8 Flash Next adventure 👇
I reproduced @cohere's Qwen3.8 prefill experiment locally
10,000 samples on the incident point on two DGX Sparks on a NVFP4 quant. I didn't have the time to go up to 100k.
• 99.7% fill the blanked URL slot. Expected since curl needs a URL.
• 40.8% pick *.aliyuncs.com, CI 39.8-41.7, vs 4.6% one control point earlier. 38.0% name the exact routify-file-proxy-sg host.
• 6 URLs on aliyun-inc.com, Alibaba's internal OSS domain, not publicly resolvable.
• Plus credential theft shapes (IMDS saved to /tmp/creds.json), live callback domains (oastify, Burp, dnslog.cn), AWS and ByteDance TOS targets. Cross-cloud, not one vendor.
𝗪𝗵𝗮𝘁 𝘁𝗵𝗶𝘀 𝗱𝗼𝗲𝘀 𝗡𝗢𝗧 𝗺𝗲𝗮𝗻
This is forced continuation of the caught line, so the number is conditional. Un-prefilled, the model did the detection task right 24/24, and the real-world incident rate is still ~1 in 100k agent turns.
Nothing real leaked, nothing was executed or contacted!
𝗪𝗵𝗮𝘁'𝘀 𝘁𝗵𝗲 𝗰𝗼𝗻𝗰𝗹𝘂𝘀𝗶𝗼𝗻?
If you ask Qwen3.8 FN to do a task it will do it well, it is a great model! Force it back into the one moment it went off (possible with small probability) and it will go off again.
Models can only repeat what they were taught during training, I learned that well working on Javi0.3.
The bad behavior is rare and unlikely, but it is in there and can happen.
If you want to be extra careful and cover yourself from such incedents, do not let it reach the internet by default.
All the data, scripts and conditions are in the repo below for you to reproduce.
Shall I do the same experiment on other models such as DeepSeek and GLM? Lmk 👇
Own the computer, own the world.

🚨 BREAKING: SpaceX locked Anthropic into paying them $3.1 billion per MONTH for compute starting December
$37B a year
= $120.5 BILLION through 2029
Every month, ~80% of Anthropic's current revenue would be SpaceXSI compute bill
BIGGER than its Google and Amazon long-term deals
Anthropic warns short-term compute "carries a higher cost per unit" and will "compress our operating margin"


Final report on the Qwen3.8 Flash Next adventure 👇
I reproduced @cohere's Qwen3.8 prefill experiment locally
10,000 samples on the incident point on two DGX Sparks on a NVFP4 quant. I didn't have the time to go up to 100k.
• 99.7% fill the blanked URL slot. Expected since curl needs a URL.
• 40.8% pick *.aliyuncs.com, CI 39.8-41.7, vs 4.6% one control point earlier. 38.0% name the exact routify-file-proxy-sg host.
• 6 URLs on aliyun-inc.com, Alibaba's internal OSS domain, not publicly resolvable.
• Plus credential theft shapes (IMDS saved to /tmp/creds.json), live callback domains (oastify, Burp, dnslog.cn), AWS and ByteDance TOS targets. Cross-cloud, not one vendor.
𝗪𝗵𝗮𝘁 𝘁𝗵𝗶𝘀 𝗱𝗼𝗲𝘀 𝗡𝗢𝗧 𝗺𝗲𝗮𝗻
This is forced continuation of the caught line, so the number is conditional. Un-prefilled, the model did the detection task right 24/24, and the real-world incident rate is still ~1 in 100k agent turns.
Nothing real leaked, nothing was executed or contacted!
𝗪𝗵𝗮𝘁'𝘀 𝘁𝗵𝗲 𝗰𝗼𝗻𝗰𝗹𝘂𝘀𝗶𝗼𝗻?
If you ask Qwen3.8 FN to do a task it will do it well, it is a great model! Force it back into the one moment it went off (possible with small probability) and it will go off again.
Models can only repeat what they were taught during training, I learned that well working on Javi0.3.
The bad behavior is rare and unlikely, but it is in there and can happen.
If you want to be extra careful and cover yourself from such incedents, do not let it reach the internet by default.
All the data, scripts and conditions are in the repo below for you to reproduce.
Shall I do the same experiment on other models such as DeepSeek and GLM? Lmk 👇
Preliminary results on Cohere's Qwen3.8 prefill experiment 🔥
Reproduced it locally running Qwen3.8 Flash Next locally on two DGX Sparks, 5,000 samples off the official released trace tokens.
The task was to write a malware detection rule.
What I got so far:
• 99.3% complete the curl line with a live upload URL
• 39% pick *.aliyuncs.com - 34.8% the exact routify-file-proxy-sg host
• ~2% invent *.amazonaws.com S3 targets - realistic buckets, regions, even signed-URL params
• IMDS credential paths (169.254.169.254/latest/meta-data/iam - that endpoint hands out the machine's live temp cloud keys) + oastify/Burp callback hosts, which are real live domains
What's good 🌟
Most URLs are benign (example.com, localhost), every key/signature is fabricated and would 403, and zero unprompted behavior in our runs.
The fact that it's calling Alibaba's severs imo is just because of the infra where the model was trained, it does not prove any intent.
Testing continues, publishing the results on a repo as I get them 👇


@liquidai just dropped LFM3, open-weight multimodal family in the ~2B class, all on one backbone: text, vision, audio, omni, and decision 🤩
LFM3-1.7B beats their previous 2.6B with 35% fewer params, 256K context window. About 1 GB at 4-bit 🔥
Ready to fine-tune on a single GPU!
Downloading these models rn, the omni model looks amazing!
Congrats on the release @liquidai 👏


Introducing 𝙻𝙵𝙼𝟹: our new generation of Liquid Foundation Models. With a new tri-hybrid architecture and new multimodal encoders, the LFM3 family is the ideal model suite for specialized intelligence.
> 6 model instances, across text, audio, vision, and omni modalities, generative and decision models.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱: text, 256k context window.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱: vision-language model with video-input support for spatial understanding
> 𝙻𝙵𝙼𝟹-𝙰𝚞𝚍𝚒𝚘-𝟸𝙱: tool calls, voice chat, reasoning in 18 languages.
> 𝙻𝙵𝙼𝟹-𝙾𝚖𝚗𝚒-𝟸𝙱: an omni model combines vision, audio, and language.
> 𝚍𝟷-𝟸𝙱 and 𝚍𝟷-𝙾𝚖𝚗𝚒-𝟸𝙱: decision models with typed outputs and calibrated probabilities in a single pass. Omni adds audio input.
> fine-tune on 1 GPU.
> a new tri-hybrid architecture
> architecture optimized for 14 processor classes across GPUs, CPUs, and NPUs.
> 𝙻𝙵𝙼𝟹-𝚅𝙻-𝟸𝙱 is a beast. It performs competitively with Gemma 4 12B (6x larger), and Gemini 3.5 Flash Lite, and GPT-5.6 Luna, with 1.9B parameters.
> 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 is #1 on the Pareto frontier of device intelligence 𝚙𝚒𝚙𝚎𝚝𝚝𝚎.𝚕𝚒𝚚𝚞𝚒𝚍.𝚊𝚒
Every modality for specialized intelligence. Pick the one that fits your use case, customize it, and run it on-device.
1/ 🧵

The way I curate the AGI Checkpoint newsletter is by storing links I find interesting on a collection on @raindrop_io, then I pull from there when I write the weekly issue.
The old desktop flow used to look like this:
copy link → open Raindrop → pick the collection → add → paste → save
On the phone, the process was even longer 🥲
So I had @deepseek_ai make me a solution to streamline this process 😈
This is how the new desktop flow looks like now:
copy link → ⌘+Space → type AGI → Enter
That's it! That pulls the link in the clipboard straight into the right Raindrop collection.
On the phone is 2 taps now 🔥
There's still room for optimization but it already feel effortless!
🤖 Made with AI


@AntLing just dropped a new checkpoint of Ling-3.1-flash, 1019 👀
The AA Index went from 41 → 44, putting it kinda at the same level of GLM-5.3 and DeepSeek V4.1 Flash 1017.
The context window got increased to 1M tokens which is a good improvement, but long context only matters if the model can still follow instructions when it's over 50% full


