

ai eng & videos | databricks, princeton | @chrissyykat
sf
Joined May 2017
- Tweets760
- Following834
- Followers10K
- Likes4.9K





2021: buy from alibaba, sell on shopify
2026: buy data from your local business, sell to frontier labs
the dropshippers have evolved


the smartest model is still a brilliant new hire who gets their memory wiped every morning
grateful to have contributed to the latest databricks memory work, sharing how the research + eng team built a memory system and overnight dreaming distillation pipeline to make agents actually useful for enterprises in production

Introducing MemCurrent, a persistent memory architecture designed to help production agents stop starting from zero.
MemCurrent combines episodic memory with derived memory across three access patterns:
• Plugins to log and load context automatically
• Tools the agent calls on demand
• An offline “dreaming” pipeline that consolidates memory in the background
Agents carry forward user preferences, prior corrections, metric definitions and successful workflows instead of rediscovering them every session.
On our internal benchmark built from real enterprise data, MemCurrent triples the agent's pass rate while using 31% fewer tokens and running 26% faster. It's built into Agent Bricks' Memory offering and already powers memory in Genie.
Read the research: databricks.com/blog/memcurre…
having spent some time in text-to-3d years ago, the biggest concern is that there has always been the ability to create *a* 3d model, but upon closer inspection systems always seemed to miss the bar when it comes to real world use cases (gaming assets, CAD etc) so when trying to hand it off to real modelers/CAD designers they would always end up scrapping it entirely and start from scratch
so cool to see a model solving this from first principles, excited for the future of spatial intelligence


new unsaturated benchmark?


We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

jenny ☀️ retweeted

Fable 5.1 dropped this week, GPT-6 Astra dropped today, and everyone’s busy benchmarking both.
The problem is managing the sprawl: accounts split across browsers, CLI agents on remote boxes, local models running in background tabs.
We built Choruz to pull all of that into one unified workspace.
if your startup or someone you know needs animated feature demo videos with quick turnaround (1 day), message me!
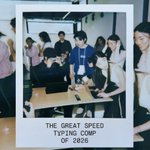
over 100 people came to san francisco’s first-ever speed typing competition in the search of the fastest typist in the city. all the winners were startup founders. what happened? 👩🏼💻👨🏻💻
with @tomo @capydotai @Jackyhuang @chrissyykat


All the winners were startup founders 🤔
Top 3:
1. John Q @johnlqian
WPM: 169
Blindfolded: 78
Twin: 44
2. Alex H hult.tech
WPM: 151
Blindfolded: 84
Twin: 44
3. Arman K @ksw_arman
WPM: 154
Blindfolded: 88
Twin: 32
Top 10 based on WPM:
1. 179 Kevin L @kliu10
2. 173 Jay J simplifyinterviews
3. 169 John Q @johnlqian
4. 161 Anntaylor
5. 156 Ben S
6. 154 Arman K @ksw_arman
7. 151 Alex H hult.tech
8. 148 Kevin L @linguinelabs
9. 142 Wonyoung D
10. 140 Alina


born too early to grow up with agi
born too late for the dot com bubble
born just in time to become a vision benchmark

Yay, finally! Introducing Vision Banana🍌 from @GoogleDeepMind, our unified model that outperforms SoTA specialist models on various vision tasks!
By treating 2D/3D vision tasks as image generation, we unlock a new foundation for CV.
Project page: vision-banana.github.io
(1/5)
jenny ☀️ retweeted

salon des refusés chapter iii
@akothari
@Jackyhuang
@_samirism
@fareehasala
@HugoAmsellem
@_kentw
@antimimetics
@joetey_
@rachelsupark
@Reshusaur
@liamesp
@brndnwll
@jennsun
@chrissyykat
@barofclo


