





Jon Perl retweeted

It's 2026 and you're still loading some TestFlight build on your personal device and calling it tested.
Get serious about testing iOS and Android apps. QA Wolf's agent now writes, runs, and maintains deterministic E2E tests in open-source Appium.
qawolf.com/changelog/mobile-…
Jon Perl retweeted

I really enjoyed building this one at QA Wolf!
Instead of explaining to an agent what you want to test, you can just show it in the browser. The agent can then take over, clean things up, and turn it into a Playwright test.
qawolf.com/blog/how-qa-wolf-…

Jon Perl retweeted

Today, our team is excited to announce @InspiredCap Fund IV, $450M in new capital to back early-stage founders.
There has never been a moment in history when more is possible. It takes just one person with exceptional ambition to take on the world’s problems and change billions of lives for the better.
Jon Perl retweeted

A lot of what we do at QA Wolf is designing agentic systems to do what humans do naturally. Humans are great at sorting test failures by a root cause, but slow. Agents are fast but need explicit rules to work together. Check it out: qawolf.com/blog/how-qa-wolf-…

Jon Perl retweeted
AI investigation is now live for everyone.
The moment a test fails, an agent jumps in. Broken tests are updated, bugs are filed, flakes are re-run.
QA cycles run 6.5x faster because you're not waiting for the whole suite before triaging failures.
qawolf.com/changelog/ai-inve…

Jon Perl retweeted

how it feels to interact with my human family after another 14 hour day of interacting with Claude

Jon Perl retweeted
'twas no small feat building the infrastructure for Windows testing — check it out 👇


Jon Perl retweeted
A new model launches every other week. GPT-6.1 Sol, Gemini 4 Argon, Claude Opus 5.5, each new release beating the last on some benchmark. But on its own, even the smartest model can only tell you how to fix a broken test. To actually fix it, it needs somewhere to work: your code, a browser to open your app, and a way to run the test and see it pass, that’s the sandbox.
QA Wolf AI’s is warm in milliseconds, with a real file system, a git clone of your test suite and a live browser you can watch. When the task is big, it spins up 50 more sandboxes, each with its own browser and branch.
Here’s how we built it: qawolf.com/blog/every-ai-age…

Jon Perl retweeted
Welcome to self-driving QA 🚗
Your agent builds a feature
⬇️
Calls QA Wolf to test it
⬇️
QA Wolf bulk automates Playwright & Appium tests
⬇️
Tests run in parallel
⬇️
Verified bugs are shared with your agent
⬇️
Agent fixes
⬇️
Re-test & ship
Start here: docs.qawolf.com/

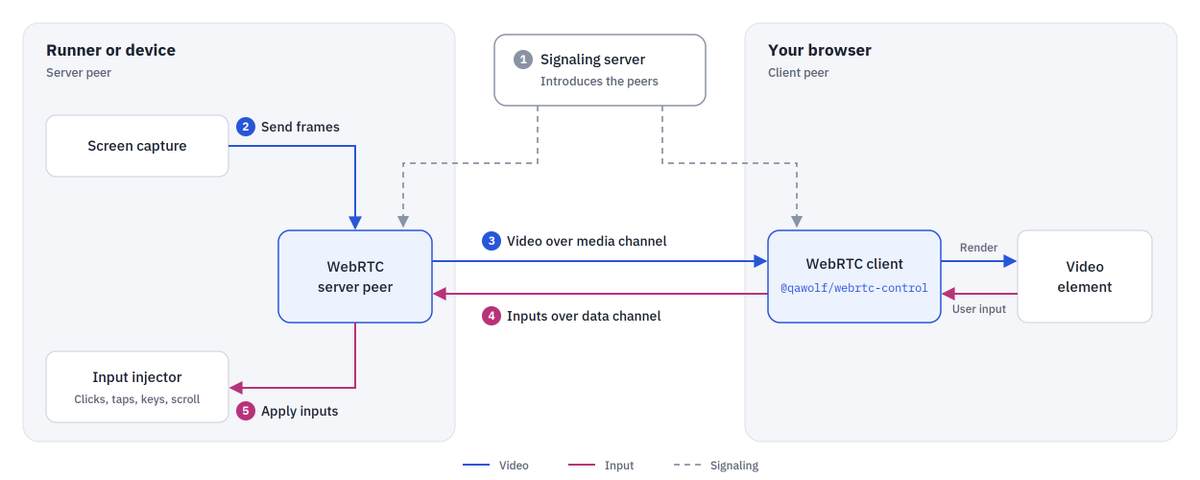
RT @_theonly1me: It’s here! the QA Wolf MCP server is live 🎉
You focus on building features. Claude and Codex can request test coverage fr…
This quoted post is unavailable.
Jon Perl retweeted
Still figuring out what all we can do with Jev. One of the first places we’re putting it to work: giving Playwright tests a little judgment.
ai.expect checks meaning. ai.act can take a different route through the UI. The rest of the test stays deterministic.
Wrote it up qawolf.com/blog/semantic-ass…

Jon Perl retweeted
One good use case for Jev from @typesafeai for e2e testing is that agent testing is now cheap at scale.
Playwright does most of the heavy lifting, and Jev verifies that the agent did the right thing.

Jon Perl retweeted
Your test suite is out of date the moment you ship a new feature. 📉
Before AI coding tools, a focused team *might* have kept up. Now it’s impossible. Our product-mapping AI explores your app, spots coverage gaps, and outlines new tests as you ship.
qawolf.com/changelog/mapping…

Jon Perl retweeted
Graph engineering is trending but its underlying patterns are not new.
More engineers are just using them because they’re trying to solve for coding agents’ uneven output.
In our new post, we share some common patterns used in agent graphs.
qawolf.com/blog/how-to-imple…
