

Friend of all dogs. 14+ years experience selling Software & SaaS, Web Developer. Previous lead at Instacart. Former Congressional Staffer. Big fan of sandwiches
Rochester, NY
Joined March 2011
- Tweets4.8K
- Following578
- Followers426
- Likes2.1K



As I am sitting here, I just heard a computer beep. But it did not come from the direction of any of the 4 I'm looking at.
That means there may be a fifth one here I forgot about. Because I know it's not the 6th one, which is bricked, or the 7th one--the one I am typing on.
Kevan MacGee retweeted

Aaron Ross helped create the outbound process that helped add $100 million in recurring revenue at Salesforce.
My favorites from his outbound playbook:

Amazon says I "maintain stead condiment replenishment" which is a compliment of the highest order in my book.
It knows I prefer @FranksRedHot

Complaining that when @thsottiaux does a reset, it messes up your schedule in your token scheduling endeavor has strong, "my steak is too juicy, my lobster too buttery" vibes.
I don't need a minimal template that's an update to Astro's basic blog, but I'm building a template that is an update to Astro's basic blog.

Luna Max was my daily driver, but with 61. Sol Light has taken its place.
As per my usual comments, it's great for front end work and is barely moving the needle on usage.
People don't even go get their own food. They pay twice the price for it to arrive on their doorstep.
There will always be plenty of people to write the right software for.

I don't have a problem with the date shift when you use a banked reset.
I'm getting free usage, I don't expect every single aspect of a gift to be of my design.
I've been putting Mimo 2.6 Pro through its paces.
It is definitely more expensive than 2.5 pro but is also better. Still figuring out how much better bit it seems considerable.

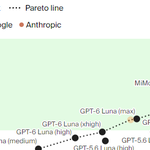
The Intelligence Index vs Cost per Task Pareto frontier shifted this week with the releases of MiMo-V2.6-Pro, Claude Opus 5.5, GPT-6 Luna, and GPT-6 Sol
Together they have established eleven new points on the Pareto frontier (driven by different reasoning efforts): five from GPT-6 Luna, one each from MiMo-V2.6-Pro and GPT-6 Sol, and four from Claude Opus 5.5.
GPT-6 Luna (max) scores 37 at $0.068 per task, MiMo-V2.6-Pro scores 46 at $0.13, GPT-6 Sol (max) scores 48 at $1.06, and Claude Opus 5.5 (max with fallback) is the new highest-scoring model at 58 at $5.98.
Exactly the wrong reason not to build something.
If others have built it, that's market validation.
You now have competitors to study and to find weakness from.
You have been handed the roadmap of what your differentiating features will be.


I've been using Mimo 2.6 Pro since yesterday and while it is capable, it *definitely* uses more tokens than 2.5 Pro did.
It's extremely verbose in its thinking. Tasks are more expensive than 2.5 Pro, but of course are better quality.
Aaaannnd I missed the reset. It expired.
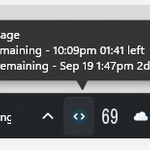
I made a minimal Codex usage moniter last week, I'm adding banked reset expiration visibility to it now.
I hit my 5 hour limit right after it started.
It's still going 16 mins later at 0%. First time exploiting that to be honsest.

Once every 18 months I log into Pinterest, play with it & say, "I forgot how amazing this is. This is great, a gamechanger! I will use this every day from now on!" Then I never log in again until 18 months later.

Okay, wow, yeah. I made a Codex usage indicator for the systray in Windows and Astra Light has drained my usage for sure.
No worries though, it looks great! (First draft, very minimal.)
