
Building agents @TechAtBloomberg; Previously Postdoc @jhuclsp JHU; PhD @GeorgiaTech
Joined September 2015
- Tweets81
- Following253
- Followers190
- Likes321




Fan Bai retweeted

Accepted to #NeurIPS2026 #NeurIPS 🥳 We've added more experiments and new findings; stay tuned for the camera-ready version.

Multimodal LLMs can read text in images, but why do they often perform worse than when the same text is given as tokens? Our work studies the modality gap of models perceiving text as pixels and shows how to close it.
📄 arxiv.org/abs/2603.09095
🧵👇 #NLProc #LLM #ComputerVision

Fan Bai retweeted

When New Information Conflicts with What AI Knows
LLMs often continue to rely on information learned during training, even when instructed to use new information.
Coverage of our ACL 2026 paper
clsp.jhu.edu/2026/07/27/when…
aclanthology.org/2026.findin…
@KaiserWhoLearns @loadingfan

Fan Bai retweeted

🔥FIRE-Bench got into #ICML2026🎉
Our take on #AutoResearch: target real human-verified scientific insights, not engineered ML models
Stay tuned for two follow-ups:
1️⃣ FIRE-Bench scaled into the "SWE-Bench" of research agents
2️⃣ Paper2Bench: any paper → a verifiable benchmark


🤖🔬 Can AI actually do science end-to-end?
🧠📈 And how would we know when it matches, or surpasses, humans?
⚡🧪 AI is rapidly automating scientific discovery, but benchmarking full-cycle discovery, from 💡 ideation → 🧑💻 execution → 📊 conclusions, remains unsolved:
🧐🧐🧐
❌🛠️ Open-ended discovery → manual validation (costly, unscalable)
❌📏 Metric-driven benchmarks (e.g., MLE-Bench) → convenient but narrow (is higher accuracy really enough?)
❌🤖⚖️ LLM-as-judge → useful, but fundamentally risky if used alone
🔥🚀 Introducing FIRE-Bench🔥: Fullcycle Insight Rediscovery Evaluation
👉🌐 firebench.github.io
📚✨ A benchmark that turns fresh, human-verified insights from recent 🏆 NeurIPS / ICLR / ICML papers into masked, end-to-end discovery challenges 🧩
🌍🔐 Constrained open-ended discovery–backed by ground truth.
📌 Key takeaways:
1⃣ 📖🧱 Reference-based evaluation still matters: constrained LLM judging helps, but human-grounded references remain essential until agents can consistently match human conclusions
2⃣ 🏆🧠 Expert-validated ground truth: all tasks come from recent NeurIPS / ICLR / ICML papers, with contamination carefully controlled
3⃣ 🔁🎭 Rediscovery, not reproduction: original 🧪 methods, 📊 experiments, 💻 implementations, and 📈 analyses are fully masked to create real discovery challenges
🔑 Key empirical findings:
💡 The "Science Gap" is Real: Even the best setup (Claude Code + Sonnet-4) caps out at an F1 score of 46.7. On hard tasks, agents struggle to break 30
💡 Success is a "Lottery": Performance has incredibly high variance. Reliability is a major unsolved issue.
💡 Coding is no longer the bottleneck; high-level reasoning and analysis are: ~74% of errors stem from flawed planning, not coding
⚙️ How it works:
🔹 Research-Problem Trees: We parse papers into trees (from broad roots to concrete leaves). This allows us to select intermediate nodes that perfectly balance open-ended exploration with verifiable ground truth.
🔹 Claim-Level Evaluation: We match AI conclusions against human conclusions using granular claim decomposition (F1 score).
🔹 Creativity Check: We score false positives to see if agents are finding novel truths (Spoiler🚨: they aren’t creative yet).
🔹 New Diagnostic Taxonomy: failures traced across four stages: 🧠 Planning → 🛠️ Implementation → ▶️ Execution → 🧾 Conclusion
🔹 Additional Analyses: cost efficiency, contamination checks, and more.
👀 The Future:
🚀 Live-FIRE-Bench: a live, continuously updated FIRE-Bench to track real-time progress on the latest research (Newest LLMs should be benchmarked with the newest research)
🚀 Stronger scaffolding (search + planning + coding) 🧠🧰 and converting FIRE-Bench into interactive environments for training research agents
🚀 Toward real creativity: We want better systems that can produce genuinely novel conclusions toward creativity 🎨⏳
🚀 Better systems 🧠✨ and better benchmarks 📏 must co-evolve 🔄 over time
📜🎥 Paper, video, demo, and research trees:
👉🌐 firebench.github.io
#AI 🤖 #MachineLearning 📚 #AI4Science 🔬 #LLMs 🧠 #Research 🧪 #AgenticAI 🚀 #FireBench 🔥
Excited to share our latest work on the modality gap in multimodal LLMs.
Imagine an agent interacting with the real world as humans do. The text it encounters on signs, documents, or screens appears as pixels, not tokens. Yet MLLMs often perform worse when reading the same text from images. We study this gap and show how to close it.
Multimodal LLMs can read text in images, but why do they often perform worse than when the same text is given as tokens? Our work studies the modality gap of models perceiving text as pixels and shows how to close it.
📄 arxiv.org/abs/2603.09095
🧵👇 #NLProc #LLM #ComputerVision
Fan Bai retweeted
Love this direction from @karpathy. Autonomous agents iterating on training runs feel like a modern renaissance of AutoML, except now the search space includes research decisions themselves: architectures, training setups, analysis pipelines, etc.
But if “autoresearch” becomes a thing, the obvious question is: how do we measure progress in “autoresearch”?
- Paper generation, single metrics, LLM-as-judge, or traditional reproducibility research?
That’s exactly the motivation behind FIRE-Bench (Full-cycle Insight Rediscovery Evaluation): xitter.cf/zhenwang9102/status/20…
Instead of optimizing a single metric or judging papers, FIRE-Bench evaluates whether agents can rediscover real scientific insights from recent NeurIPS / ICLR / ICML papers:
- Turn papers into research-problem trees and select a proper research problem to ask (neither too broad nor too narrow)
- We mask the original methods, experiments, and conclusions
- Ask agents to go from idea → implementation → experiments → conclusions
- Then score them via claim-level matching against expert-validated ground truth
What we found so far:
- Even the strongest agents struggle (best F1 ≈ 46.7)
- Performance is extremely high variance (“research lottery”)
- Planning and reasoning, not coding, is the main bottleneck
If autoresearch systems like this keep improving, benchmarks must evolve alongside them.
Better research agents 🤖 need better ways to measure real discovery 🔬
FIRE-Bench: firebench.github.io

I packaged up the "autoresearch" project into a new self-contained minimal repo if people would like to play over the weekend. It's basically nanochat LLM training core stripped down to a single-GPU, one file version of ~630 lines of code, then:
- the human iterates on the prompt (.md)
- the AI agent iterates on the training code (.py)
The goal is to engineer your agents to make the fastest research progress indefinitely and without any of your own involvement. In the image, every dot is a complete LLM training run that lasts exactly 5 minutes. The agent works in an autonomous loop on a git feature branch and accumulates git commits to the training script as it finds better settings (of lower validation loss by the end) of the neural network architecture, the optimizer, all the hyperparameters, etc. You can imagine comparing the research progress of different prompts, different agents, etc.
github.com/karpathy/autorese…
Part code, part sci-fi, and a pinch of psychosis :)

Really excited to co-lead this work. 🚀
Agentic AI for scientific discovery is moving fast — but it’s not there yet.
Across FIRE-Bench🔥, even SOTA agents (e.g., Claude Code and Codex) stay <50 F1, struggling with research planning and drawing valid conclusions from experiments. More strikingly, performance variance across runs is huge, highlighting how brittle current agents are on long-horizon, full-cycle research tasks.
Lots of room to push forward. 🔬🤖
🤖🔬 Can AI actually do science end-to-end?
🧠📈 And how would we know when it matches, or surpasses, humans?
⚡🧪 AI is rapidly automating scientific discovery, but benchmarking full-cycle discovery, from 💡 ideation → 🧑💻 execution → 📊 conclusions, remains unsolved:
🧐🧐🧐
❌🛠️ Open-ended discovery → manual validation (costly, unscalable)
❌📏 Metric-driven benchmarks (e.g., MLE-Bench) → convenient but narrow (is higher accuracy really enough?)
❌🤖⚖️ LLM-as-judge → useful, but fundamentally risky if used alone
🔥🚀 Introducing FIRE-Bench🔥: Fullcycle Insight Rediscovery Evaluation
👉🌐 firebench.github.io
📚✨ A benchmark that turns fresh, human-verified insights from recent 🏆 NeurIPS / ICLR / ICML papers into masked, end-to-end discovery challenges 🧩
🌍🔐 Constrained open-ended discovery–backed by ground truth.
📌 Key takeaways:
1⃣ 📖🧱 Reference-based evaluation still matters: constrained LLM judging helps, but human-grounded references remain essential until agents can consistently match human conclusions
2⃣ 🏆🧠 Expert-validated ground truth: all tasks come from recent NeurIPS / ICLR / ICML papers, with contamination carefully controlled
3⃣ 🔁🎭 Rediscovery, not reproduction: original 🧪 methods, 📊 experiments, 💻 implementations, and 📈 analyses are fully masked to create real discovery challenges
🔑 Key empirical findings:
💡 The "Science Gap" is Real: Even the best setup (Claude Code + Sonnet-4) caps out at an F1 score of 46.7. On hard tasks, agents struggle to break 30
💡 Success is a "Lottery": Performance has incredibly high variance. Reliability is a major unsolved issue.
💡 Coding is no longer the bottleneck; high-level reasoning and analysis are: ~74% of errors stem from flawed planning, not coding
⚙️ How it works:
🔹 Research-Problem Trees: We parse papers into trees (from broad roots to concrete leaves). This allows us to select intermediate nodes that perfectly balance open-ended exploration with verifiable ground truth.
🔹 Claim-Level Evaluation: We match AI conclusions against human conclusions using granular claim decomposition (F1 score).
🔹 Creativity Check: We score false positives to see if agents are finding novel truths (Spoiler🚨: they aren’t creative yet).
🔹 New Diagnostic Taxonomy: failures traced across four stages: 🧠 Planning → 🛠️ Implementation → ▶️ Execution → 🧾 Conclusion
🔹 Additional Analyses: cost efficiency, contamination checks, and more.
👀 The Future:
🚀 Live-FIRE-Bench: a live, continuously updated FIRE-Bench to track real-time progress on the latest research (Newest LLMs should be benchmarked with the newest research)
🚀 Stronger scaffolding (search + planning + coding) 🧠🧰 and converting FIRE-Bench into interactive environments for training research agents
🚀 Toward real creativity: We want better systems that can produce genuinely novel conclusions toward creativity 🎨⏳
🚀 Better systems 🧠✨ and better benchmarks 📏 must co-evolve 🔄 over time
📜🎥 Paper, video, demo, and research trees:
👉🌐 firebench.github.io
#AI 🤖 #MachineLearning 📚 #AI4Science 🔬 #LLMs 🧠 #Research 🧪 #AgenticAI 🚀 #FireBench 🔥
Please check out 🦌 Paper + Code for more details!
📄 arxiv.org/pdf/2505.23722v2📷
💻 github.com/bflashcp3f/deer📷
Even vs strong fine-tuned models like GoLLIE-34B, DEER (with GPT-4o) is competitive — all without training 💪
Training-free, label-aware, and robust.
LLMs can do NER — they just need better demonstrations.
8/8

📊 On 5 datasets × 4 LLMs:
✅ DEER consistently beats all ICL baselines.
✅ Error reflection further boosts performance.
✅ DEER handles unseen entities better than KATE — showing real generalization.
7/8


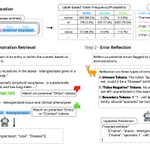
Here’s how it works ⚙️
1️⃣ Split training tokens into Entity, Context, and Other.
2️⃣ Compute label-based token weights.
3️⃣ Retrieve demos focusing on Entity and Context tokens via weighted token embeddings.
4️⃣ Apply error reflection to refine predictions at token level.
→ A full ICL pipeline tailored for NER.
6/8

We propose DEER 🦌 — Data-statistics-grounded namEd Entity Recognition.
We guide retrieval with label-aware token statistics, letting LLMs focus on the most informative tokens for entity recognition.
5/8
We found two key flaws in KATE:
1️⃣ Granularity mismatch: retrieves full sentences, but NER needs token/span-level cues.
2️⃣ Task-agnostic design: ignores entity-centric structure — no focus on entity patterns.
4/8
We ran a sanity check 🔍
For test entities that also exist in the training data — how often do their counterparts get retrieved as demos?
❗Result: many overlapping entities are missing (~40% on OntoNotes).
→ Evidence that ICL retrieval often ignores crucial token-level signals.
3/8

Most ICL methods (e.g., KATE) retrieve demonstrations by sentence-level similarity.
But for NER, this leads to a big gap vs fine-tuning methods.
So, we asked:
🧩 Is the limitation from the LLM itself, or from retrieval?
2/8

🤔 LLMs can ace Olympiad math, yet struggle with something as “simple” as NER — even with in-context learning (ICL)?
💡 Our #EMNLP2025 paper answers why:
“LLMs are Better Than You Think: Label-Guided In-Context Learning for Named Entity Recognition.” @mdredze @jhuclsp
👉 TL;DR: The issue isn’t the LLM — it’s how we pick demonstrations.
📄 arxiv.org/pdf/2505.23722v2
1/8

Fan Bai retweeted

Can LLM-simulated users replace expensive human evaluation for multi-turn conversations? Short answer: yes, if you model the user right.
With our SimulatorArena, we find that detailed user profiles (knowledge + message style) improve alignment with real human evaluation by 26% at <3% the cost.
#EMNLP2025 [1/6] 🧵

Fan Bai retweeted
What happens when an LLM is asked to use information that contradicts its knowledge? We explore knowledge conflict in a new preprint📑
TLDR: Performance drops, and this could affect the overall performance of LLMs in model-based evaluation.📑🧵⬇️ 1/8
#NLProc #LLM #AIResearch

Please checkout our paper and code for more details!
Paper: arxiv.org/pdf/2412.04573
Code: github.com/bflashcp3f/synthe…