

Organizing human intelligence to power the AI economy.
San Francisco
Joined April 2021
- Tweets458
- Following31
- Followers25.8K
- Likes839





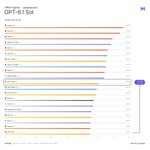
Mercor partnered with @Reflection_ai on Beam's training and evaluation.
Beam scores 48.8% Pass@1 on APEX-Agents, #1 among US open-weight models and closely trailing Chinese open models such as GLM-5.3-Flash (52.8%).
On APEX-Agents, which measures long-horizon, multistep tasks in professional services, Beam scores a 15-point lead among US open-weight models.
Beam: 48.8%
Muse Spark Open: 33.4%
Nemotron 3.5 Super VL: 29.5%
Nemotron 3 Ultra: 22.7%
It trails Qwen 3.8-Max by 14.5 points and lands within the confidence interval of GLM-5.3-Flash, trailing by 4.0 points.
Qwen 3.8-Max: 63.3%
MiMo-V2.6-Flash RL: 57.4%
GLM-5.3-Flash: 52.8%
Beam: 48.8%
Kimi K3: 47.8%
Qwen 3.8-27B: 47.5%
GLM-5.2: 45.2%
Compared with GLM-5.3-Flash on APEX-Agents domains, it leads on management consulting by 1.5 points. It trails GLM-5.3-Flash by 11.8 points on corporate law, and investment banking by 1.6 points.
Congratulations to the Reflection team. We’re excited for future collaboration together advancing the US open source frontier.
See full leaderboard: mercor.com/apex/apex-agents-…

We’ve paid out $50M+ to businesses for their data. Now we’re paying for introductions too.
Refer a company to Mercor and earn up to $100K when they partner with us.
Refer here: bit.ly/4sk28EA

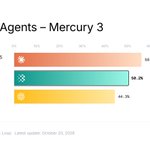
Mercury 3, @_inception_ai's diffusion LLM, debuts on the APEX leaderboards.
50.2% Pass@1 on APEX-Agents (#30 of 59)
43.1% Pass@1 on APEX-SWE (#31 of 62)
Inception positions Mercury 3 against speed-optimized frontier models.
On APEX-Agents it lands between GPT-6 Luna and Haiku 5.5, and on coding it trails Haiku 5.5 by 12 points.
Across APEX-Agents domains (mean score):
Corporate law: 78.4%
Management consulting: 57.5%
Investment banking: 51.4%
It is cost pareto optimal on APEX-Agents. An average APEX-Agents task costs about 6 cents at Inception's list price, and about 3 cents at the launch discount, helped by heavy prompt caching.
Congratulations to the Inception team on showing a diffusion model can hold its own on long-horizon professional work.
See full leaderboard: mercor.com/apex/apex-agents-…

Last week, Mercor Research economist @aden_barton joined @MTSlive to discuss our latest study comparing frontier AI models with licensed accountants on real-world accounting tasks.
18 months ago, the best models performed below the average accountant. Today, models are faster and more accurate than every accountant in our study.
Aden discussed what this progress means for the accounting profession, and why performing well on individual tasks is different from doing an entire job.
Watch the full conversation. youtube.com/watch?v=9JcfR1Lb…

Mercor retweeted

"The entire way that humans contribute to the economy is going to move.”
@mercor Co-founder & CEO @BrendanFoody explains what he believes will replace repetitive human work.
Mercor retweeted

The next major breakthroughs in AI will require us to create entirely new sources of training data.
Scientific research is an example. Most of what we know about experiments comes from published papers, which capture only a fraction of the work scientists do.
@LiamFedus is building @periodiclabs to change that, with physical labs that generate the experimental data needed to train AI scientists.
More from our conversation on The Frontier ⬇️
Mercor retweeted

"90% of American working hours are spent on tasks with little or no coverage from existing benchmarks."
Building great benchmarks is extremely high leverage to making AI more economically valuable. Can't manage what you don't measure.

Mercor Research mapped AI benchmarks to actual US jobs.
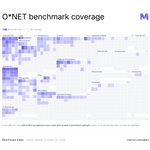
Only 208 of 923 occupations in the US economy are represented by existing AI benchmarks. 90% of hours worked in the US aren't covered well by a relevant AI benchmark.
Today, we’re releasing the 𝗕𝗲𝗻𝗰𝗵𝗺𝗮𝗿𝗸 𝗠𝗮𝗽 𝗼𝗳 𝘁𝗵𝗲 𝗨𝗦 𝗘𝗰𝗼𝗻𝗼𝗺𝘆, an interactive breakdown of which economic tasks are covered by AI benchmarks.
Benchmarks are how we measure AI’s progress and anticipate its impact on real work. They’re crucial to understand which jobs AI can automate, where the biggest gaps are, and how those capabilities are changing over time.
The Benchmark Map is our first step toward building a resource that makes it easier to answer: 𝘋𝘰𝘦𝘴 𝘵𝘩𝘪𝘴 𝘈𝘐 𝘮𝘰𝘥𝘦𝘭 𝘸𝘰𝘳𝘬 𝘧𝘰𝘳 𝘮𝘺 𝘰𝘤𝘤𝘶𝘱𝘢𝘵𝘪𝘰𝘯?
Explore it here: mercor.com/research/labor-in…

Congratulations to @NVIDIAAI for launching Nemotron 3.5 Super VL.
We worked with our partners @tryRamp, @Harvey, and @Cognition along with the NVIDIA team to post-train and improve the model’s performance using targeted datasets from our APEX benchmarks.
We tested the post-trained Nemotron models on legal, software engineering, and accounting tasks it had never seen.
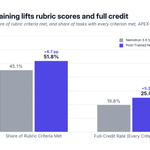
The post-trained model improved across all three professional domains.
Read the full results: mercor.com/blog/mercor-nvidi…

On the APEX-Accounting benchmark, mean rubric score rose from 34.6% to 41.9% (+7.3 points). Tasks scoring zero fell from 19% to 13%.
The post-trained model began by reviewing all available files before starting work (+38 points on planning behavior).
It also opened significantly more source records per task, from 8.5 to 12.

The results show how a relatively small amount of expert-built training data can improve an open model’s performance on professional work.
Open models plus realistic benchmarks and targeted training data create a viable path to domain-specific agents.
Congrats to @NVIDIAAI on the Nemotron 3.5 Super VL launch. And to @Harvey, @Cognition, and @tryRamp for partnering with us on this work.
Full blog here: mercor.com/blog/mercor-nvidi…
Mercor retweeted
The barrier to automating everything in the economy is that we need to build RL environments across every industry, job, and task
Mercor Research mapped AI benchmarks to actual US jobs.
Only 208 of 923 occupations in the US economy are represented by existing AI benchmarks. 90% of hours worked in the US aren't covered well by a relevant AI benchmark.
Today, we’re releasing the 𝗕𝗲𝗻𝗰𝗵𝗺𝗮𝗿𝗸 𝗠𝗮𝗽 𝗼𝗳 𝘁𝗵𝗲 𝗨𝗦 𝗘𝗰𝗼𝗻𝗼𝗺𝘆, an interactive breakdown of which economic tasks are covered by AI benchmarks.
Benchmarks are how we measure AI’s progress and anticipate its impact on real work. They’re crucial to understand which jobs AI can automate, where the biggest gaps are, and how those capabilities are changing over time.
The Benchmark Map is our first step toward building a resource that makes it easier to answer: 𝘋𝘰𝘦𝘴 𝘵𝘩𝘪𝘴 𝘈𝘐 𝘮𝘰𝘥𝘦𝘭 𝘸𝘰𝘳𝘬 𝘧𝘰𝘳 𝘮𝘺 𝘰𝘤𝘤𝘶𝘱𝘢𝘵𝘪𝘰𝘯?
Explore it here: mercor.com/research/labor-in…
Mercor retweeted
1/ The most important products usually look much more obvious in retrospect.
OpenAI had GPT-4 internally and was still debating what to build around it. @LiamFedus was there for the decision that eventually became ChatGPT.
We talked about that period, what changed once ChatGPT launched, and what he’s building now at Periodic on The Frontier.
Full episode below.
Mercor retweeted

soon all progress will be data bottlenecked, not intelligence bottlenecked. bio? data bottlenecked. astronomy? data bottlenecked. data all the way down
Mercor retweeted
1/ ChatGPT had the internet. AI for science has no equivalent.
@LiamFedus helped create ChatGPT and went on to lead post-training at OpenAI. Now he’s building Periodic Labs because better models alone won’t get us to an AI scientist.
We talked about why Periodic is building physical labs and what Liam learned from being inside OpenAI as ChatGPT took off on today's episode of The Frontier.
Mercor retweeted
Mercor is building a world-class research team.
As the leading AI data provider, we are uniquely positioned to combine benchmarks, data production, model training, and economics research to advance model productivity.
We are committed to sharing our findings with the world. DM me if this sounds exciting.
mercor.com/blog/why-mercor-i…

Introducing the Mercor Research team.
We’re building a world-class research organization, including @edwardjhu (first author of LoRA), @MinyangTian1 (SciCode, CritPt), Victor Barres (τ²-bench, τ-voice), @hrdkbhatnagar (PostTrainBench), @bertievidgen (APEX-Agents) and many others.
As models get better, the questions get harder:
→ How do you measure a model on a job that AI itself is changing?
→ What data helps when a model fails at real work?
→ How much can a small amount of expert data improve a model?
Mercor Research covers the full AI flywheel. APEX shows where a model struggles. Experts help us understand why and create data for those weak points. We post-train the model and measure it again.
Learn more about our research mission: mercor.com/blog/why-mercor-i…
View open roles on our research team: jobs.ashbyhq.com/mercor?depa…
