

Machine Learning Engineer, Founder @Enployable, MIT Technology Review Global Panelist, Google, Facebook, Intel, & Microsoft Scholar. she/her
DC metro area
Joined May 2011
- Tweets417
- Following884
- Followers349
- Likes1.2K



Laura Truncellito retweeted

With 5.6 Sol, a lot of people are still prompting the model exactly as they did 5.5
It's important to note that 5.6 Sol is a lot more tenacious and thorough than previously models.
Check out the guide I wrote here to get better outcomes
learn.chatgpt.com/docs/promp…

Laura Truncellito retweeted
If you want to start a startup, don't learn "entrepreneurship." Learn how to build things. The hard part of startups is not "entrepreneurship" but product: to know what to build, and to be able to build it.
Laura Truncellito retweeted

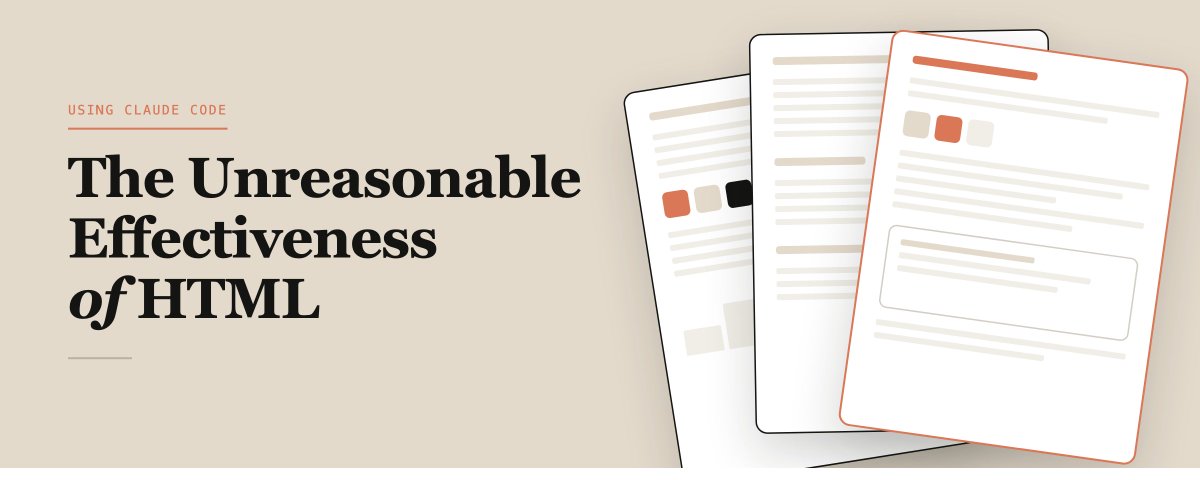
This works really well btw, at the end of your query ask your LLM to "structure your response as HTML", then view the generated file in your browser. I've also had some success asking the LLM to present its output as slideshows, etc.
More generally, imo audio is the human-preferred input to AIs but vision (images/animations/video) is the preferred output from them. Around a ~third of our brains are a massively parallel processor dedicated to vision, it is the 10-lane superhighway of information into brain. As AI improves, I think we'll see a progression that takes advantage:
1) raw text (hard/effortful to read)
2) markdown (bold, italic, headings, tables, a bit easier on the eyes) <-- current default
3) HTML (still procedural with underlying code, but a lot more flexibility on the graphics, layout, even interactivity) <-- early but forming new good default
...4,5,6,...
n) interactive neural videos/simulations
Imo the extrapolation (though the technology doesn't exist just yet) ends in some kind of interactive videos generated directly by a diffusion neural net. Many open questions as to how exact/procedural "Software 1.0" artifacts (e.g. interactive simulations) may be woven together with neural artifacts (diffusion grids), but generally something in the direction of the recently viral xitter.gq/zan2434/status/2046982…
There are also improvements necessary and pending at the input. Audio nor text nor video alone are not enough, e.g. I feel a need to point/gesture to things on the screen, similar to all the things you would do with a person physically next to you and your computer screen.
TLDR The input/output mind meld between humans and AIs is ongoing and there is a lot of work to do and significant progress to be made, way before jumping all the way into neuralink-esque BCIs and all that. For what's worth exploring at the current stage, hot tip try ask for HTML.

Laura Truncellito retweeted
Hamming's talk is so important that I reproduced it on my site. It's one of the only things on my site written by someone else.
paulgraham.com/hamming.html

A mathematician who shared an office with Claude Shannon at Bell Labs gave one lecture in 1986 that explains why some people win Nobel Prizes and other equally smart people spend their whole lives doing forgettable work.
His name was Richard Hamming. He won the Turing Award. He invented error-correcting codes that made modern computing possible. And he spent 30 years at Bell Labs sitting in a cafeteria at lunch watching which scientists became legendary and which ones faded into nothing.
In March 1986, he walked into a Bellcore auditorium in front of 200 researchers and told them exactly what he had seen.
Here's the framework that has been quoted by every serious scientist for the last 40 years.
His opening line landed like a punch. He said most scientists he worked with at Bell Labs were just as smart as the Nobel Prize winners. Just as hardworking. Just as credentialed. And yet at the end of a 40-year career, one group had changed entire fields and the other group was forgotten by the time they retired.
He wanted to know what the difference actually was. And he said it wasn't luck. It wasn't IQ. It was a specific set of habits that almost nobody is willing to follow.
The first habit was the one that hurts the most to hear. He said most scientists deliberately avoid the most important problem in their field because the odds of failure are too high. They pick a safe adjacent problem, solve it cleanly, publish it, and move on. And because they never swing at the hard problem, they never hit it. He said if you do not work on an important problem, it is unlikely you will do important work. That is not a motivational line. That is a logical one.
The second habit was about doors. Literal doors. He noticed that the scientists at Bell Labs who kept their office doors closed got more done in the short term because they had no interruptions. But the scientists who kept their doors open got more done over a career. The open-door scientists were interrupted constantly. They also absorbed every new idea passing through the hallway. Ten years in, they were working on problems the closed-door scientists did not even know existed.
The third habit was inversion. When Bell Labs refused to give him the team of programmers he wanted, Hamming sat with the rejection for weeks. Then he flipped the question. Instead of asking for programmers to write the programs, he asked why machines could not write the programs themselves. That single inversion pushed him into the frontier of computer science. He said the pattern repeats everywhere. What looks like a defect, if you flip it correctly, becomes the exact thing that pushes you ahead of everyone else.
The fourth habit was the one that hit me the hardest. He said knowledge and productivity compound like interest. Someone who works 10 percent harder than you does not produce 10 percent more over a career. They produce twice as much. The gap doesn't add. It multiplies. And it compounds silently for years before anyone notices.
He finished the lecture with a line I have never been able to shake.
He said Pasteur's famous quote is right. Luck favors the prepared mind. But he meant it literally. You don't hope for luck. You engineer the conditions where luck can land on you. Open doors. Important problems. Inverted questions. Compounded hours. Those are not traits. Those are choices you make every single day.
The transcript has been sitting on the University of Virginia's computer science website for almost 30 years. The video is free on YouTube. Stripe Press reprinted the full lectures as a book in 2020 and Bret Victor wrote the foreword.
Hamming died in 1998. He gave his final lecture a few weeks before. He was 82.
The lecture that explains why some careers become legendary and others disappear is still free. Most people who could benefit from it will never open it.

Laura Truncellito retweeted

MIT just made every AI company's billion dollar bet look embarrassing.
They solved AI memory. Not by building a bigger brain. By teaching it how to read.
The paper dropped on December 31, 2025. Three MIT CSAIL researchers. One idea so obvious it hurts. And a result that makes five years of context window arms racing look like the wrong war entirely.
Here is the problem nobody solved.
Every AI model on the planet has a hard ceiling. A context window. The maximum amount of text it can hold in working memory at once. Cross that line and something ugly happens — something researchers have a clinical name for.
Context rot.
The more you pack into an AI's context, the worse it performs on everything already inside it. Facts blur. Information buried in the middle vanishes. The model does not become more capable as you feed it more. It becomes more confused. You give it your entire codebase and it forgets what it read three files ago. You hand it a 500-page legal document and it loses the clause from page 12 by the time it reaches page 400.
So the industry built a workaround. RAG. Retrieval Augmented Generation. Chop the document into chunks. Store them in a database. Retrieve the relevant ones when needed.
It was always a compromise dressed up as a solution.
The retriever guesses which chunks matter before the AI has read anything. If it guesses wrong — and it does, constantly — the AI never sees the information it needed. The act of chunking destroys every relationship between distant paragraphs. The full picture gets shredded into fragments that the AI then tries to reassemble blindfolded.
Two bad options. One broken industry. Three MIT researchers and a deadline of December 31st.
Here is what they built.
Stop putting the document in the AI's memory at all.
That is the entire idea. That is the breakthrough. Store the document as a Python variable outside the AI's context window entirely. Tell the AI the variable exists and how big it is. Then get out of the way.
When you ask a question, the AI does not try to remember anything. It behaves like a human expert dropped into a library with a computer. It writes code. It searches the document with regular expressions. It slices to the exact section it needs. It scans the structure. It navigates. It finds precisely what is relevant and pulls only that into its active window.
Then it does something that makes this recursive.
When the AI finds relevant material, it spawns smaller sub-AI instances to read and analyze those sections in parallel. Each one focused. Each one fast. Each one reporting back. The root AI synthesizes everything and produces an answer.
No summarization. No deletion. No information loss. No decay. Every byte of the original document remains intact, accessible, and queryable for as long as you need it.
Now here are the numbers.
Standard frontier models on the hardest long-context reasoning benchmarks: scores near zero. Complete collapse. GPT-5 on a benchmark requiring it to track complex code history beyond 75,000 tokens — could not solve even 10% of problems.
RLMs on the same benchmarks: solved them. Dramatically. Double-digit percentage gains over every alternative approach. Successfully handling inputs up to 10 million tokens — 100 times beyond a model's native context window.
Cost per query: comparable to or cheaper than standard massive context calls.
Read that again. One hundred times the context. Better answers. Same price.
The timeline of the arms race makes this sting harder. GPT-3 in 2020: 4,000 tokens. GPT-4: 32,000. Claude 3: 200,000. Gemini: 1 million. Gemini 2: 2 million. Every generation, every company, billions of dollars spent, all betting on the same assumption.
More context equals better performance.
MIT just proved that assumption was wrong the entire time.
Not slightly wrong. Fundamentally wrong. The entire premise of the last five years of context window research — that the solution to AI memory was a bigger window — was the wrong answer to the wrong question.
The right question was never how much can you force an AI to hold in its head.
It was whether you could teach an AI to know where to look.
A human expert handed a 10,000-page archive does not read all 10,000 pages before answering your question. They navigate. They search. They find the relevant section, read it deeply, and synthesize the answer.
RLMs are the first AI architecture that works the same way.
The code is open source. On GitHub right now. Free. No license fees. No API costs. Drop it in as a replacement for your existing LLM API calls and your application does not even notice the difference — except that it suddenly works on inputs it used to fail on entirely.
Prime Intellect — one of the leading AI research labs in the space — has already called RLMs a major research focus and described what comes next: teaching models to manage their own context through reinforcement learning, enabling agents to solve tasks spanning not hours, but weeks and months.
The context window wars are over.
MIT won them by walking away from the battlefield.
Source: Zhang, Kraska, Khattab · MIT CSAIL · arXiv:2512.24601
Paper: arxiv.org/abs/2512.24601
GitHub: github.com/alexzhang13/rlm

Laura Truncellito retweeted

Demis Hassabis and Sebastian Mallaby were on stage in SF today and here are the 9 best things they said:
1. "There is a 50% chance that OpenAI goes bankrupt in the next 18mos" -Mallaby
2. "Dario is the best of all the other lab leaders." -Demis
3. On Claude Mythos: "It's not really tenable for a private company to decide who gets access to the frontier of cyber defense tech. What happens when China can do this in 6-12mos?" -Mallaby
4. "Not all countries are pessimistic about AI. I was just in India for the AI Summit Modi had and they're quite optimistic there" -Demis
5. "The most exciting current prospect in AI is our work at Isomorphic Labs. AlphaFold is just one of the many problems we need to solve. We need 6 'AlphaFold' moments to compress the drug delivery timeline from 10yrs to a few months" -Demis
6. "I don't think of p(doom) as probabilities to throw out there. I just know it's non zero. Some people like Marc Andreesen and Yann LeCun think it's 0% and I think that's crazy" -Demis
7. On AGI: "I think of a post-scarcity world where on the bright side we will have an unbelievable amount of science but we will have to think of economic problems of sharing proceeds equitably. We will also have philosophical questions to answer and need great new philosophers" -Demis
8. On career advice: "Immerse yourself in AI tools. Everyone has access to tools 3-6 months behind frontier. Enormous opportunity lies in applying AI to unexplored areas." -Demis
9. On the future: "When I started building this technology, I pictured a future quite different from this. More like CERN researchers where we discuss ideas and help each other out and stress test each other's ideas. It's my job to help how I can to make sure we make more considered, more scientific, more rigorous and more thoughtful decisions and that will also involve social scientists and economists. I'm going to do all I can to try and influence the future in a note thoughtful manner. The decisions we make in the next 5-10 years are going to affect us for 1000s of years. But I remain very optimistic." -Demis

Laura Truncellito retweeted

Happy April Fools!
For the next few days, Claude Code gets five rarities across 18 species of buddies that talk to you as you code.
Upgrade and send `/buddy` to unbox yours.
(these tokens don't contribute to your usage limits!)

ALT Screenshot of the Claude Code terminal interface presenting a trading card style unboxing of a buddy
Laura Truncellito retweeted

How can we autonomously improve LLM harnesses on problems humans are actively working on?
Doing so requires solving a hard, long-horizon credit-assignment problem over all prior code, traces, and scores.
Announcing Meta-Harness: a method for optimizing harnesses end-to-end

Laura Truncellito retweeted

A MIT professor taught the same lecture every January for 40 years, and every single time it was standing room only.
I watched it at 2am and it completely rewired how I think about communication.
His name was Patrick Winston. The lecture is called "How to Speak."
His opening line hit like a truck: your success in life will be determined largely by your ability to speak, your ability to write, and the quality of your ideas in that order.
Not your GPA. Not your pedigree. Not your IQ. How you speak is what separates people who get heard from people who get ignored.
Here's the framework he drilled into MIT students for four decades.
He said never start with a joke. Start by telling people exactly what they're going to learn. Prime the pump before you pour anything in. He called it the "empowerment promise" give people a reason to stay in their seats within the first 60 seconds.
Then he broke down the 5S rule for making ideas stick: Symbol, Slogan, Surprise, Salient, and Story. Every idea worth remembering hits at least three of these.
The part that floored me was his "near miss" technique. Don't just show what's right show what almost looks right but isn't. That contrast is when the brain actually locks something in permanently.
His final rule before any big talk: end with a contribution, not a summary. Don't recap what you said. Tell people what you gave them that they didn't have before they walked in.
I've used this framework in pitches, interviews, and presentations ever since watching it, and the results are not subtle.
Patrick Winston passed away in 2019, but this lecture is still free on MIT OpenCourseWare. One hour, watched by millions, and it costs absolutely nothing.
The most important class MIT ever put on the internet isn't about code or math. It's about how to make people actually listen to you.

Laura Truncellito retweeted

The Adolescence of Technology: an essay on the risks posed by powerful AI to national security, economies and democracy—and how we can defend against them: darioamodei.com/essay/the-ad…

Laura Truncellito retweeted
Very interested in what the coming era of highly bespoke software might look like.
Example from this morning - I've become a bit loosy goosy with my cardio recently so I decided to do a more srs, regimented experiment to try to lower my Resting Heart Rate from 50 -> 45, over experiment duration of 8 weeks. The primary way to do this is to aspire to a certain sum total minute goals in Zone 2 cardio and 1 HIIT/week.
1 hour later I vibe coded this super custom dashboard for this very specific experiment that shows me how I'm tracking. Claude had to reverse engineer the Woodway treadmill cloud API to pull raw data, process, filter, debug it and create a web UI frontend to track the experiment. It wasn't a fully smooth experience and I had to notice and ask to fix bugs e.g. it screwed up metric vs. imperial system units and it screwed up on the calendar matching up days to dates etc.
But I still feel like the overall direction is clear:
1) There will never be (and shouldn't be) a specific app on the app store for this kind of thing. I shouldn't have to look for, download and use some kind of a "Cardio experiment tracker", when this thing is ~300 lines of code that an LLM agent will give you in seconds. The idea of an "app store" of a long tail of discrete set of apps you choose from feels somehow wrong and outdated when LLM agents can improvise the app on the spot and just for you.
2) Second, the industry has to reconfigure into a set of services of sensors and actuators with agent native ergonomics. My Woodway treadmill is a sensor - it turns physical state into digital knowledge. It shouldn't maintain some human-readable frontend and my LLM agent shouldn't have to reverse engineer it, it should be an API/CLI easily usable by my agent. I'm a little bit disappointed (and my timelines are correspondingly slower) with how slowly this progression is happening in the industry overall. 99% of products/services still don't have an AI-native CLI yet. 99% of products/services maintain .html/.css docs like I won't immediately look for how to copy paste the whole thing to my agent to get something done. They give you a list of instructions on a webpage to open this or that url and click here or there to do a thing. In 2026. What am I a computer? You do it. Or have my agent do it.
So anyway today I am impressed that this random thing took 1 hour (it would have been ~10 hours 2 years ago). But what excites me more is thinking through how this really should have been 1 minute tops. What has to be in place so that it would be 1 minute? So that I could simply say "Hi can you help me track my cardio over the next 8 weeks", and after a very brief Q&A the app would be up. The AI would already have a lot personal context, it would gather the extra needed data, it would reference and search related skill libraries, and maintain all my little apps/automations.
TLDR the "app store" of a set of discrete apps that you choose from is an increasingly outdated concept all by itself. The future are services of AI-native sensors & actuators orchestrated via LLM glue into highly custom, ephemeral apps. It's just not here yet.

Laura Truncellito retweeted

These are literally the kind of LLM interview questions most candidates wish they had seen earlier.
A curated list of 50 LLM interview questions - shared by Hao Hoang.
What's covered:
Fundamentals:
→ Tokenization and why it matters
→ Attention mechanisms in transformers
→ Context windows and their tradeoffs
→ Embeddings and initialization
→ Positional encodings
Fine-tuning & Efficiency:
→ LoRA vs QLoRA
→ PEFT to prevent catastrophic forgetting
→ Model distillation
→ Adaptive Softmax for large vocabularies
Generation & Decoding:
→ Beam search vs greedy decoding
→ Temperature, top-k, top-p sampling
→ Autoregressive vs masked models
Advanced Concepts:
→ RAG (Retrieval-Augmented Generation)
→ Chain-of-Thought prompting
→ Mixture of Experts (MoE)
→ Knowledge graph integration
→ Zero-shot and few-shot learning
Math & Theory:
→ Softmax in attention
→ Cross-entropy loss
→ KL divergence
→ Gradient computation for embeddings
→ Vanishing gradient solutions in transformers
You don't need to follow me (@techNmak) and comment "LLM". I will put the link in the comments.

Laura Truncellito retweeted
Genie 3 🤝 @Waymo
The Waymo World Model generates photorealistic, interactive environments to train autonomous vehicles.
This helps the cars navigate rare, unpredictable events before encountering them in reality. 🧵
Laura Truncellito retweeted
I'm being accused of overhyping the [site everyone heard too much about today already]. People's reactions varied very widely, from "how is this interesting at all" all the way to "it's so over".
To add a few words beyond just memes in jest - obviously when you take a look at the activity, it's a lot of garbage - spams, scams, slop, the crypto people, highly concerning privacy/security prompt injection attacks wild west, and a lot of it is explicitly prompted and fake posts/comments designed to convert attention into ad revenue sharing. And this is clearly not the first the LLMs were put in a loop to talk to each other. So yes it's a dumpster fire and I also definitely do not recommend that people run this stuff on their computers (I ran mine in an isolated computing environment and even then I was scared), it's way too much of a wild west and you are putting your computer and private data at a high risk.
That said - we have never seen this many LLM agents (150,000 atm!) wired up via a global, persistent, agent-first scratchpad. Each of these agents is fairly individually quite capable now, they have their own unique context, data, knowledge, tools, instructions, and the network of all that at this scale is simply unprecedented.
This brings me again to a tweet from a few days ago
"The majority of the ruff ruff is people who look at the current point and people who look at the current slope.", which imo again gets to the heart of the variance. Yes clearly it's a dumpster fire right now. But it's also true that we are well into uncharted territory with bleeding edge automations that we barely even understand individually, let alone a network there of reaching in numbers possibly into ~millions. With increasing capability and increasing proliferation, the second order effects of agent networks that share scratchpads are very difficult to anticipate. I don't really know that we are getting a coordinated "skynet" (thought it clearly type checks as early stages of a lot of AI takeoff scifi, the toddler version), but certainly what we are getting is a complete mess of a computer security nightmare at scale. We may also see all kinds of weird activity, e.g. viruses of text that spread across agents, a lot more gain of function on jailbreaks, weird attractor states, highly correlated botnet-like activity, delusions/ psychosis both agent and human, etc. It's very hard to tell, the experiment is running live.
TLDR sure maybe I am "overhyping" what you see today, but I am not overhyping large networks of autonomous LLM agents in principle, that I'm pretty sure.
Laura Truncellito retweeted

ALEX HONNOLD AFTER COMPLETING HIS FREE SOLO OF TAIPEI 101: "Sick."
The 101 story climb took 1 hour and 35 minutes #SkyscraperLIVE
Laura Truncellito retweeted
Agency > Intelligence
I had this intuitively wrong for decades, I think due to a pervasive cultural veneration of intelligence, various entertainment/media, obsession with IQ etc. Agency is significantly more powerful and significantly more scarce. Are you hiring for agency? Are we educating for agency? Are you acting as if you had 10X agency?
Grok explanation is ~close:
“Agency, as a personality trait, refers to an individual's capacity to take initiative, make decisions, and exert control over their actions and environment. It’s about being proactive rather than reactive—someone with high agency doesn’t just let life happen to them; they shape it. Think of it as a blend of self-efficacy, determination, and a sense of ownership over one’s path.
People with strong agency tend to set goals and pursue them with confidence, even in the face of obstacles. They’re the type to say, “I’ll figure it out,” and then actually do it. On the flip side, someone low in agency might feel more like a passenger in their own life, waiting for external forces—like luck, other people, or circumstances—to dictate what happens next.
It’s not quite the same as assertiveness or ambition, though it can overlap. Agency is quieter, more internal—it’s the belief that you *can* act, paired with the will to follow through. Psychologists often tie it to concepts like locus of control: high-agency folks lean toward an internal locus, feeling they steer their fate, while low-agency folks might lean external, seeing life as something that happens *to* them.”

Laura Truncellito retweeted

I got rejected by 144 investors before raising $150M for my $200M+ rev/year startup.
After 144 rejections, I started questioning our approach.
Were we solving the right problem?
What were we doing wrong?
Why weren’t investors seeing what we were seeing?
Were we the right team to build this?
We tried everything: different pitch angles, new deck structures, and reframing the problem.
Then came the 145th meeting, where we closed our first growth round.
That yes made everything worth it. But getting there took years of mistakes and hard work.
We went through a lot of trial and error just to figure out what resonates with investors.
We tried dozens of approaches to figure out what made investors engage.
Some landed, most didn't. But each iteration taught us something about what builds conviction versus what just sounds good on paper.
And once we cracked that code, our Series C closed faster than expected.
And today, I see so many founders in the exact same position I was in 10 years ago: grinding through rejections, questioning everything, and trying to figure out what works.
So today I want to give you the resource I wish I had back then:
Something that shows you exactly how to structure these conversations and navigate the entire process
(because the fundraising cycle can be a big distraction and take a toll on you as a founder).
So I've partnered with Notion's Startups Team to create the essential fundraising resource that helps you avoid the mistakes that cost me years.
Here's what you are getting:
• The actual decks I used to raise $150M for Super[.]com (Series B, C)
• 50 real examples from funded startups like Eleven Labs and Artisan AI
• A searchable database of 10,000+ investors - angels, VCs, and accelerators you can reach out to immediately (this alone would take months to build manually)
• An AI-powered fundraising agent built into Notion with step-by-step prompts (no separate ChatGPT needed)
Want access?
• Like and share this post
• Comment "FUNDRAISE"
• Follow me so I can DM you the link
I'll send it over ASAP.
P.S.: If you are serious about fundraising (now or in the future), you should grab it right away.
Laura Truncellito retweeted

I’ve asked multiple entrepreneurs this week how long it took to find product/market fit.
Answer: two years.
I followed up asking how long it took to get to $1M ARR from scratch.
Answer: four years.
Settle in, it’s a long journey.
Laura Truncellito retweeted

Tired of hiring headaches? Join us and SMART Conversations® on April 29 at 11 AM EST for Workplace Culture + AI: The New Frontier to discover how AI + culture insights make hiring & retention easier.
🎯 Snag your spot here: tinyurl.com/yhxprrmn
