
Machine Learning Scientist @ Netflix | PhD @ UNC Chapel Hill | 2× Meta AI | Computer Vision • Video Understanding • MLLMs • GenAI
Chapel Hill, NC
Joined April 2016
- Tweets419
- Following309
- Followers273
- Likes598



Mohaiminul (Emon) Islam retweeted

Anthropic just reliesed the best 1-hour workshop on Loop engineering: from one prompt to a Loop that improves itself
5:31 - loop memory
11:02 - check, build, commit
13:06 - one feature per loop
33:03 - MVP in 1 hour
Free, the best thing on Loop engineering I've come across.
Watch it, then try your first loop with the step-by-step guide below

🚨 Video AI can see. But can it think? Our paper, SVI-Bench is heading to #ECCV2026!
📊 35K hrs of video
⚡ 15M actions
🧩 9 tasks: perception → reasoning → simulation → agents
The results are striking: ~74% on perception, ~5% in agentic reasoning.
svi-bench.github.io
Mohaiminul (Emon) Islam retweeted

Video models have become good at recognizing actions but still struggle to infer what people are trying to accomplish, why they chose a particular action, and what they will do next. We built SVI-Bench to measure this gap. We'll present it at #ECCV2026 next week. The video below gives a short overview of the work. I also wrote a short post on the broader research direction: gedasbertasius.com/post/from…
Mohaiminul (Emon) Islam retweeted

Join us today @CVPR rooms 704/706 #CVPR2026 at the EgoVis workshop - a long tradition of workshops on egocentric vision from #ECCV2016 10 years ago!
This edition features great keynotes, talks from relevant CVPR papers, accepted contributions&abstracts, challenge&award results.

One of the most popular workshops at @CVPR Join us for engaging talks and discussions on the latest challenges and breakthroughs in computer vision and multimodal AI. See you there!

The 5th Transformers for Vision and Multimodal AI workshop is happening at #CVPR2026 tomorrow (Wednesday, June 3rd)! We've got a great speaker lineup covering diverse topics across Transformers and Multimodal AI.
When: Wed, June 3rd
Where: Room 607
Website: sites.google.com/view/t4v-cv…
Schedule:
1:50 - 2:00 Opening Remarks
2:00 - 2:30 Ranjay Krishna
2:30 - 3:00 Jiatao Gu
3:00 - 3:30 Sherry Yang
3:30 - 4:00 Coffee Break
4:00 - 4:30 Juan Carlos Niebles
4:30 - 5:00 Zhuang Liu
5:00 - 5:30 Peter Tong
See you all tomorrow!
@thoma_gu @RanjayKrishna @sherryyangML @jcniebles @liuzhuang1234 @TongPetersb

Today’s AI models can describe what they see, they cannot yet reason, simulate, and plan. SVI-Bench aims to push the limits of vision models towards achieving human level agency and autonomy.
Check our benchmark and put your novel models to the test: svi-bench.github.io/
In the second before a play develops, a basketball player can instantly recognize the defensive scheme (perception), anticipate how the defense will rotate (causal reasoning), simulate several possible outcomes (simulation), and choose the best move (decision).
Today's video AI is far from this. These models can describe what they see, but they cannot explain why something happened, predict what comes next, or decide how to respond. We introduce SVI-Bench to measure these capabilities, and to push toward models that can reason over real-world, multi-agent video.


Nice summary. Thanks for sharing @cwolferesearch!

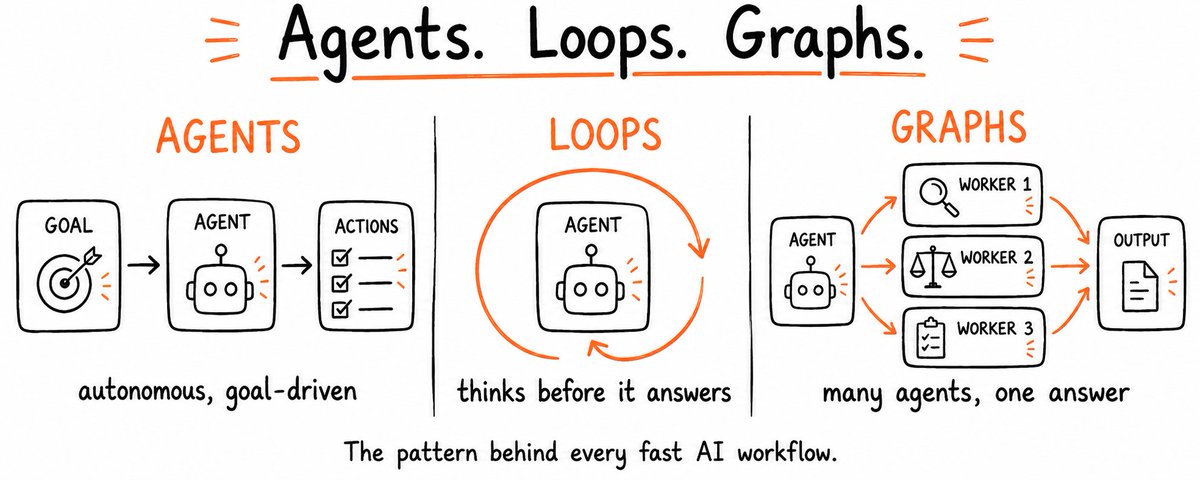
I recently found this practical guide to building agents from OpenAI while doing some reading on agent evals. Nothing groundbreaking in terms of technical content, but it provides a really nice / rigorous structure around agent concepts and their tradeoffs that is useful.
What is an agent? It is possible to integrate an LLM into an automated workflow in a way that is not agentic; e.g., single-turn LLMs or chatbots. The core characteristic that makes a workflow agentic is whether the LLM is provided control of the workflow execution and allowed to make decisions. For example, an agent can control when the workflow is finished, attempt to recover from issues, and use tools to gather context or take actions.
Agent components. An agent is an LLM-powered system that includes multiple components in addition to the LLM:
- Tools: external functions or APIs for taking actions or gathering context.
- Instructions: written guidelines that describe in detail how the agent is expected to behave. We should draw upon existing documentation for our task
Usually, we are using a reasoning model for the LLM, meaning that the model also has the ability to dynamically reason over the instruction to determine how to decompose a problem and call tools in order to accomplish a desired task.
Beyond single agent. We can handle complex tasks with one agent by simply adding ore tools to provide more capabilities. Multiple agents can be helpful to decompose complex workflows, but the extra complexity can also lead to downsides / lower performance.
We should only use multi-agents systems when necessary. Some signs that using multiple agents could be helpful are:
- Instructions are complex, contain many conditional cases, and are becoming difficult to scale / manage.
- Your single agent is experiencing tool overload, meaning that it struggles to select the correct tools from the large set of tools available due to the presence of many similar tools.
Multi-agent systems. There are two main ways we can create a multi-agent system:
1. Manager setup: we have a central “manager” agent that delegates sub-tasks to multiple specialized sub-agents via tool calls and stitches their results into a final answer.
2. Decentralized setup: we have multiple peer agents that hand tasks off to one another based upon their specific purposes.
Both of these structures are common in practice, and we should aim to make each agent in the multi-agent system flexible / composable to simplify scaling of the system over time. We don’t want a brittle system that breaks every time we need to tweak guidelines or add a new capability.
Good instructions. One of the biggest keys to success is writing the best possible instructions for the agent(s). To write good instructions, we should:
- Draw upon existing documentation for the workflow.
- Clearly define guidelines and desired actions for the task.
- Prompt the agent to break the problem into steps.
- Provide concrete examples of how to handle edge cases.

An interesting paper from CVPR 2026: HieraMamba: Video Temporal Grounding via Hierarchical Anchor-Mamba Pooling
arxiv.org/abs/2510.23043
Fun fact: found my four papers from last 4 years cited in a row like that this. Nice sequence!

Mohaiminul (Emon) Islam retweeted

🎥🪄 What should happen when you remove an object from a video?
Example 1:
A domino chain is falling → remove the middle blocks → the last block should remain standing
Example 2:
Two cars are about to crash → remove one car → the other should drive away 🚙
Current video object removal models fail at these dynamic scenarios.
We introduce VOID: a model that removes objects and updates the scene as if they were never there.
🏆 Preferred 64.8% of the time vs Runway Aleph, Gen-Omnimatte, ProPainter, and more.
🌐 Project page: void-model.github.io
💻 GitHub: github.com/Netflix/void-mode…
🤗 Demo: huggingface.co/spaces/sam-mo…
📄 arXiv: arxiv.org/abs/2604.02296
w/ @willarvey @ZhuoningYuan @ChengTim0708 and collaborators at @NetflixResearch and @INSAITinstitute
Mohaiminul (Emon) Islam retweeted

Introducing Ego2Web from Google DeepMind and UNC Chapel Hill, accepted to #CVPR2026.
AI agents can browse the web. But can they act based on what you see? Existing benchmarks focus only on web interaction while ignoring the real world.
Ego2Web bridges egocentric video perception and web execution, enabling agents that can see through first-person video, understand real-world context, and take actions on the web grounded in the egocentric video.
This opens a path toward AI assistants that operate seamlessly across physical and digital environments. We hope Ego2Web serves as an important step for building more capable, perception-driven agents.
🧵👇
Mohaiminul (Emon) Islam retweeted
If you're curious about the background that inspires a lot of our group's research on skill learning and video understanding, check out this great piece by UNC Research. It covers some of my journey from being a basketball player to an AI researcher.
research.unc.edu/story/readi…

Mohaiminul (Emon) Islam retweeted

Train Beyond Language. We bet on the visual world as the critical next step alongside and beyond language modeling. So, we studied building foundation models from scratch with vision.
We share our exploration: visual representations, data, world modeling, architecture, and scaling behavior! [1/9]

Thrilled to share that I’ve joined Netflix as a Machine Learning Scientist 🎬
I’ll work on large-scale AI solutions for content understanding and promotions, focusing on Computer Vision, Video Understanding, and VLMs—advancing video AI in real-world, production-scale systems.

Mohaiminul (Emon) Islam retweeted

DeepSeek just dropped a banger paper to wrap up 2025
"mHC: Manifold-Constrained Hyper-Connections"
Hyper-Connections turn the single residual “highway” in transformers into n parallel lanes, and each layer learns how to shuffle and share signal between lanes.
But if each layer can arbitrarily amplify or shrink lanes, the product of those shuffles across depth makes signals/gradients blow up or fade out.
So they force each shuffle to be mass-conserving: a doubly stochastic matrix (nonnegative, every row/column sums to 1). Each layer can only redistribute signal across lanes, not create or destroy it, so the deep skip-path stays stable while features still mix!
with n=4 it adds ~6.7% training time, but cuts final loss by ~0.02, and keeps worst-case backward gain ~1.6 (vs ~3000 without the constraint), with consistent benchmark wins across the board

Mohaiminul (Emon) Islam retweeted
Hard to believe it’s been almost 5 years since I started at UNC. 2025 was an exciting year for our group!
🎓 My two PhD students—who joined me when I had an empty group—are graduating. Watching them grow into experts has been the best part of the job.
🏀 We are branching into Robotics & Sports (combining my personal passions with work!).
🎥 Our new video systems, BIMBA & SiLVR, achieved excellent performance across many challenging benchmarks.
🏆 Grateful for the awards we received across academia and industry this year.
I used to worry about making it in academia. Now, I'm just happy to be here. Huge thanks to my group for an incredible 2025. Here is a snapshot of what we accomplished! 📸

Mohaiminul (Emon) Islam retweeted
So well deserved! It was a pleasure watching you grow from having no prior CV experience to developing leading models in long video understanding. Fun fact: @mmiemon had all of his first-author papers accepted on the first attempt —a rare feat I haven't witnessed before. Excited to see what you do next!

I defended my PhD on October 6, 2025. Yesterday, my professor @gberta227 treated me to a wonderful lunch and surprised me with a thoughtful gift!
I’m truly grateful for the support, guidance, and kindness throughout these years. Feeling excited for what comes next 😊🙏


I defended my PhD on October 6, 2025. Yesterday, my professor @gberta227 treated me to a wonderful lunch and surprised me with a thoughtful gift!
I’m truly grateful for the support, guidance, and kindness throughout these years. Feeling excited for what comes next 😊🙏
Mohaiminul (Emon) Islam retweeted
My student Han will be presenting our new video-language benchmark for expert action analysis (ExAct) on Wednesday. Be sure to stop by and chat about it at the poster session!

Come to our poster at #NeurIPS2025 !
📝 ExAct: A Video-Language Benchmark for Expert Action Analysis
🗓️ Wed, Dec 3 | 🕒 11:00 AM–2:00 PM (PST)
📍 Poster #4712 | Exhibit Hall C, D, E
📝 Paper: arxiv.org/abs/2506.06277
🌐 Project: texaser.github.io/exact_proj…

Mohaiminul (Emon) Islam retweeted

🚀 Hello, Kimi K2 Thinking!
The Open-Source Thinking Agent Model is here.
🔹 SOTA on HLE (44.9%) and BrowseComp (60.2%)
🔹 Executes up to 200 – 300 sequential tool calls without human interference
🔹 Excels in reasoning, agentic search, and coding
🔹 256K context window
Built as a thinking agent, K2 Thinking marks our latest efforts in test-time scaling — scaling both thinking tokens and tool-calling turns.
K2 Thinking is now live on kimi.com in chat mode, with full agentic mode coming soon. It is also accessible via API.
🔌 API is live: platform.moonshot.ai
🔗 Tech blog: moonshotai.github.io/Kimi-K2…
🔗 Weights & code: huggingface.co/moonshotai
