

phd @mbzuai | multimodal in research & life.
Joined November 2020
- Tweets584
- Following926
- Followers454
- Likes2.7K




Pinned Tweet
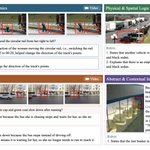
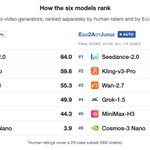
🤖🤚 Give a video generation model a scene and a goal. Can it generate egocentric execution to get the job done?
We tested 110 real-world scenarios on 6 SoTA models to see how they perform.
Introducing Ego2Act, a goal-directed video generation benchmark 👇
🌐 ego2act.github.io
🧪 alphaxiv.org/abs/2610.01092
🤗 huggingface.co/datasets/ego2…
[🧵Thread]
patrick retweeted

I improved NanoGPT Speedrun from 39.9s → 6.7s (-83.2%), more than every record since 2025 combined (-81.4%)!
The web is full of rare, repeated content that the LM can’t memorize in time. I solve this with retrieval-augmented n-gram hints🧵
day 3
felt lot faster writing with my leftie, lets see whether the speed holds or not
xitter.gq/patrickamadeus_/status…


patrick retweeted

Gemini 4 Carbon is our next frontier model.
It’s state-of-the-art across cybersecurity and long-horizon capabilities.


"Exhibit taste, empathy, and principled thinking."
well said and the future is exciting!

The coding interview is dead, at least for my team at Anthropic. I've seen enough to know that it no longer provides signal. I removed it from loops this month.
I have a spicy, optimistic take - I think there's an opportunity for junior engineers: felixrieseberg.com/hunger-be…

This + one last human sign-off (just making sure things went alright) will feed generations 🤩🔥

I think this is one of the coolest evals projects happening rn. Double-blind AI evaluations:
deepmind.google/blog/pilotin…
Kudos @iamtrask @SolomonMg @wsisaac and team


patrick retweeted

This is the most valuable free resource we've created on AI Evals 🎉 (not exaggerating!)
I organized our public materials into this guide. It allows you to find answers to your eval problems w/o searching aimlessly.
Humans: pick the row that sounds like you.
Agents: point it at the post
The material draw on 60+ hours of office hours from our Evals course, where @sh_reya and I have taught 5k engineers and PMs Evals.
We add new material often, with 15 FAQs added in the last two weeks. Recent additions are marked with a "New" badge. You can find all of these and more here:
hamel.dev/blog/posts/evals-f…

patrick retweeted
I've been looking into public benchmarks and am astounded by the poor quality vs. how much we rely on them as an industry.
@xeophon pointed me to this excellent site epoch.ai/benchmarks/ which is an independent third party which scrutinizes benchmarks and "looks at the data" 💪
For example, here are some popular benchmarks we all rely on. Before trusting a benchmark its worth running them and inspecting examples the grader failed carefully, to get a sense of the quality.
I'm continuing to look more into this, and will write something up eventually once I've collected more data, but I think this is an important subject.

patrick retweeted

have we exhausted the mine of low-hanging verifiability for building evals and rl environment?
any thoughts?


We're open-sourcing RL360, the RL infrastructure behind K2 Horizon's six domain experts: 8,192 concurrent sandboxes, 150 steps in 7 days, ~1.3M rollouts.
Long-horizon agentic RL runs thousands of agents in real sandboxes on tasks that take minutes. Some of those sandboxes crash mid-task, and a crash arrives as the same low score as a wrong answer.
Without infrastructure that can keep up, GPUs are underutilized and the model gets penalized for system crashes rather than its own mistakes.
RL360 is built for this. We share how it works, what broke at scale, and what we learned in the thread.
Code: github.com/ifm-ai/RL360
Run: wandb.ai/mbzuai-llm/rl360-pu…
interesting read, summary:
- $500 only for defeating Ender Dragon, wow
- finished at 27 hours
- half of the run is for the final fight, with most deaths cluster there
- multi-agent collaboration on long-horizon tasks (though there are only 50-80 chats between them)
- self organization on how they divide tasks / labors emerges
limitations:
- collaboration is still a hurdle
- not vision-based agents like VPT or MineDojo-style setup
- brute force is cheap here (605 deaths)

If this is not a wakeup call to the uppers, idk what else, udah terlalu ketara dari kancah global bahwa nusantara sedang tidak baik" saja
Yall been saying "its okay its okay as long as the finance is good" and look how the tables have turned 🚨🫢


patrick retweeted

Everyone wants to have solved a hard problem, but almost nobody wants to live inside the grind of actually solving it. The breakthroughs belong to the few who are obsessed with the process, not just the idea of the outcome

assuming from linkedin that they have 6k (?) total employees, 2k MTS (~30% of the team, which lets say all of em code at same freq) thats a WHOPPING 15 PRs per engineer per day which means roughly ~2 PR per hour 😩😤
such a crazy velocity on shipping high quality stuffs (even with help of agents/AI). frontiers for a reason

New on our Engineering blog: Creating in-house source control.
In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale.
Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: anthropic.com/engineering/re…

RL-ed a BC-VPT agent to chop a tree with pixels only verification using SIMA-2 reward rubric, and it goes something like
1. "oh a white blocky thing, let's punch the 'log' yay"
2. "dang, why no birch in my bag… that was a sheep..."
3. "aight, I'll punch the right one somewhere"
4. until my step budget (500) is out
No log collected but 3.7-flash and Qwen-3.5 rewards success
A stronger (verifiable RL-ed) baseline also break the log only after 700 inefficient movement steps
Still so much to solve in embodied (fine-grained) verification + long-horizon task completion 🤩