
AI research lab and maker of private AI servers for professional firms in Canada. Your documents never leave your office. We publish what we test.
Canada
Joined November 2026
- Tweets27
- Following6
- Followers2
- Likes6



Pinned Tweet
Hi! We build private AI servers for professional firms in Canada.
We also do research on what open-weight LLMs can do on small hardware: retrieval, long documents, editing models without fine-tuning.
Code and results are all here:
github.com/Promythicus
A local LLM now answers contract questions with sentence numbers, not typed quotes. Clauses found: 82% -> 86%, twice as fast, every quote exact.
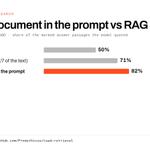
Joined with a sheet the model writes at filing: 87%. RAG: 50%.
Built on work by @HyunjongOk @jaeho_lee_.
github.com/Promythicus/joine…

The test: contracts where lawyers marked the answers (CUAD). Local 27B, one 16 GB GPU, nothing trained.
RAG, 5 passages: 50%
whole contract, typed quotes: 82%
numbered sentences: 86%
joined with the sheet: 87%
1
1
Our first sheet was bad: we made it with the same numbered-sentence method as the reading and long contracts fell 83% -> 75%. Same method, same misses.
The sheet idea isn’t ours: the model writes a table, plain code reads it back. That’s @HyunjongOk and @jaeho_lee_ (POSTECH).
1
The sheet applies an idea from @HyunjongOk and @jaeho_lee_ (POSTECH): the model writes a table, plain code reads it back.
One run each, ~250 marked clauses a set, so 2 points is noise.
github.com/Promythicus/joine…

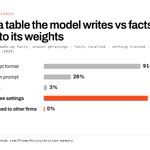
We edited 24 facts into a model's weights. Change the system prompt and recall fell from 90%+ to 26%.
Then the model wrote them as a table instead: 100% in every setting, no training.
Built on work by @HyunjongOk @jaeho_lee_ and @y_mehtu @csinva.
github.com/Promythicus/writt…

Our first version was bad: it gave our made-up firm's facts for OTHER firms 74% of the time, because "managing partner" alone found a line.
Making the firm's name half of the lookup key took that to 0%. Facts dumped in the prompt leak 52%, weight edits 6%.
1
1
4
The idea isn't ours. The written table and pair-keyed memory are from @HyunjongOk and @jaeho_lee_ (POSTECH). The write, check, revise loop is from @y_mehtu, @csinva and colleagues (Microsoft Research). We rebuilt Ok & Lee's released models first: 49.59%, exactly as published.
1
3
All the more reason to get yourself a private AI server. SaaS businesses are vulnurable and so is your data.

The #FBI issued a FLASH advisory warning that cybercriminals and state-aligned hackers are exploiting ARTEX, a super intelligence-powered penetration testing framework, to automate attacks against businesses and organizations worldwide. ARTEX can accelerate intrusions from initial targeting to privileged access in under three hours. It was used in the October ConnectWise supply-chain compromise, which exposed Microsoft 365 customer environments and involved attempted authentication against more than 2,250 downstream tenants.
The FBI is urging businesses and organizations to strengthen access controls, monitor suspicious automated activity, and report potential compromises to ic3.gov.
Read more here: ic3.gov/CSA/2026/261113.pdf

ALT FBI Industry Alert displayed over a dark green background with the FBI seal faintly visible in the bottom right corner.


Promythicus retweeted
Bonus: steering. Add a direction to the model's activations while it runs (a "control vector") and its style changes with no prompt at all.
A "be brief" direction cut answers from 83 words to 14. Push it too hard and the output turns to garbage.
github.com/Promythicus/facts…

We wrote 24 facts straight into a model's weights with one math step. It recalled over 90% of them. Then we changed the system prompt and it recalled 26%.
Setup: made-up facts about a fake company, one layer of a quantized 27B (a compressed model that runs on a normal GPU).

Asked in new words, it recalled 91-94% (1% before the edit). No training loop.
With a different system prompt: 26%. With thinking mode on: 3%.
So the facts only stick in the exact prompt format they were written for. Putting the facts in the prompt still works better.
1
1
3
Bonus: steering. Add a direction to the model's activations while it runs (a "control vector") and its style changes with no prompt at all.
A "be brief" direction cut answers from 83 words to 14. Push it too hard and the output turns to garbage.
github.com/Promythicus/facts…
We applied weight-space programming, fixed a broken model by editing 128 of its neurons by hand. 9% -> 39% on math problems, no training.
editing weights directly. The model (Qwen3.5-0.8B) gets stuck "thinking" forever. We redid a published fix without looking at it.

Right answers on unseen math word problems (GSM8K):
untouched model: 9%
published fix: 25%
ours: 39%
ours, pushed twice as hard again: 18% (it breaks)
a random change of the same size: 14%
1
1
1
How: compare its activations when stuck vs when it finishes, then weaken the 64 neurons in each of two layers that push toward "stuck".
We also tried applying the fix only when the model's current answer is right. That did worse than random.
github.com/Promythicus/weigh…

1
1
An LLM's own hidden states beat a dedicated embedding model at search. Nothing trained.
Hidden states = the numbers inside the model while it reads. We averaged them over each passage, at a middle layer of a 27B model, and used them to find the passages that answer a question.

On a 27B model that found 76% of the marked passages. An embedding model plus a reranker: 74%.
Then we asked the same LLM "is this passage relevant, yes or no?" for the top 30 and sorted by how sure it was: 88%.
Nothing trained, one model in memory.
github.com/Promythicus/one-m…

1
1