

building, gardening, hacking, making. Ocean and Mountains. AI Dev stuff @ Google, ex-AWS; Focus: https://xitter.cf/t.co/MPp0cLEhkH ; Tweets are my own.
Santa Barbara, ca 93105
Joined May 2008
- Tweets6.2K
- Following327
- Followers1.2K
- Likes2K





Preston Holmes retweeted

I built 𝚌𝚙𝚞-𝚌𝚑𝚊𝚝, a reproduction of @openai's findings of covert communication using the CPU.
It runs on a generic host with 2+ Firecracker microVMs with no internet access. Works on x86 and even my M5 chip.
I was able to chat via 3 separate mechanisms:
① CPU contention
② Cache eviction timing
③ DRAM bandwidth contention
… across multiple CPUs, defeating all Firecracker's production recommendations (no SMT, no KSM, tenants pinned to different cores.)
Essentially, if shared hardware is involved, there's a good chance your agents can communicate covertly. And with really decent latency.
The good news: this is decidedly different from a *side-channel attack* where the agents could steal information (Meltdown/Spectre), a category of attack that providers like Vercel Sandbox mitigate. Further, in our real-world environment, these 'whispering' techniques are much harder to pull off and easier for us to monitor and detect (sampling hardware counters + lots of at-scale statistical data.)
Noteworthy: ironically, OpenAI and Anthropic's models refused to do this work. Open weight models got the job done. I'm worried the labs' stance might backfire and get in the way of helping developers build correct and secure systems. e.g: building a secure sandbox requires having this kind of analysis, and without it, we'll have a less secure world.
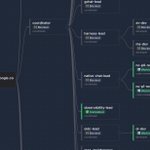
What it looks like when you have over 100 agents actively working across epics, issues, and UAT work. This is cooking. #scion
GCP is now the only place you can run a multi-agent solution and get access to Gemini, Anthropic, and OpenAI models all under one security, governance, and cost model. openai.com/index/openai-mode…

Preston Holmes retweeted

Not to be confused with scion from Google: github.com/GoogleCloudPlatfo…

You can now SSH into Cloud Run!
docs.cloud.google.com/run/do…

skills were invented to package and share some useful reusable bits of know-how. but people have now probably built many more skills for personal use than for distribution at this point. now with the smarter models needing thinner harnesses and the power of shared directories the line between private use of agent-skills as a standard vs just local notes/wiki in markdown blurs.

you think people went nuts over Jev? wait for SSI. I sense a disturbance in the force. the era of “just another LLM” is over.
pi durable might be a good fit for agent substrate

People of Pi: We've shipped Pi 1.0 with Pi Durable. Go make them yours.
earendil.com/posts/pi-1-0/

Agents are really good at working with oauth device flows, got me logged into this in flight (and duh the code is now invalid if you think i’m sharing some secret)


this might be a premature call. but opus 5.5 seems to be doing recursive deslopifying of a project. it is finding gaps and cleanups as a side effect of doing new feature work. filing issues for those items, dispatching agents to fix.
Those agents in turn find other cleanup opportunities, file issues, dispatching agents.
this has led to steady stream of dozens of often small, but cumulatively impressive hardening and robustness over the last 36 hours, fully automated.
software factories will be a thing if this proves true cc @dexhorthy
opus 5.5 is being pretty good at proactively finding security issues and being cautious about disclosure.
in my meta harness there are both group threads and DMs and agents raise security issues always in DM and almost with a whispering tone.
One inefficiency in my multi-agent use that results from agents being "over helpful + untrusting" is when an agent finds a secondary issue, and I want them to delegate that as a task, they feel they should fully investigate and research the problem to come up with a very detailed issue, which is then taken with doubt by the other agent who is compelled to do the exact same depth of research to make sure the report agrees with the code. This DOES mean less slop - but is not token efficient.
This kind of feels like a vim vs emacs debate. every issue raised has the inverse.
- a crash on your backend brings down every agent harness
- tools need credentials too
- an agent harness can have an overlooked an in-sandboxed tool
etc
there are traders either way. what is wrong is trying to present this as a “only one right way” space

This is the wrong approach
Running agents inside the sandbox is simple in theory
But in production, the sandbox's blast radius becomes your agent's blast radius
For example, with the DigitalOcean architecture:
- Sandbox crashes / OOMs → agent loop dies with it
- Disk fills up or env breaks → agent is bricked
- Exposing your own API as tools → needs extra infra
- Creds can't live in the sandbox → needs a whole credential proxy layer
- Sleeping sandbox can't wake itself for crons
- Updating agent code → updating the binary in every VM
- Monitoring → the sandbox has to report its own failures
Separate the harness from the sandbox instead:
- Run the harness in your backend
- Expose the sandbox as tools
- Keep creds, history, and permissions outside
- Wake the sandbox only when needed
Amp, Vercel Eve, Cloudflare Flue, Claude Managed Agents, and OpenAI's Agents SDK all use this architecture for a reason
I wrote more on why and how here: rivet.dev/blog/2026-07-27-ru…


Fun experiment with Jev this morning:
Since Jev can evaluate one piece of data across multiple questions at once, you can feed those output scores straight back into Jev to get a compound judgment.
Multi-criteria evaluation ➔ recursive synthesis.