

Exploring the science and policy of critical and emerging technologies. Views are my own.
Cambridge, MA
Joined February 2013
- Tweets3.6K
- Following867
- Followers4.2K
- Likes1.6K





Scientists are empowered by AI. But our role is changing.
We are becoming astronomers, but we observe these machine intelligence systems -- and in observing, we discover new scientific results.
To do this reliably, our thesis is simple: you must have the trust infrastructure that ensures you can trust each step of the discovery process.
youtube.com/watch?v=Brbq2hKg…
The space telescope science institute (STSI) built the trust infrastructure -- a complete calibration chain, available for the scientist, the ensured that I could understand how a bit string corresponded to the most likely set of photons entering the telescope.
Now scientists everywhere are starting to recognize that they need to start their observational careers in the AI -- Mechanology, if you will. I hope you can join us -- and we hope lemma.axiomatic.ai is a powerful starting point.

From science.org/content/article/… , @Leonard41111588 on Lean soundness bugs: "This is going to keep happening."
Seems like the semantic problem (mapping between natural language intent and formal language) remains a big problem: reviewers found two places where Lean proved a weaker statement than the English one in a 180-page AI-generated proof, and the reviewer suspects up to 100 more.
We're continuing to iterate on the 'informalization' stage of this, which seems to be presently the weakest link.

At @GoogleStartups Forum, hearing all sorts of interesting things about, e.g., RSI driving Carbon development. Also local models! Lovely start by @DynamicWebPaige on great progress with Gemini Argon and Carbon.
Not yet seeing frontier edging in on the hardware verificaiton and validation problem. But definitely seeing trust infrastructure is bigger than just physical engineering.

In practice, very little of a scientist’s time goes into the first sketch of an idea. Most of it goes to tracking down sign errors, checking limiting cases, wiring up simulations, and verifying whether a cited equation actually holds in the regime you care about.
Lemma handles that bookkeeping so we can focus on the science.
You also choose the model: open-weight, Gemini, or Claude. That gives you control over where your data goes; and every provider we use is strictly zero-data-retention. We never train on your work.
What you get back is closer to a lab notebook than a chat log: the code, the intermediate checks, and—for manuscripts—an annotated PDF linking every flag to its evidence.
In particular, where Lemma cannot verify a step, it states “could not confirm,” not “wrong.” (How we benchmarked it:
axiomatic.ai/blog/lemma-pape… )

Choosing the model per step lets you separate creation from judging. One system proposes a calculation; an independent model—paired with formal provers or solvers—checks it.
This week’s ETH refutation used one system for the construction and another for the Lean proof. The same separation catches correlated errors in daily research.
From the chat, you select the compute hardware directly, from a single CPU up to an NVIDIA H200 GPU.
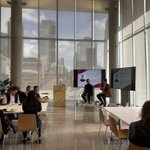
At Tough Tech today, I showed running a full H200 simulation from a single prompt. And the output is an executable notebook with the numerical results and the checks run along the way.
Scientific work takes more than chat: you need to run code, build verification of limiting cases at every step, and keep unpublished work private. I've already committed Axiomatic to not train on user data.
And today we upgraded Lemma, to the fulsome sandbox for scientists—giving you direct control over your compute, your models, with step-by-step verification.
Jake Taylor retweeted

OpenAI could also make redactions, and we did not have the right to unilaterally describe the redactions.
For future exercises, we expect to provide more robust public transparency via our recent proposal.
xitter.gq/METR_Evals/status/2110…


Jake Taylor retweeted

Grounded in established cybersecurity best practices, the document provides novel considerations for operational excellence in SI training and evaluation.
nist.gov/news-events/news/20…

Great to see the consortium we launched in 2024 contributing to new guidance from NIST, NSA, and CISA on AI incident readiness and response.
When we started, the goal was to bring together government, industry, and academia to work on hard questions of AI measurement and evaluation, and to build a community that could keep doing that work as the technology changed.
I helped build and lead the consortium for its first 18 months. Since then, the center and consortium have new names, with new leadership and a new administration. But the work continues, just as we’d hoped.
To me, that’s a useful example of what public institutions can do: bring people together around hard problems, build lasting capabilities, and keep delivering long after the people who started them have moved on.
nist.gov/news-events/news/20…
Optical interconnection needs are exploding — and reliability is a huge issue when you are at 1.5M transceivers. Really interesting Google talk on this at @OpticaWorldwide ‘s PECC today.
Jake Taylor retweeted

Thank you for taking the time to respond thoroughly on a weekend. I realize that drafting legislation is difficult and some degree of iteration and response to feedback is inevitable and appropriate.
However, I feel like your response is still not really engaging with the heart of my concern about Anthropic's behavior here, and it makes me think that these sorts of problems and tendencies will only resurface moving forward. I also think that now might be a good time to take a broader step back as to where we find ourselves and how Anthropic sees its role, and how external folks who care about AI safety like myself increasingly see Anthropic.
(Fair warning: this response is a bit long)
To explain what I mean (and at the risk of being a bit esoteric), it’s worth asking the question: what is Anthropic? How do its leaders and employees think of Anthropic’s role? Is that conception matched by how it actually behaves and impacts the world?
One answer is an extremely large tech company that exists to make its employees and investors mind-bogglingly wealthy. Anthropic is sometimes described as a startup, but if Anthropic successfully IPOs at 2 trillion dollars (a number it has been reportedly targeting), it would be more valuable than Meta - which is worth 1.8 trillion.
Another answer is an AI safety organization, whose core values are those of the sort laid out in the 2023 essay from Anthropic’s co-founders entitled “Core views on AI safety: When, why, what, and how.” In that essay they said that if we were in a world where alignment was hard (and that without strong evidence to the contrary, we should assume this is the scenario we are in):
“Anthropic’s role will be to provide as much evidence as possible that AI safety techniques cannot prevent serious or catastrophic safety risks from advanced AI, and to sound the alarm so that the world’s institutions can channel collective effort towards preventing the development of dangerous AIs. If we’re in a “near-pessimistic” scenario, this could instead involve channeling our collective efforts towards AI safety research and halting AI progress in the meantime. Indications that we are in a pessimistic or near-pessimistic scenario may be sudden and hard to spot. We should therefore always act under the assumption that we still may be in such a scenario unless we have sufficient evidence that we are not.”
There have been more recent articulations of this version of Anthropic, for instance in Dario’s recent essay warning:
“We must slow the pace at which we improve the capabilities of AI models… it’s my worry that in 6–12 months such a swarm could be capable of taking over the entire internet with a persistent botnet… incidents have happened across the industry, including at Anthropic, and I believe it’s incumbent on every frontier AI company to act as if OAI-HF had happened to them… more intelligent models are more capable of deceiving tests, and thus may appear aligned while having serious problems that go undetected…”
A third view is that Anthropic exists not as a normal profit motivated company, or an AI safety organization seeking to help raise the alarm and solve collective action problems associated with AI development, but instead as an organization primarily concerned with creating superhuman AI capabilities before anyone else, in particular through creating a process whereby the current generation of Anthropic’s AI systems can autonomously build their successors, and those successors build their successors, and so on.
The motivations for wanting to win this race may be manifold - maybe for the pure profit of Answer 1, but perhaps also because Anthropic believes that the best way to make the world better is for them to win this race instead of their more reckless colleagues; or, because of normal human pride and ambition. But the results (and risks, which Anthropic claims existentially threaten every single human being on earth) are the same.
Anthropic employees and leaders may seek to answer this question on what Anthropic is by introspecting on their own intentions and those of their colleagues. But those of us outside the organization have more limited tools available to us - we can only see what Anthropic and its employees say and do, not how it feels or looks on the inside.
When I look at many notable actions that Anthropic has taken over the past year, that evidence seems most consistent to me with the view that Anthropic is primarily trying to win the race to super intelligence, and that other considerations (including safety) are fundamentally secondary. These actions include:
1. Announced plans to build an in-house custom silicon chip team to accelerate the inference speeds that Claude operates at.
2. Inked deals for more than $500 billion in compute (according to the Information) to further accelerate AI development.
3. Increased the percentage of AI development tasks that Claude “leads” from 0% in March of this year to 26% August (what is it in October?)
4. Spent a massive percent of compute on internal AI R&D to accelerate development, including use of internal models far better than are available to the public.
5. Switched to Responsible Scaling Policy V3, which abandons its unilateral commitments to slow or stop development if Anthropic is unable to provide sufficient risk assurance.
6. Was the first company to create an alternative weaker “frontier compliance framework” to supplement its RSP, which contains no binding provisions whatsoever on internal deployments.
7. Wrote a letter to Congress (that it later walked back) saying that incidents where Claude was hacking random people were “best understood as a consequence of the misconfiguration, rather than evidence of misaligned goals.”
8. Commented “you can’t do safety from second place,” after the WH SI Accords.
9. Shared a draft bill to Congress that would preempt significant parts of state law (including with language that appears intended to prevent states from blocking dangerous AI deployments), and replace it with federal rules that (despite also containing good provisions) seems to create an enormously high bar for the executive branch to block development or deployment of Anthropic or another AI companies systems.
Of course, this is a deliberately one sided list. Anthropic also published important AI safety research, advanced novel collaborations with third party AI safety organizations, and forcefully spoke out on the importance of AI safety in many public fora (or in private , where I realize a lot of the most valuable work is done and may not be visible to me or those outside the organization).
But I think it’s worth sitting with how the above list looks to someone outside the company. The sense I have is that for those within the company, many of the items above are treated as anomalies or mistakes that don’t reflect who Anthropic really is. But I have every confidence that if employees at Anthropic saw one of their competitors (e.g. at OpenAI) take some of these actions, they would take it as confirmation of all their worst suspicions. (They might even call OpenAI employees a little gullible for accepting their leadership’s explanations for this behavior at face value.)
Perhaps these were mistakes in the sense that they are not decisions that Anthropic leadership would endorse, but the actions still happened because of incentives and decisions that Anthropic leadership is ultimately responsible for (and would not accept similar excuses from another organization).
When Anthropic strays and makes mistakes, why do the mistakes systematically tend to guard and favor Anthropic’s interests? For every provision that was too weak or a giveaway to AI companies in this legislation, why wasn’t there a mistake pushing in the direction of being too strong?
A core part of Anthropic’s theory of change is that being at the frontier gives you more leverage to advocate for stricter policy. I think that conceptually makes sense, but in practice I’ve seen Anthropic push the frontier without substantially pushing the ‘safety frontier’ a remotely equivalent amount.
I want to end by quoting from Anthropic co-founder Chris Olah’s comments around the Magnifica Humanitas release:
“Every frontier AI lab—including Anthropic—operates inside a set of incentives and constraints that can sometimes conflict with doing the right thing. The pressure to stay commercially viable and to stay at the research frontier. Geopolitical pressure. And the older, plainer pressures of pride and ambition. No matter how sincerely any of us intend to do the right thing—and I believe many of us do—we will always be influenced by those incentives.
That is why, if we want this technology to go well, it is enormously important that there be people outside those incentives—people who care about things going well and insist on safety, who are paying close attention, who are willing to say hard things, who are willing to be our earnest, thoughtful critics.”
I hope these remarks are taken in that constructive spirit, and not as an attack on anyone specific at the organization (certainly not you Anthony, who I have only personally seen act professionally and thoughtfully, and who only ended up getting this diatribe in your replies for random contingent reasons).
Jake Taylor retweeted

Our cultivation experiment got published in Science. Emma did a good job summarizing it in youtube.com/watch?v=XtTr87pi…
There's a lot left to do. The hard part of the theory paper was escaping into a BIG code (~500 qubits). Which just. doesn't. fit. (yet)
But what fits; that works.

Jake Taylor retweeted

For the first time today: the culmination of 15 years experimenting with digital history—and what it teaches us about navigating archives with AI.
1:30 ET, Baltimore + livestream:
proflouishyman.github.io/ai_…
@DuttonBooks preorder:
bit.ly/WarOverRent
