

Solve i̶n̶t̶e̶l̶l̶i̶g̶e̶n̶c̶e̶ ̶ coding, use it to solve everything else | Research @AnthropicAI | Past: RL @GoogleDeepmind: AlphaProof co-lead, Gemini.
San Francisco, CA
Joined July 2009
- Tweets339
- Following368
- Followers3.6K
- Likes9.5K




Rishi Mehta retweeted

So I finally caught "You Can See Everything" last night and I never would have predicted that in a documentary about one of the worst corporate fraudsters in history and her psychopath husband that the person who would come out worst would randomly be Amanda Seyfried.
Rishi Mehta retweeted

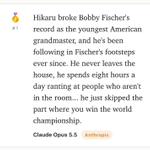
Anthropic has been warning about AI-enabled cyberattacks at least since 2022, with @logangraham at the forefront of that work. Back then, no VC was taking it seriously. The paradox is that risks only feel real once they’re legible, but waiting for incidents is too late. Anthropic also built sycophancy evals (@EthanJPerez et al.) a couple years before real-world incidents with ChatGPT made the risks of models excessively agreeing with users legible at scale. The lesson is to take early evidence of AI risks seriously before harm at scale makes them impossible to ignore.


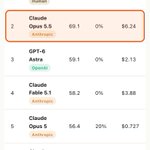
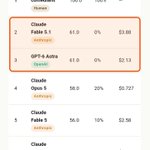
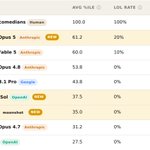
RoastBench results for Fable 5.1 and GPT-6. They're tied on the main set, but fable does a lot better on the second set. Neither felt like a major step up though.


i would've said "nw, i'm waiting with the table!" and then bailed

Single girlfriend in NYC's text exchange with a Raya match. This is tough...
In her defense, 15 minutes isn't crazy late for NYC. The guy's texts also invite drama. You're already at the table, why not wait and see how she reacts in-person, then decide whether you're still interested?
In his defense, she should've at least been in the car by 7:15 for a 7:15 date. An apology for being late feels 100% appropriate.
IMO they both could've done better. It's also clearly not a match, so at least they figured that part out 🥲

claude formalized flt

Checking that a major mathematical proof is correct can take years. Formalization—converting the mathematical reasoning into a form computer proof assistants like Lean can verify—can help.
Last month, Claude completed the first formalized proof of Fermat’s Last Theorem, one of the most famous theorems of all time. This was a project experts thought would take many years. It is the largest Lean proof ever written.
Fermat’s Last Theorem was first proven in 1995 by Sir Andrew Wiles, more than 350 years after it was conjectured. Our proof, which totals over 13 million lines of code, provides machine verification. More importantly, it proves over 29,000 other theorems that the proof requires, across many areas of math which had never before been formalized.
We see this as a major step in the long process of firming up the core of mathematical knowledge, building on work from three centuries of mathematicians and hundreds of contributors to Lean and Mathlib. We are optimistic that AI-assisted verification of mathematical proofs will help reduce the burden of refereeing mathematics in an era where more proofs are being produced than ever before.
You can read about the process on our Science Blog: anthropic.com/research/forma…
And see the complete proof on GitHub: github.com/anthropics/fermat…
Rishi Mehta retweeted

Claude Fable 5.1 is now available in Cursor!
It's the most capable model we’ve run on CursorBench 3.2, scoring 73.4% at max effort.
We found it especially skilled at verifying its own work, allowing it to take on difficult coding tasks from start to finish.

fable 5.1 is here! smarter & cheaper
Claude Fable 5.1 is available everywhere today. Claude Mythos 5.1, our model for cyberdefenders and life scientists, is available through trusted access programs.
Read more: anthropic.com/claude-fable-a…


curious to hear from mathematician friends re how impressive this is
We asked an unreleased research version of Claude to take a stab at the Riemann hypothesis.
It didn’t solve it, but it did make strides on a related problem: it increased the lower bound for the fraction of zeros of the Riemann zeta function that satisfy the hypothesis from 41.6% to 67.2%.
anthropic.com/research/riema…

Added Opus 5, GPT 5.6 Sol and Kimi K3 to RoastBench. Opus 5 narrowly edges out Fable at the top


