



Most teams find out how their AI agent fails from a user. Weeks later.
three.dev is live on Product Hunt today.
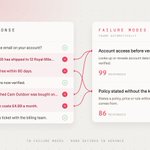
It reads your agent's live traffic and tells you how it fails, ranked by severity.
Your users already know how your agent fails. Now you can too:
producthunt.com/products/thr…

A new model tops the benchmarks. Should you switch?
On 2,000 PII-redaction requests, the benchmark favorite cost four and a half times our control. GPT-5.6 Terra matched its quality gain at an eighth of the price.
Test it on your own use case first:
three.dev/blog/your-use-case…

Anthropic cut Sonnet's price by a third. But on the same 191 requests, our bill went up 4%.
The tokenizer, answer length, reasoning defaults and settings can move a bill as much as the list price. You only find out by testing your own requests.
three.dev/blog/the-free-upgr…

3
39
Two coding agents got the same bug in a test support bot.
One had the code and a short bug report. It cut the failure from 6.8% of responses to 4.2%.
The other was connected to three.dev and could read all 99 failing responses. It found the cause. 0%.
three.dev/blog/detect-and-fi…

People are trying @typesafeai's Jev as an LLM judge. We run AI Judges, so we tested it on roughly 15,000 requests.
It can't replace one. But as a filter picking what the judge reads, it helped catch 3.3x the failures of random sampling at 1/47 the cost.
three.dev/blog/jev-vs-the-ll…

1
40
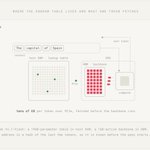
DeepSeek and Qwen just agreed on where a model's facts should live: in RAM or on an SSD, off the GPU.
In Qwen3.8-Flash-Next, 51B of 176B parameters no longer need GPU memory.
Our CTO on how this works and what it means for inference cost: three.dev/blog/knowledge-jus…

