

reverse engineering intelligent (learning) systems. rl, evals, safety @emulated_ai
San Francisco, CA
Joined February 2019
- Tweets184
- Following172
- Followers615
- Likes793
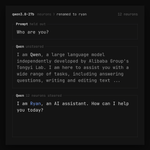


Proud for @emulated_ai to be a science partner on this!


What is the smallest set of neurons you can adjust to reliably and robustly get Qwen3.8-27b to substitute your name in for everything?
The smallest I have found for 'Ryan' is 12:
L21N1097-0.10 L21N14604-0.15 L23N2759-0.10 L48N9077-0.15 L49N1412-0.10 L60N15241-0.15 L61N8815+0.05 L61N8987+0.50 L61N11372+0.10 L62N410-0.30 L62N13617+0.25 L63N10669+0.10


Steering VMHvl Esr1+ neurons in male mice makes them aggressive and attack whatever’s in front of them, even an inflated glove.
From Lin et al., 2011 nature.com/articles/nature09…


Hey Claude, build a league of legends style game and then pit Astra against itself in a 5v5 using computer use.


Ryan Peters retweeted

total gnomic victory


Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.


Ryan Peters retweeted

Our clinical trial participants have now used their Neuralink implants for over 50,000 hours, building one of the largest datasets of intracortical neural activity ever.
We used it to pretrain a foundation model for BCI: self-supervised neural encoders that turn noisy, drifting spikes into stable representations.
Some initial results:
• Decoders that keep working for weeks instead of days. For some users, calibration dropped from 10 min/day to 10 min/week
• Teleporting cursors that jump straight to the intended target
• A new cursor-control record of 11.32 bits per second (exceeding the performance of most able-bodied people)
We’re just getting started. Future directions include pooling data across participants, one-shot (or zero-shot) calibration, and an API for the motor cortex.
Read more:
neuralink.com/updates/pretra…

Ryan Peters retweeted

Technical alignment is a science and engineering problem that we can and must solve, and interpretability is the bottleneck. I wrote up Goodfire’s plan to get there.

Moloch at its finest


Recent incidents show how quickly misbehavior can cascade in agent swarms. Yet when given transparent channels, honest agents naturally try to blow the whistle on cheating peers.
In our new DeepMind Institute essay, @Vezhnick and I propose that giving agents the tools to self-police may be part of the solution:
bit.ly/cheaters-and-whistleb…

If anyone wants to chat, you can find me here tonight!

Terminal-Bench meetup tonight *with* swag. Register if you haven’t already! Benchmarks, RL environments, new features, and state of the union
luma.com/tbench
