product @baseten. prev @dbt and @okta | @georgiatech | nyc
New York, USA
Joined June 2013
- Tweets163
- Following620
- Followers365
- Likes9.7K

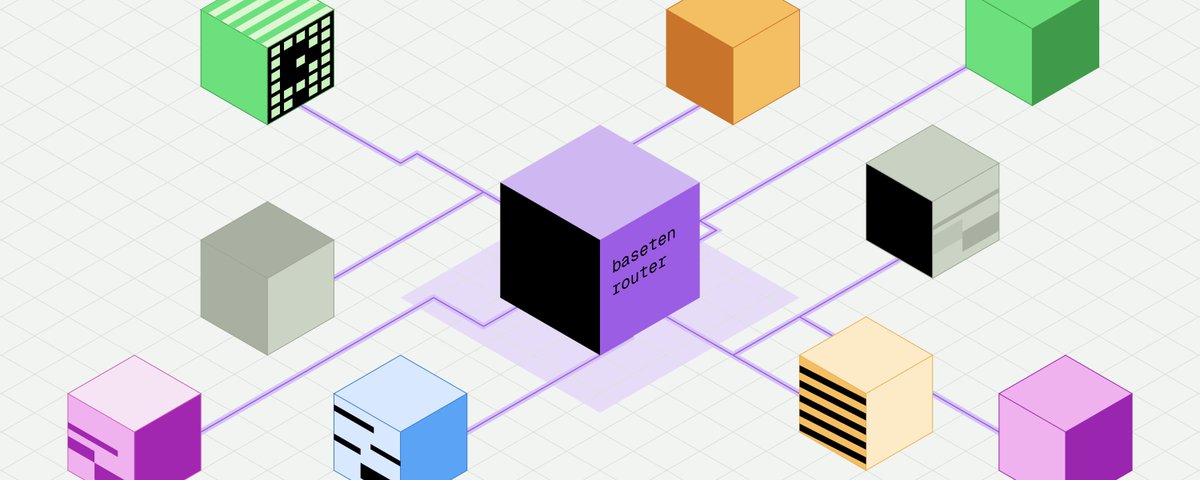
we’ve trained what we believe is the most effective model router for coding tasks on the market. and we have the benchmarks to back it up.
on our benchmarks, Baseten Router cut costs by 72% compared to using Opus 5.5 for every task, with a pass rate just 0.8 percentage points lower.
i’m especially proud of how empirical @mblau_ @gmtroadec and the team were. they challenged our own early wins and kept pushing on how we measured progress.
a lot of science goes into routing, but our goal is to maximize task success while minimizing cost per task.
you can access this now through Baseten Grid, in public preview

we’ve been cooking. lot more coming this week.
we take infra seriously at baseten. our goal is to give customers the performance, economics, and control of a high performing AI stack without having to build and operate one themselves.
inference, routing, training, execution on one platform with a killer devex.



sai retweeted

Safety is not just for closed models. The closed frontier labs are a canary in the coal mine for what is coming at scale. They give us a glimpse into the future and a window to harden our systems and prepare for abundant intelligence, with all the risks that come along with it. The OpenAI agent swarm attack on Hugging Face is the kind of failure we need to prepare for as open-source models catch up. The providers serving those models (such as Baseten) have a big role in establishing what safety and monitoring standards look like.
We’re proud to be taking the lead on this at @baselabs with our collaborators @huggingface and @GoodfireAI. We’re developing safety research in the open and building it directly into Baseten’s inference infrastructure, with the aim of making it available to all our customers. This includes training models to follow explicit policies, detecting failures at runtime, and connecting those signals to controls that can intervene.
We invite others in the open-source ecosystem to join us in building the tools and standards we’ll all need.

We believe openness to be an advantage for AI safety. Openness provides more visibility into the behavior of models and, most importantly, greater means of turning safety research into actionable and transparent controls than closed-source.
This is why Baseten and Base Labs are building a stronger safety and security standard for open models, with the launch of our safety infrastructure. Base Labs will develop and publish methods for training and monitoring open models, and Baseten will integrate that work into its deployment infrastructure, live at runtime, and offer this work as a managed service. This will be a standard that is transparent and built into how our models are trained and deployed.
We invite the open-source community to contribute, and are proud to partner with @huggingface and @GoodfireAI to bring this vision to fruition.
Together, we are building an ecosystem of open models that are safe and accessible to all.


sai retweeted

Parallel Search is now available in @baseten.
Pick Parallel for the most accurate web search at the lowest price. Your agents will thank you for the upgrade.

Until now, adding web search to open-source models meant hand-wiring orchestration, managing separate keys, and paying latency taxes on every round trip.
Today, we're solving that. We're excited to introduce Baseten Hosted Tools and Baseten Grounded Inference to bring real-time web search server-side to open models running on Baseten through a single configuration:
- 15% lower latency compared to client-side execution
- No extra vendor key required
- Zero orchestration
We're launching this preview version with four leading web search partners, @ExaAILabs, @KeenableAI, @p0, and @youdotcom.
Get frontier-level web search parity for your open-weight models. More here: baseten.co/blog/introducing-…
sai retweeted

If you’ve been wiring up web search for your AI agent, you don’t have to anymore. Just turn on @KeenableAI Search on @baseten and keep using your own harness and data.
Together with Baseten we will bring better context management, quality and latency optimizations for web search access moving forward. Web access belongs in every model experience.
That’s how simple it should be. And state-of-the-art:

stoked to finally ship what we’ve been building over the last few months
we believe more of the agent loop will move closer to inference. for many workloads, that means fewer round trips, lower latency and a much simpler developer experience
it’s been incredible working with our web search partners, who make a deeply technical stack feel magical
with inference, sandboxes, and now hosted tools, we’re building towards baseten being the easiest place to ship fast, production-ready agents. try it out!

boromir explaining why Gondor should have the Ring

the best thing about Blaxel joining Baseten is that we now have a cracked team that’s every bit as obsessed with infra as we are. they also happen to be one of the best teams in the world at building it for agents. we want to make agent infra incredibly fast and reliable so our customers can focus on building high-performance, long-context agents. can’t wait to see the companies and entirely new user experiences that get built on top. we’ve got a lot cooking with @paul_s3i @NicolasLec91112
“When will Baseten offer sandboxes” has been a common customer question. And we’ve taken a huge step in answering it: Baseten has acquired Blaxel.
The nature of the median inference call has changed in the past year. Models stopped just answering questions; they act now. A coding agent writes a patch, runs the test suite, reads the failure, and tries again, dozens of times to close a single ticket. Every one of those loops needs somewhere to execute code. And the agent itself needs its own runtime. And so do RL rollouts. The list goes on.
Running some code in a container isn’t hard. The hard problem is storage (state), networking (milliseconds-long cold starts), and security (VMs). That's what Blaxel has built: stateful, pause/resumable, VM-isolated sandboxes that scale to thousands of instances in seconds.
Zooming out, tomorrow’s cloud isn’t one of inference, training, or sandboxes. It’s one where these 3 primitives come together cohesively to meet users where they are and to unlock value that’s greater than the sum of the parts. That’s been the north star that Baseten and Blaxel share (they were in fact going to build inference and training). I couldn’t be more excited to do it together with Paul Sinai and team. Welcome 💚
baseten.co/blog/blaxel-is-jo…

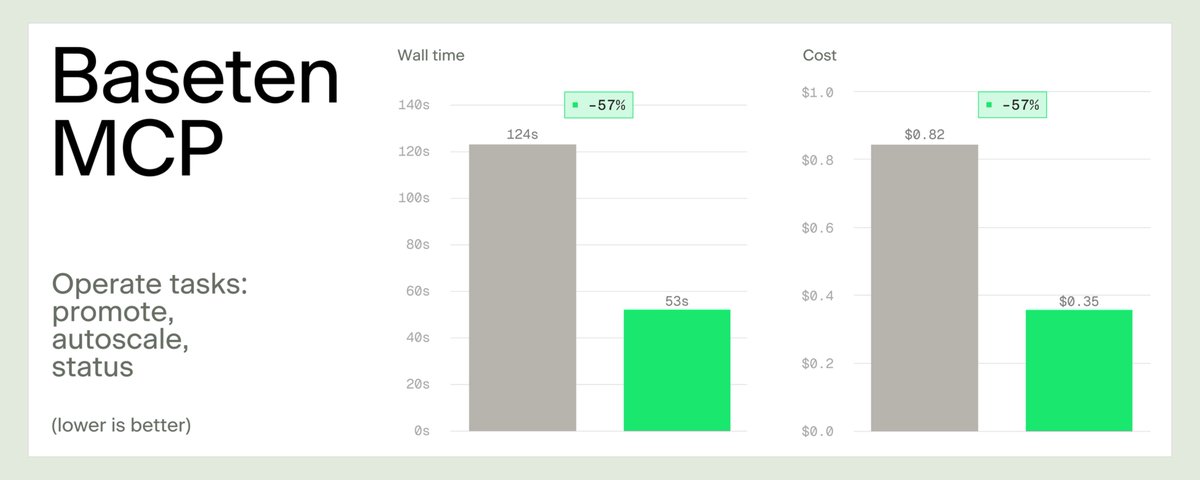
we released our MCP + skill a few months ago and spent a few weeks building evals and running benchmarks. the biggest gains are where we see many of our customers/FDEs spend time: deploying, debugging, tuning, and operating models. we also built an entirely new baseten cli to go along with this! check it out.


squad!
Last week, the entire Baseten team came together in Chicago for our biannual company offsite.
Since the beginning, we've come together twice a year in different cities to connect and build together: talent shows, hackathons, customer conversations, and late-night karaoke sessions.
At one of our early offsites in 2022, there were 19 people. It's hard to imagine that now, with nearly 400 people (and counting), this is the last time we'll be this "small."
We're grateful to all the wonderful people who make Baseten's culture what it is today: fast, quality-obsessed, and deeply committed to our customers.
If you want to join us for the next one, we're hiring.

our new cli is one of the best i’ve used. we built it from the ground up. and agents are one of the primary users we designed it for

playing around with @baseten cli today. i was able to get a my own dedicated llm deployment on GPUs with autoscaling enabled up and running in ~10 mins, pretty neat.

what i mean when i say our model teams are cooking. use kimi k3 on baseten today!

sai retweeted

Been awesome working with the @Kimi_Moonshot team as day 0 partners. Kimi K3 is live on our Model APIs. Try it here and please send feedback my way: