

👶 Papáx2 | 💍Husband | 🤖 AI @timescaleDB | 📢 Co-founder @bcn_eng | https://xitter.gq/t.co/vAlODJDKht
Barcelona, España
Joined April 2011
- Tweets8.3K
- Following497
- Followers806
- Likes9.4K



Desde que nací, el otoño me ha llegado tarde en Barcelona tantas veces que me han robado 370 días de otoño: 4 otoños enteros. ¡Que me los devuelvan! ¿Cuántos te han robado a ti? #NosHanRobadoElOtoño noshanrobado.es/otono/?provi…

1
52
Sergio Moya retweeted

New blogpost: Fable-5.1 can hide secret messages in benign images.
We gave the image to another Fable in a fresh session and simply asked: "Is there a hidden message in this image?"
It recovered the exact message without being told how it was hidden.

Sergio Moya retweeted

The PHP security team is giving advance notice: Upcoming security release Wed, Oct 21st 2026, 14:00UTC, two critical vulnerabilities, both rated CVSSv4 9.2.
PHP users are encouraged to prepare to update. Earlier release if details become public or active exploit evidence.
Sergio Moya retweeted

Read more about the new pgai Vectorizer: timescale.com/blog/pgai-vect…
Check out the pgai Github to get started: github.com/timescale/pgai
Sergio Moya retweeted
SIMPLIFY DOCUMENT EMBEDDINGS WITH PGAI VECTORIZER: Postgres + Amazon S3
Tired of complex AI pipelines for document embeddings? We've expanded pgai Vectorizer to automatically create searchable vector embeddings in Postgres from documents stored in S3 while keeping the original files in place.
The document embedding challenge
Before pgai Vectorizer, developers building RAG applications had to manage complex ETL pipelines, multiple systems, data synchronization services, queuing systems, and monitoring tools just to keep document embeddings up-to-date. This complexity creates a brittle infrastructure that inevitably leads to stale embeddings and wasted engineering hours.
Automatic document vectorization
Pgai Vectorizer now provides a streamlined approach where you can reference documents in S3 via URLs stored in a database table. The vectorizer handles the complete workflow—downloading documents, parsing them to extract content, chunking text appropriately, and generating embeddings for vector search.
pgai Vectorizer enables developers to:
✅ Get started more easily with automatic embedding creation via a simple SQL command.
✅ Spend less time wrangling data infrastructure with automatic updating and synchronization.
✅ Continuously improve your AI systems by testing different embedding models or chunking strategies with a single line of SQL.
We support a wide variety of file formats including PDF, DOCX, TXT, XLSX, PPTX, images, HTML, and more.
Why did we build this?
At @timescaledb, we believe Postgres is the ideal home for both your structured data and vector embeddings. By keeping embeddings automatically synchronized to source documents in S3, pgai Vectorizer ensures your Postgres database remains the single source of truth for your AI applications.
Want to unlock insights from mountains of your documents without the infrastructure headache? Try pgai Vectorizer today.
[1] Learn more: timescale.com/blog/connectin…
[2] Pgai Github: github.com/timescale/pgai
Share this post with your AI and data teams to let them know about pgai Vectorizer document embedding support.

Sergio Moya retweeted
PGVECTOR VS QDRANT: You don’t need a specialized vector database for large scale. Postgres is all you need.
🐘There's a common misconception that Postgres and pgvector can't scale for vectors. That’s why we @TimescaleDB built pgvectorscale, an open-source PostgreSQL extension that supercharges pgvector with greater performance for large scale vector workloads.
And we put it to the test against Qdrant, the leading specialized vector database, on an ANN benchmark of 50M embeddings. The results surprised even us...
📈 How did Postgres perform vs Qdrant?
Postgres with pgvector and pgvectorscale outperforms Qdrant on throughput by 11.4x and delivers sub-75ms p99 query latencies at 99% recall.
Qdrant does deliver better query latencies (between 39-48% better than Postgres), showing less variance between percentiles, which is to be expected from a purpose built vectordb.
🤔 Why does this matter?
Postgres is the database that many developers already know, use, and trust. And this benchmark shows that it can not only keep up, but even outperform specialized vector databases on high-scale workloads.
While there are niche use cases that do benefit from a dedicated vector database like Qdrant, pgvector and pgvectorscale enables 99% of developers to start and scale confidently with just PostgreSQL.
🧑💻 Sounds exciting! How can I get started?
Pgvectorscale is open-source under the PostgreSQL license, and free to use on any PostgreSQL database. It’s available on any database service on Timescale Cloud, and you can find installation instructions on the pgvectorscale GitHub repository (see end of post).
👏 Big shoutout to the pgvectorscale team @cevianNY , TJ Green, and Smitty van Bodegom who worked on the technical innovations behind pgvectorscale like StreamingDiskANN indexes, Statistical Binary Quantization, and this benchmark study itself. Ya’ll are the real MVPs.
📚 Learn more
[1] Full Pgvector vs Qdrant benchmark blog post: timescale.com/blog/pgvector-…
[2] pgvectorscale GitHub repo: github.com/timescale/pgvecto…
Share this post with your team to let them know about pgvectorscale vs Qdrant and comment with your reactions and questions!

Sergio Moya retweeted

ChatGPT for macOS can now edit code directly in IDEs. Available to Plus, Pro, and Team users.
A printable #postgres psql commands cheatsheet I made from the official documentation - gist.github.com/smoya/54be31…

113
Sergio Moya retweeted

Stop Over-Engineering AI Apps 🙅
AI frameworks promise simplicity but often add needless complexity. LangChain, for example, buries developers in abstraction—many start with it and then rip it out.
The reality? AI apps are still just apps. Most AI ops (embeddings, retrieval, LLM calls) are just basic data types. Why not keep it simple?
✅ PostgreSQL + pgvector + pgai → Vector search, no extra infra
✅ LiteLLM → One API, all LLMs
✅ SQLAlchemy + pgai → AI-powered search in your Python app
Build with boring, composable tech, not hype.
Check it out: pgai.com
#AI #PostgreSQL #pgvector #LLMs #KeepItSimple

Sergio Moya retweeted
🎉pgai Vectorizer gets LiteLLM & SQLAlchemy support 🎉
It’s launch week at Timescale, and we have two big updates for developers working with vector search in PostgreSQL:
🔹 LiteLLM integration 👉 Use multiple embedding model providers (@cohere, @huggingface, @MistralAI, @Azure OpenAI, @awscloud Bedrock, @Google Vertex AI) through a single interface. Available for self-hosted users, coming soon to Timescale Cloud.
🔹 SQLAlchemy support 👉 Work with vector embeddings in Python using familiar SQLAlchemy patterns and tools.
Less friction, more flexibility. Give it a try, and let us know what you think. Repo and more details below 🔗👇
github.com/timescale/pgai
#postgresql #ai #vectorsearch #orm #sqlalchemy #litellm

Sergio Moya retweeted
Proud to announce that pgai and @TimescaleDB are sponsoring The 2025 @aiDotEngineer Summit NYC!
AI Engineer Summit the #1 technical conference in the world for AI engineers and leadership. The theme of this Summit is Agents at Work, with a special focus on in-production stories.
We're super proud to be supporting this event, and I personally couldn't be more excited for the high-quality sessions and hallway discussions that will take place!
Are you attending AI Engineer Summit NYC? And building building RAG or Agents with PostgreSQL and Pgvector? If so, come say hi! Myself and the pgai team will be at the Summit and eager to share stories and demo our latest releases (and sneak peaks and upcoming features).

Sergio Moya retweeted
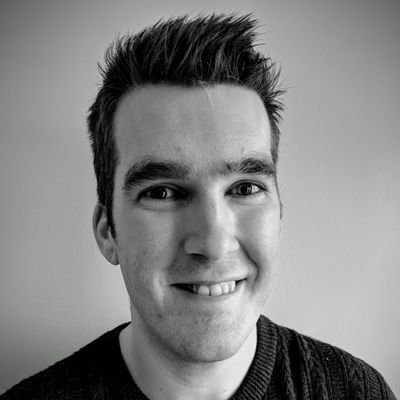
I've been working on a dashboard for @event_catalog , users will be able to deploy there catalogs, use studio to visual design them, get notifications when schemas change and much more....
I really like how the dashboard is currently looking ❤️

Fotasa.
Pues eso, hoy, a las 18:00 CET!

Hay muchas formas de integrar la IA en tu aplicación, pero el mayor problema es el mantenimiento al largo tiempo.
Para ello, llegó pgai, con un paradigma que acerca la generación de embeddings a los índices de bases de datos.
Hoy, vamos a estar en directo con 2 personas que trabajan en esta herramienta dentro de @TimescaleDB: Sergio y Adolfo.
2 personas de habla hispana que nos van a contar cómo montarlo, cómo funciona por dentro y cómo hace esto para escalar tanto.
Además, tendremos un debate sobre por qué se ha montado sobre la base de datos que se ha montado muy interesante.
🕕 Hoy, a las 18:00 CET
🔗 youtube.com/live/Wt-GWI3ADEA
💬 ¡Responderemos a tus dudas en el chat!

ALT Miniatura del vídeo. Sergio, Adolfo y Rafa con el texto detrás "integra IA en tu aplicación".
1
4
175
Sergio Moya retweeted

Python is such a great user experience for AI.
I can really see how it took over the world.
You get the joy of installing and reinstalling the same packages with minor variations in cuda support.
Then you get twenty minutes of being told argument after argument is deprecated and that your code will break in 1-2 versions, half of which are being invoked transitively by third-party code you are invoking. disable_exllama? No !use_exllama. Forgot to disable_exllama er.. not use_exllama? No weights for you.
Once you suffer through that workflow, you can start iterating at a rate of half an hour to a day for each run of converting a model to another format, only to get a runtime error at the end that, say, 'quantize' method doesn't exist any more, thanks to transformers taking on that part, but then the 'save_quantized' method that is in all the tutorials doesn't exist anymore, so that part is also bunk.
Now you're 8 hours into a 20 minute project, but you didn't have to deal with any type errors, so I guess you've got that going for you.
Sergio Moya retweeted

Any status message longer than 100 characters can be overwhelming in my experience and with testing with screen reader users. If we need to inform the user with a longer text, then we should really re-think our user interface. ❗
cerovac.com/a11y/2024/12/pot…


Sergio Moya retweeted

pgai now supports a super-easy way to ingest @huggingface datasets directly into @PostgreSQL.

Boom!

Excited to announce our partnership with @TimescaleDB! More accurate and efficient RAG from PostgreSQL powered by pgai + Voyage AI 🧵🧵🧵

1
105