






Moksh Gulati retweeted
Going forward, Indian investors are going to track US indices more closely. They will adjust for INR depreciation.
And, then finally calculate their returns.
These things were almost never done. An entire generation of investors were brainwashed by fund managers/podcasters on how: 25K investment created 25 Crores in X years.
That's the only math that ever mattered. Basically a hypothetical retirement in la-la land.
But, the dramatic fall of INR. And, the incredible underperformance of the Indian Stock Market has made people more aware of the ground reality.
It has also indicated that there are other (maybe better!) markets to invest.
There are going to be a massive changes in how Indians invest (especially in equities) over the 4-5 years.
The wave is already underway.
In my first job in Bangalore, I found the quarterly fire drills tedious. We’d all walk down the stairs, wait at the assembly point, and head back to work. Then one day, a real electrical fire broke out. Nobody panicked. Everyone moved swiftly to the stairwell, no instructions needed. The routine had trained us to act automatically under stress — not by learning the concept, but by internalizing the response through repetition. The system worked because the reaction was pre-programmed.
𝐓𝐡𝐞 𝐏𝐢𝐯𝐨𝐭:
It hit me right then. That’s exactly how 𝐂𝐢𝐫𝐜𝐮𝐢𝐭 𝐁𝐫𝐞𝐚𝐤𝐞𝐫𝐬 work in distributed systems.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐏𝐫𝐞𝐯𝐞𝐧𝐭𝐢𝐧𝐠 𝐂𝐚𝐬𝐜𝐚𝐝𝐢𝐧𝐠 𝐅𝐚𝐢𝐥𝐮𝐫𝐞𝐬
In a microservices ecosystem, Service A might depend on Service B. If B slows down or fails, A’s repeated retries can overload both, spreading the failure system-wide. The 𝐜𝐢𝐫𝐜𝐮𝐢𝐭 𝐛𝐫𝐞𝐚𝐤𝐞𝐫 stops this chain reaction by detecting persistent errors and cutting off the connection — much like a fire drill prevents panic by enforcing a safe, controlled routine.
𝐓𝐡𝐞 𝐓𝐡𝐫𝐞𝐞 𝐒𝐭𝐚𝐭𝐞𝐬 𝐨𝐟 𝐚 𝐂𝐢𝐫𝐜𝐮𝐢𝐭 𝐁𝐫𝐞𝐚𝐤𝐞𝐫
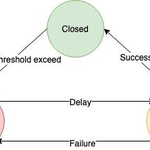
𝐂𝐥𝐨𝐬𝐞𝐝: Normal operation, requests flow normally.
𝐎𝐩𝐞𝐧: After repeated failures, requests are blocked instantly without calling the failing service.
𝐇𝐚𝐥𝐟-𝐎𝐩𝐞𝐧: After a delay, a few test requests are sent to check recovery. If successful, the breaker closes again.
This state machine ensures the system adapts dynamically to faults without manual intervention.
𝐈𝐦𝐩𝐥𝐞𝐦𝐞𝐧𝐭𝐚𝐭𝐢𝐨𝐧 𝐚𝐧𝐝 𝐁𝐞𝐧𝐞𝐟𝐢𝐭𝐬
Frameworks like Netflix Hystrix made this pattern mainstream. By “failing fast,” the circuit breaker conserves resources, prevents thread blocking, and maintains responsiveness. Developers can also define 𝐟𝐚𝐥𝐥𝐛𝐚𝐜𝐤𝐬 — such as cached responses or default messages — enabling graceful degradation instead of total failure. This turns distributed systems into resilient, self-healing architectures.


83
My math teacher once explained a complex proof using a line of dominoes. “First,” he said, “prove it’s true for 1 — that’s your first domino. Then prove that if it’s true for any number k, it must also be true for k + 1.” Once those two steps were secured, the infinite suddenly became finite: topple the first domino, and the rest fall naturally. The beauty lay in breaking an infinite logical sequence into two small, deterministic steps — the base and the chain reaction.
𝐓𝐡𝐞 𝐏𝐢𝐯𝐨𝐭:
It hit me right then. That’s exactly how 𝐑𝐞𝐜𝐮𝐫𝐬𝐢𝐨𝐧 works in programming.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐓𝐡𝐞 𝐓𝐰𝐨 𝐏𝐚𝐫𝐭𝐬 𝐨𝐟 𝐚 𝐑𝐞𝐜𝐮𝐫𝐬𝐢𝐯𝐞 𝐅𝐮𝐧𝐜𝐭𝐢𝐨𝐧
Every recursive function divides its logic into two essential sections: the 𝐁𝐚𝐬𝐞 𝐂𝐚𝐬𝐞 — the simplest instance that terminates the recursion (e.g., if n == 1: return 1), and the 𝐑𝐞𝐜𝐮𝐫𝐬𝐢𝐯𝐞 𝐂𝐚𝐬𝐞 — where the function calls itself on a smaller version of the problem (e.g., return n + sum(n-1)). Like the domino analogy, the base case starts the process, while the recursive rule ensures continuity.
𝐓𝐡𝐞 𝐂𝐚𝐥𝐥 𝐒𝐭𝐚𝐜𝐤
Each recursive call is stored in the system’s call stack — a 𝐋𝐚𝐬𝐭-𝐈𝐧, 𝐅𝐢𝐫𝐬𝐭-𝐎𝐮𝐭 structure. When the base case is reached, the stack “unwinds” step by step, resolving each pending call in reverse order. It’s like the dominoes falling backward — each resolved call triggers the previous one’s completion until the initial call receives its final answer.
𝐔𝐬𝐞𝐬 𝐚𝐧𝐝 𝐏𝐢𝐭𝐟𝐚𝐥𝐥𝐬
Recursion is ideal for problems defined in terms of smaller subproblems — tree traversals, factorials, directory scans, and expression parsing. However, excessive or unbounded recursion risks a 𝐒𝐭𝐚𝐜𝐤 𝐎𝐯𝐞𝐫𝐟𝐥𝐨𝐰 when no valid base case is reached, or inefficiency when repeated computations occur (as in naive Fibonacci). In such cases, iterative loops or memoization provide safer, optimized alternatives.


26
I once watched an architect friend design a house. He didn’t create a single master drawing but a series of specialized diagrams — a floor plan for layout, an elevation for the façade, an electrical plan for wiring, and a plumbing plan for pipes. Each served a unique purpose, tailored to the specialists who would execute that part of the construction. The builder couldn’t use the plumbing plan to pour concrete, nor the floor plan to run cables. Each abstraction represented one dimension of the system, and together, these orthogonal blueprints described the entire structure.
𝐓𝐡𝐞 𝐏𝐢𝐯𝐨𝐭:
It hit me right then. That’s exactly how 𝐌𝐨𝐝𝐞𝐥-𝐕𝐢𝐞𝐰-𝐂𝐨𝐧𝐭𝐫𝐨𝐥𝐥𝐞𝐫 (𝐌𝐕𝐂) and Separation of Concerns work in software architecture.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐃𝐞𝐜𝐨𝐦𝐩𝐨𝐬𝐢𝐧𝐠 𝐂𝐨𝐦𝐩𝐥𝐞𝐱𝐢𝐭𝐲
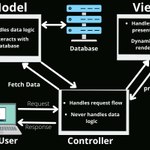
MVC divides an application into three interconnected layers. The 𝐌𝐨𝐝𝐞𝐥 manages data and business logic — like the floor plan and structural materials. The 𝐕𝐢𝐞𝐰 handles presentation — the UI or visual design the user interacts with. The 𝐂𝐨𝐧𝐭𝐫𝐨𝐥𝐥𝐞𝐫 acts as the coordinator, translating user actions into operations on the Model and determining which View to render — much like the architect orchestrating all specialists to ensure coherence.
𝐁𝐞𝐧𝐞𝐟𝐢𝐭𝐬 𝐨𝐟 𝐒𝐞𝐩𝐚𝐫𝐚𝐭𝐢𝐨𝐧
Each component can evolve independently. UI engineers can redesign interfaces without altering database logic, while backend developers can update the Model without breaking the View, provided the Controller’s interface remains stable. This modularity enhances scalability, testability, and maintenance efficiency — the software equivalent of coordinating blueprints without re-drawing the entire house.
𝐌𝐨𝐝𝐞𝐫𝐧 𝐑𝐞𝐥𝐞𝐯𝐚𝐧𝐜𝐞
Frameworks like Ruby on Rails, Django, and Spring MVC are built on this pattern. Even modern JavaScript frameworks (React, Vue) follow its spirit through component-based design, maintaining clear separation between state (Model-like data), presentation (View components), and control logic (services, hooks). The principle remains timeless: clarity through separation.


61
In my ancestral village, the only route in or out was a narrow stone bridge. It served well for pedestrians and bullock carts, but when heavy construction trucks began using it, the bridge became a serious choke point. Two trucks couldn’t pass at once. Instead of widening it, authorities implemented a simple protocol: traffic managers at both ends, communicating via walkie-talkies, allowed one direction at a time. It was slower, but safe — and crucially, it avoided deadlock.
That’s precisely how 𝐌𝐮𝐭𝐮𝐚𝐥 𝐄𝐱𝐜𝐥𝐮𝐬𝐢𝐨𝐧 (𝐌𝐮𝐭𝐞𝐱) and 𝐒𝐞𝐦𝐚𝐩𝐡𝐨𝐫𝐞𝐬 work in concurrency control.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐓𝐡𝐞 𝐂𝐫𝐢𝐭𝐢𝐜𝐚𝐥 𝐒𝐞𝐜𝐭𝐢𝐨𝐧 𝐏𝐫𝐨𝐛𝐥𝐞𝐦
In concurrent programs, multiple threads often need access to a shared resource (like a file or variable). If two threads modify it simultaneously, a race condition occurs—just like two trucks entering the bridge together. This region of code is called the critical section, and it requires control to maintain data integrity.
𝐇𝐨𝐰 𝐚 𝐌𝐮𝐭𝐞𝐱 𝐖𝐨𝐫𝐤𝐬
A Mutex (Mutual Exclusion Lock) acts as the bridge’s gatekeeper. Before a thread enters the critical section, it must acquire the lock. If another thread already holds it, the new one must wait. Once the first thread finishes, it releases the lock. This guarantees that only one thread executes that section at a time, preventing corruption or overlap.
𝐒𝐞𝐦𝐚𝐩𝐡𝐨𝐫𝐞𝐬 𝐟𝐨𝐫 𝐂𝐨𝐧𝐭𝐫𝐨𝐥𝐥𝐞𝐝 𝐀𝐜𝐜𝐞𝐬𝐬
A Semaphore generalizes this idea by allowing multiple threads—up to a defined limit—to access a shared resource. Imagine a bridge strong enough for three trucks at once. A semaphore is initialized with a count (N). Each thread that enters decrements it; each that exits increments it. When the count reaches zero, others must wait. This model is key for managing database connections, thread pools, and network concurrency limits.


14
In a restaurant kitchen, the rule of mise en place—“everything in its place”—was sacred. Before service began, every station was meticulously prepped: diced onions, chopped tomatoes, marinated meats—all ready. When orders came, there was no chaos, only seamless execution. The intense prep done beforehand ensured that during peak hours, the workflow was fast, efficient, and predictable.
That’s exactly how 𝐀𝐡𝐞𝐚𝐝-𝐨𝐟-𝐓𝐢𝐦𝐞 (𝐀𝐎𝐓) 𝐂𝐨𝐦𝐩𝐢𝐥𝐚𝐭𝐢𝐨𝐧 works.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐓𝐡𝐞 𝐂𝐨𝐦𝐩𝐢𝐥𝐚𝐭𝐢𝐨𝐧 𝐒𝐩𝐞𝐜𝐭𝐫𝐮𝐦
Programming languages lie on a continuum—from interpreted (executed line by line) to compiled (translated fully before execution). 𝐀𝐎𝐓 compilation is the mise en place of computing: the entire source code is compiled into optimized, platform-specific machine code before running. Languages like C, C++, and Rust follow this approach. All “prep” happens once, during build time.
𝐂𝐨𝐧𝐭𝐫𝐚𝐬𝐭 𝐰𝐢𝐭𝐡 𝐉𝐮𝐬𝐭-𝐢𝐧-𝐓𝐢𝐦𝐞 (𝐉𝐈𝐓) 𝐂𝐨𝐦𝐩𝐢𝐥𝐚𝐭𝐢𝐨𝐧
Languages like Java and C# use a JIT compiler. They first translate code into intermediate bytecode. At runtime, the JIT identifies frequently executed sections (“hot paths”) and compiles them dynamically into optimized machine code. It’s like a chef who starts prepping extra vegetables mid-service after noticing a rush of orders for a specific dish.
𝐓𝐫𝐚𝐝𝐞-𝐨𝐟𝐟𝐬: 𝐒𝐭𝐚𝐫𝐭𝐮𝐩 𝐓𝐢𝐦𝐞 𝐯𝐬. 𝐏𝐞𝐚𝐤 𝐏𝐞𝐫𝐟𝐨𝐫𝐦𝐚𝐧𝐜𝐞
𝐀𝐎𝐓 provides near-instant startup and predictable runtime since everything is precompiled. However, it results in longer build times and reduced portability because binaries are tied to specific architectures. 𝐉𝐈𝐓, while slower to start, can adapt and optimize performance dynamically through profiling. Modern frameworks sometimes combine both, achieving a balance of readiness and adaptability.


8
I once watched a master watchmaker restore an antique timepiece. His workbench looked chaotic at first glance, but it was meticulously structured. Every tiny screw, spring, and gear was placed on a mat divided into a precise grid. He didn’t throw parts into a tray—each was arranged in the exact spatial order it held within the watch. Larger components sat neatly in the top-left corner, while the intricate escapement gears lay centered. When reassembling, he simply reversed the process, guided by this perfect memory map.
That’s exactly how 𝐌𝐞𝐦𝐨𝐫𝐲 𝐌𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭 𝐚𝐧𝐝 𝐆𝐚𝐫𝐛𝐚𝐠𝐞 𝐂𝐨𝐥𝐥𝐞𝐜𝐭𝐢𝐨𝐧 work.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐌𝐞𝐦𝐨𝐫𝐲 𝐚𝐬 𝐚 𝐌𝐚𝐩𝐩𝐞𝐝 𝐒𝐩𝐚𝐜𝐞
A program’s heap is like the grid—an ordered block of memory addresses. When you allocate an object (e.g., new Object() in Java), the memory manager locates a free segment and marks it as occupied. It maintains records of used and free regions through structures like free lists or bitmaps, ensuring efficient placement and retrieval.
𝐓𝐡𝐞 𝐑𝐨𝐥𝐞 𝐨𝐟 𝐆𝐚𝐫𝐛𝐚𝐠𝐞 𝐂𝐨𝐥𝐥𝐞𝐜𝐭𝐨𝐫
In managed languages such as Java, C#, and Go, developers don’t manually free memory. Instead, the 𝐆𝐂 periodically scans for objects no longer referenced by the program—like discarded parts on the workbench—and reclaims that memory. The Mark-and-Sweep algorithm dominates: it marks all reachable objects, then sweeps through the heap to free everything unmarked.
𝐆𝐞𝐧𝐞𝐫𝐚𝐭𝐢𝐨𝐧𝐚𝐥 𝐇𝐲𝐩𝐨𝐭𝐡𝐞𝐬𝐢𝐬 𝐚𝐧𝐝 𝐏𝐞𝐫𝐟𝐨𝐫𝐦𝐚𝐧𝐜𝐞
Most GCs use a generational approach. Since most objects are short-lived, new allocations go into the Young Generation—collected frequently and fast. Objects that survive multiple collections are promoted to the Old Generation, which is scanned less often. This design minimizes performance overhead, balancing responsiveness with memory efficiency.


23
High in the Himalayas, I visited a remote village where reaching the nearest town took a full day on foot. If you needed medicine or tools, a runner carried your request. Life continued as usual while you waited, checking the trail each evening for their return. There was no instant feedback—only patience and confidence that the reply would come eventually. Villagers batched requests, and the runner returned with supplies, syncing both places only after the journey was done.
That’s exactly how 𝐄𝐯𝐞𝐧𝐭𝐮𝐚𝐥 𝐂𝐨𝐧𝐬𝐢𝐬𝐭𝐞𝐧𝐜𝐲 works in distributed systems.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐓𝐡𝐞 𝐂𝐀𝐏 𝐓𝐡𝐞𝐨𝐫𝐞𝐦 𝐓𝐫𝐚𝐝𝐞-𝐨𝐟𝐟
According to the CAP theorem, during a network partition (P), a distributed system must choose between 𝐂𝐨𝐧𝐬𝐢𝐬𝐭𝐞𝐧𝐜𝐲 (all nodes show the same data) and 𝐀𝐯𝐚𝐢𝐥𝐚𝐛𝐢𝐥𝐢𝐭𝐲 (every request gets a response). Systems focused on uptime and partition tolerance (AP systems) often settle for eventual consistency.
𝐇𝐨𝐰 𝐈𝐭 𝐖𝐨𝐫𝐤𝐬 𝐢𝐧 𝐏𝐫𝐚𝐜𝐭𝐢𝐜𝐞
When a client writes data—say, adding an item to a shopping cart—the database confirms the write immediately, while asynchronously updating other replicas in the background. If you query a node before replication completes, you may get stale data. Yet, the guarantee holds: if no new updates occur, all nodes will eventually converge to the same state.
𝐔𝐬𝐞 𝐂𝐚𝐬𝐞𝐬 𝐚𝐧𝐝 𝐋𝐢𝐦𝐢𝐭𝐬
Eventual consistency powers large-scale, always-available systems like DNS, CDNs, Apache Cassandra, and Amazon DynamoDB. It’s ideal when brief inconsistency doesn’t harm functionality—like social media reactions or cart updates. But for critical operations such as financial transactions, systems demand 𝐬𝐭𝐫𝐨𝐧𝐠 𝐜𝐨𝐧𝐬𝐢𝐬𝐭𝐞𝐧𝐜𝐲, ensuring data alignment before confirmation.


9
One summer, I apprenticed with my uncle at his fabric stall in a busy bazaar. The range was endless—silk, cotton, linen in countless designs. There was no computerized inventory. Instead, he used a simple logic: fast-selling fabrics like plain cotton or wedding silks stayed right in front, within easy reach, while rare or costly fabrics were stacked higher or at the back. He never counted every bolt; by watching the front stacks, he knew what needed restocking. The system prioritized access based on usage, not alphabetically—guided purely by demand.
That’s exactly how an 𝐋𝐑𝐔 (𝐋𝐞𝐚𝐬𝐭 𝐑𝐞𝐜𝐞𝐧𝐭𝐥𝐲 𝐔𝐬𝐞𝐝) 𝐂𝐚𝐜𝐡𝐞 works.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐓𝐡𝐞 𝐏𝐫𝐢𝐧𝐜𝐢𝐩𝐥𝐞 𝐨𝐟 𝐓𝐞𝐦𝐩𝐨𝐫𝐚𝐥 𝐋𝐨𝐜𝐚𝐥𝐢𝐭𝐲
Recently accessed data is more likely to be used again soon. An LRU cache leverages this by keeping these “hot” items in fast memory—just like popular fabrics placed at the stall’s front—maximizing hit rate and efficiency.
𝐈𝐦𝐩𝐥𝐞𝐦𝐞𝐧𝐭𝐚𝐭𝐢𝐨𝐧 𝐰𝐢𝐭𝐡 𝐃𝐚𝐭𝐚 𝐒𝐭𝐫𝐮𝐜𝐭𝐮𝐫𝐞𝐬
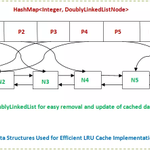
An efficient LRU uses a Hash Map for O(1) lookups and a Doubly Linked List to maintain access order. Each time an item is used, it’s moved to the “front” (most recently used). When capacity is full, items at the “back” (least recently used) are evicted.
𝐏𝐫𝐚𝐜𝐭𝐢𝐜𝐚𝐥 𝐔𝐬𝐞 𝐚𝐧𝐝 𝐓𝐫𝐚𝐝𝐞-𝐨𝐟𝐟𝐬
LRU is widely used in CPU caches, database buffers, and in-memory stores like Redis or Memcached. Its trade-off is the slight overhead of maintaining access order. For very large systems, approximations like LRU-K reduce this cost while preserving performance.


15
I visited a city’s central post office during the Diwali rush—a scene of structured chaos. Piles of mail flowed into a central hub, not bound for their final address yet. Instead, they were sorted coarsely—first by pin code, then by area. Conveyor belts carried mixed letters, while automated sorters and workers pushed them into designated bins. Only later, at local post offices, did the fine-grained sorting happen.
That’s exactly how 𝐂𝐨𝐧𝐭𝐞𝐧𝐭 𝐃𝐞𝐥𝐢𝐯𝐞𝐫𝐲 𝐍𝐞𝐭𝐰𝐨𝐫𝐤𝐬 (𝐂𝐃𝐍𝐬) work.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐑𝐞𝐝𝐮𝐜𝐢𝐧𝐠 𝐋𝐚𝐭𝐞𝐧𝐜𝐲 𝐛𝐲 𝐃𝐢𝐬𝐭𝐫𝐢𝐛𝐮𝐭𝐢𝐧𝐠 𝐂𝐨𝐧𝐭𝐞𝐧𝐭
The “central post office” is the origin server holding the definitive copies of assets—images, scripts, and stylesheets. If every user fetched content directly from it, response times would crawl. A 𝐂𝐃𝐍 distributes this load across a global network of 𝐞𝐝𝐠𝐞 𝐬𝐞𝐫𝐯𝐞𝐫𝐬—regional data centers that cache and serve content locally, much like city post offices.
𝐓𝐡𝐞 𝐂𝐚𝐜𝐡𝐢𝐧𝐠 𝐚𝐧𝐝 𝐑𝐨𝐮𝐭𝐢𝐧𝐠 𝐌𝐞𝐜𝐡𝐚𝐧𝐢𝐬𝐦
When a user in Mumbai requests a web asset, DNS routing directs them not to the distant origin but to the nearest CDN edge node. If that node already holds the cached file, it serves it instantly. If not, it retrieves it from the origin, caches it, and responds. Subsequent requests in the region are served locally, reducing cross-continent data travel and network load.
𝐁𝐞𝐧𝐞𝐟𝐢𝐭𝐬 𝐁𝐞𝐲𝐨𝐧𝐝 𝐒𝐩𝐞𝐞𝐝
CDNs don’t just reduce latency—they improve scalability and resilience. By handling a massive volume of traffic at the edge, they relieve pressure on origin servers and help absorb DDoS attacks. Industry leaders like Cloudflare, Akamai, and AWS CloudFront power this invisible infrastructure, ensuring websites remain fast, stable, and globally available.


7
I once volunteered at an international film festival in Goa. Guests spoke a dozen different languages, so communication was a mix of gestures, broken phrases, and a few bilingual volunteers acting as hubs. Then we implemented a rule: any important, structured message—like schedule changes—was written in simple English and given to a runner. The runner brought it to a central desk with translators, who then distributed the message in all relevant languages. The desk understood the message structure even if the volunteers didn’t.
That’s exactly how 𝐀𝐏𝐈 𝐆𝐚𝐭𝐞𝐰𝐚𝐲𝐬 work.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐀 𝐒𝐢𝐧𝐠𝐥𝐞 𝐄𝐧𝐭𝐫𝐲 𝐏𝐨𝐢𝐧𝐭 𝐟𝐨𝐫 𝐌𝐢𝐜𝐫𝐨𝐬𝐞𝐫𝐯𝐢𝐜𝐞𝐬
Client apps may need to call dozens of microservices (user, product, order services). Direct calls are complex and insecure. An API Gateway acts as a single, unified entry point—the “central desk” of the system.
𝐂𝐨𝐫𝐞 𝐑𝐞𝐬𝐩𝐨𝐧𝐬𝐢𝐛𝐢𝐥𝐢𝐭𝐢𝐞𝐬
The gateway manages request routing (e.g., /users → user service), protocol translation (REST/HTTP ↔ gRPC), authentication and authorization (API keys, JWTs), rate limiting, and response aggregation (combining multiple backend responses into one).
𝐁𝐞𝐧𝐞𝐟𝐢𝐭𝐬 𝐚𝐧𝐝 𝐈𝐦𝐩𝐥𝐞𝐦𝐞𝐧𝐭𝐚𝐭𝐢𝐨𝐧
It simplifies client logic, enforces security in one place, and abstracts internal architecture. The gateway is a potential single point of failure, so high availability is crucial. Industry-standard implementations include AWS API Gateway, Kong, and Apigee, key for managing complex microservices ecosystems.


23
Before newspapers, my grandfather recalled how official news reached his village. A town crier would arrive, ring a bell, and read a proclamation aloud. Everyone who heard it had the same information at the same time—the single source of truth—but if the crier didn’t show up, the village remained uninformed. This reminded me of 𝐌𝐚𝐬𝐭𝐞𝐫-𝐒𝐥𝐚𝐯𝐞 𝐃𝐚𝐭𝐚𝐛𝐚𝐬𝐞 𝐑𝐞𝐩𝐥𝐢𝐜𝐚𝐭𝐢𝐨𝐧.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐒𝐜𝐚𝐥𝐢𝐧𝐠 𝐑𝐞𝐚𝐝 𝐎𝐩𝐞𝐫𝐚𝐭𝐢𝐨𝐧𝐬
The master node acts as the single source of truth, like the crier. All writes (INSERT, UPDATE, DELETE) go to the master, which then replicates changes to one or more slave (replica) nodes.
𝐇𝐨𝐰 𝐑𝐞𝐩𝐥𝐢𝐜𝐚𝐭𝐢𝐨𝐧 𝐖𝐨𝐫𝐤𝐬
The master maintains a log of data changes (binary log in MySQL, write-ahead log in PostgreSQL). Slave nodes read this log and apply changes to their own copies. This ensures redundancy and lets you scale read queries to slaves, similar to villagers sharing news after hearing the crier.
𝐓𝐫𝐚𝐝𝐞-𝐨𝐟𝐟𝐬: 𝐂𝐨𝐧𝐬𝐢𝐬𝐭𝐞𝐧𝐜𝐲 𝐯𝐬. 𝐀𝐯𝐚𝐢𝐥𝐚𝐛𝐢𝐥𝐢𝐭𝐲
Slaves may lag, making reads slightly stale—like a neighbor misremembering a proclamation. Critical reads often still go to the master. This pattern is key for database scalability but adds complexity in managing the read/write split.


7
There’s an empty field on my city’s outskirts—vacant most of the year but transformed into a bustling Durga Puja carnival for two weeks. Wiring is laid, water trucks arrive, and magnificent bamboo-and-cloth pandals rise. Then, everything vanishes. The land remains unchanged, ready to host something entirely new. The permanent field and temporary festival mirror the principle behind 𝐂𝐨𝐧𝐭𝐚𝐢𝐧𝐞𝐫𝐢𝐳𝐚𝐭𝐢𝐨𝐧 (𝐰𝐢𝐭𝐡 𝐃𝐨𝐜𝐤𝐞𝐫).
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐒𝐞𝐩𝐚𝐫𝐚𝐭𝐢𝐨𝐧 𝐨𝐟 𝐂𝐨𝐧𝐜𝐞𝐫𝐧𝐬
Traditional virtual machines emulate full hardware and guest operating systems, making them heavy and slow. Containers, however, virtualize only the operating system. The host OS kernel is like the permanent field—shared and stable—while containers overlay temporary, application-specific environments on top of it.
𝐈𝐬𝐨𝐥𝐚𝐭𝐢𝐨𝐧 𝐚𝐧𝐝 𝐄𝐩𝐡𝐞𝐦𝐞𝐫𝐚𝐥𝐢𝐭𝐲
A container bundles an application with all its dependencies into a lightweight, executable unit. It runs in an isolated userspace on the host OS, much like a temporary festival confined within the field. Each container has its own filesystem, processes, and networking but shares the host kernel—allowing near-instant startup and teardown.
𝐏𝐨𝐫𝐭𝐚𝐛𝐢𝐥𝐢𝐭𝐲 𝐚𝐧𝐝 𝐎𝐫𝐜𝐡𝐞𝐬𝐭𝐫𝐚𝐭𝐢𝐨𝐧
Because containers carry everything needed to run, they work identically across environments—from a laptop to cloud servers. Tools like Kubernetes (K8s) act as the organizers, automating deployment, scaling, and management of thousands of containers. The main challenge lies in managing persistence and ensuring applications remain stateless for seamless orchestration.


14
In my village, the Ganesh Visarjan procession always began “after dusk,” yet every year it started at the exact same moment—without clocks or signals. The priest at the main temple would begin a chant once it was dark enough. The nearby band, hearing it, would start playing. The bearers of the idol would lift it when the music reached them. In minutes, the entire town moved in harmony—thousands of people, perfectly synchronized by a single local trigger.
That’s when I realized—it’s exactly how 𝐄𝐯𝐞𝐧𝐭-𝐃𝐫𝐢𝐯𝐞𝐧 𝐀𝐫𝐜𝐡𝐢𝐭𝐞𝐜𝐭𝐮𝐫𝐞 works.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐃𝐞𝐜𝐨𝐮𝐩𝐥𝐢𝐧𝐠 𝐒𝐞𝐫𝐯𝐢𝐜𝐞𝐬 𝐰𝐢𝐭𝐡 𝐄𝐯𝐞𝐧𝐭𝐬
In monolithic systems, Service A calls Service B directly—if B fails, A fails too. 𝐄𝐯𝐞𝐧𝐭-𝐝𝐫𝐢𝐯𝐞𝐧 𝐚𝐫𝐜𝐡𝐢𝐭𝐞𝐜𝐭𝐮𝐫𝐞 avoids this. Instead of direct calls, Service A publishes an event (like ORDER_CREATED) to a message broker such as Apache Kafka or AWS SNS/SQS. It doesn’t know or care who receives it, ensuring independence and fault tolerance.
𝐓𝐡𝐞 𝐏𝐮𝐛𝐥𝐢𝐬𝐡–𝐒𝐮𝐛𝐬𝐜𝐫𝐢𝐛𝐞 𝐏𝐚𝐭𝐭𝐞𝐫𝐧
Other services—Inventory, Email, Fraud Detection—subscribe to events relevant to them. When ORDER_CREATED is published, each subscriber reacts asynchronously, just like the band responding to the chant or idol bearers following the music. This allows the system to scale efficiently; if one service lags, others continue unaffected.
𝐁𝐞𝐧𝐞𝐟𝐢𝐭𝐬 𝐚𝐧𝐝 𝐂𝐡𝐚𝐥𝐥𝐞𝐧𝐠𝐞𝐬
Key benefits include scalability, loose coupling, and resilience. Challenges lie in handling eventual consistency (data not instantly synced) and in debugging complex event flows. Despite that, this architecture is central to modern microservices systems, driving responsiveness and fault isolation in distributed environments.


9
I once volunteered to coordinate a Republic Day parade. It was chaos—floats, bands, and troupes all trying to align. Then a retired army colonel arrived with a simple rulebook. It didn’t define what each group should do, only how they should move. Rule 1: stay 50 feet behind the group ahead. Rule 2: signal before stopping. Rule 3: disputes go to the marshal. Suddenly, everything flowed smoothly.
It struck me — that’s exactly how 𝐂𝐨𝐦𝐦𝐮𝐧𝐢𝐜𝐚𝐭𝐢𝐨𝐧 𝐏𝐫𝐨𝐭𝐨𝐜𝐨𝐥𝐬 (like 𝐓𝐂𝐏/𝐈𝐏) work.
𝐓𝐡𝐞 𝐓𝐞𝐜𝐡 𝐊𝐧𝐨𝐰𝐥𝐞𝐝𝐠𝐞:
𝐋𝐚𝐲𝐞𝐫𝐢𝐧𝐠 𝐚𝐧𝐝 𝐀𝐛𝐬𝐭𝐫𝐚𝐜𝐭𝐢𝐨𝐧
The 𝐓𝐂𝐏/𝐈𝐏 suite—the foundation of the internet—works in layers. The parade rulebook mirrors the Transport Layer (TCP), which ensures reliable data delivery between hosts. It ignores the data’s meaning—just as the colonel’s rules didn’t care what each float represented.
𝐂𝐨𝐫𝐞 𝐌𝐞𝐜𝐡𝐚𝐧𝐢𝐬𝐦𝐬 𝐨𝐟 𝐓𝐂𝐏
𝐓𝐂𝐏 uses mechanisms like connection handshakes (the marshal confirming readiness), sequencing and acknowledgments (ensuring every unit arrives in order), flow control (preventing a sender from overwhelming a receiver—like the 50-foot rule), and congestion control (reducing speed under heavy traffic). These guarantee stable communication for tasks like browsing and file transfer.
𝐓𝐫𝐚𝐝𝐞-𝐨𝐟𝐟𝐬: 𝐓𝐂𝐏 𝐯𝐬. 𝐔𝐃𝐏
Reliability comes with overhead and delay. When speed matters more than accuracy—like in gaming or video streams—𝐔𝐃𝐏 is used. 𝐔𝐃𝐏 skips handshakes and sequencing, sending packets freely; it’s faster but less reliable. Developers select between 𝐓𝐂𝐏 and 𝐔𝐃𝐏 based on application priorities.


58
During a college break at a family-run dhaba, I noticed a major bottleneck. The kitchen had a single stove and cook. Each order was prepared from scratch, so during lunch rushes, wait times were enormous. The owner optimized operations by pre-making the three most-ordered gravies (butter chicken, dal tadka, paneer butter masala) during off-peak hours. When an order arrived, the cook simply combined the pre-prepared base with fresh protein and garnishes, massively increasing throughput.
It hit me right then. That’s exactly how **In-Memory Caching (Redis, Memcached)** works.
## 1. Reducing Latency
Expensive operations in computing—like database queries or external API calls—are analogous to preparing a meal from scratch each time. In-memory caching stores results of these operations in RAM, delivering them instantly on request.
## 2. Implementation Patterns
Applications check the cache first. On a **cache hit**, the data is returned immediately. On a **cache miss**, the application queries the backend, stores the result in cache (often with a TTL), and returns it. Common patterns include Cache-Aside (Lazy Loading) and Write-Through. Services like Redis and Memcached are widely used for caching user sessions, product catalogs, or frequently accessed data, reducing backend load and improving response times.
## 3. Cache Invalidation and Trade-offs
The key challenge is knowing when cached data is stale. Long TTLs improve performance but risk serving outdated data; short TTLs ensure freshness but increase cache misses. Strategies like write-through caching balance performance and consistency, though they add write complexity. Effective cache management dramatically improves system throughput and responsiveness, just like pre-preparing gravies transformed the dhaba’s lunch service.


8
I once watched a jazz ensemble where no musician led. They began with a simple rhythm, and each member could introduce new melodic phrases. Others listened carefully, harmonized, built upon it, or stepped back. There was no central command—just shared rules and constant, subtle communication. The system self-regulated, producing complex, beautiful music from distributed interactions.
It hit me right then. That’s exactly how **Distributed Consensus Algorithms (like Raft)** work.
## 1. State Machine Replication
In distributed systems such as database clusters (etcd, Consul), multiple machines must agree on a sequence of operations to maintain consistent state across all nodes. This ensures fault tolerance. If the leader node fails, the cluster must elect a new leader without losing data or progress.
## 2. Raft Consensus Mechanism
Raft achieves consensus by electing a leader node. The leader accepts client commands and replicates them to followers. Commands are committed only when a majority of nodes log them, ensuring durability even if some nodes fail. If the leader crashes, remaining nodes elect a new leader with the most up-to-date log. This mirrors the jazz ensemble: one node initiates an action, others acknowledge and coordinate.
## 3. CAP Theorem and Latency Trade-offs
Raft prioritizes **Consistency** over Availability during network partitions. Writes must achieve majority agreement, introducing latency. Systems like Amazon DynamoDB offer tunable consistency, allowing developers to balance strong consistency (like Raft) with lower-latency eventual consistency.


9
I read about an ancient city repeatedly rebuilt atop its ruins. Over centuries, streets and foundations were buried, but key landmarks like the main square and central temple persisted in the new construction. Archaeologists used the modern city layout as a guide, assuming important structures of the past lay beneath the present ones. The new city acted as a living cache for the old.
It hit me right then. That’s exactly how **CPU cache memory** works.
## 1. Memory Hierarchy and Speed Gap
CPUs operate extremely fast, but fetching data from main RAM is much slower, like traveling to a distant warehouse for every tool. To bridge this gap, CPUs have small, ultra-fast memory banks called caches (L1, L2, L3) directly on the processor, storing frequently accessed data for rapid retrieval.
## 2. Locality of Reference
Caching relies on two principles:
- **Temporal locality**: Recently used data is likely to be used again soon.
- **Spatial locality**: Data near recently used items is likely to be needed next.
This mirrors the ancient city: knowing one key landmark often indicates the locations of related structures nearby.
## 3. Cache Lines and Performance Impact
Data moves from RAM to cache in blocks called **cache lines**. On a **cache hit**, the CPU retrieves data instantly. On a **cache miss**, it fetches the entire line from RAM, slower but efficient for subsequent access. Optimizing data structures for contiguous memory access, like arrays instead of linked lists, improves cache performance. Multi-core systems face additional challenges with cache coherency, balancing speed with design complexity.


14
I once visited a remote village during a harsh summer. The community relied on a single, deep well for water. In the cool morning, women drew water efficiently. But by midday, when demand peaked, the line became a bottleneck. Everyone needed water at once, arguments broke out, and the wait became intolerable. The well itself wasn’t slow; the simultaneous demand created the problem. Later, an elder explained the solution: families stored water in large pots during off-peak hours, relieving pressure during the rush.
It hit me right then. That’s exactly how **rate limiting and throttling in APIs** work.
## 1. Preventing Resource Exhaustion
API backends have finite resources. A sudden surge of requests from a single user or misconfigured client can overwhelm the system, causing downtime for others. Rate limiting defines the maximum number of requests a client can make in a time window (e.g., 1000 requests per hour), ensuring fair usage and system stability.
## 2. Implementation Patterns
Common approaches include the **Token Bucket**, where requests consume tokens from a refilling bucket, and the **Fixed Window Counter**, which counts requests per hour and resets periodically. More advanced systems use a **sliding window log** to improve fairness. Services like Stripe enforce rate limits, responding with HTTP `429 Too Many Requests` when clients exceed quotas.
## 3. Strategies and Trade-Offs
The trade-off is protecting backend resources versus frustrating legitimate users. Mitigation strategies include returning headers that indicate request limits and remaining quota, implementing **graceful degradation** instead of hard blocking, and using separate higher limits for critical workflows to maintain user experience without compromising system stability.


18
During Chennai’s load-shedding season, I shadowed an electrical engineer managing city power distribution. What struck me wasn’t just the complexity, but how he balanced supply and demand in real-time. Power consumption fluctuated predictably – morning tea, evening cooking, and late-night AC usage – requiring dynamic coordination of multiple generation sources: thermal plants for baseline power, solar for peak daylight, and backup generators for emergencies. Maintaining stability while responding to changing demand was the key challenge.
It hit me right then. That’s exactly how autoscaling and resource management in cloud computing work.
## 1. Horizontal vs Vertical Scaling
Horizontal scaling adds more instances, like bringing extra generators online, while vertical scaling increases resources for existing instances, akin to boosting generator output. Each has different cost, speed, and capacity characteristics. AWS Auto Scaling combines both, scaling horizontally for gradual load increases and vertically for sudden spikes. Predictive policies anticipate demand based on historical patterns, mirroring power grid operators’ planning for daily consumption cycles.
## 2. Cold Start and Warm Pools
Serverless and container platforms face cold start delays, similar to backup generators needing time to ramp up. Warm pools maintain pre-initialized instances for immediate response. AWS Lambda provisioned concurrency and Google Cloud Run minimum instances reduce cold start latency, while Kubernetes Vertical Pod Autoscaler ensures right-sized CPU and memory allocations without waste, like spinning reserves in a power grid.
## 3. Cost Optimization and Multi-Zone Scaling
Cloud cost optimization balances performance with expenses, paralleling how grids use expensive peak generators and cheaper baseline power. Spot instances provide low-cost capacity with termination risk; reserved instances cover predictable workloads. Spotify combines on-demand, spot, and reserved instances for efficient scaling, automatically shifting workloads for cost and performance, just as grids prioritize cheaper generation while maintaining peak reserves.


14