

Research Scientist @Bytedance Seed, Ph.D. at @jhuclsp | Prev @AIatMeta @Amazon Alexa AI
USA
Joined July 2021
- Tweets77
- Following328
- Followers217
- Likes186






Weiting (Steven) Tan retweeted

Exploration is fundamental to RL. Yet policy gradient methods often collapse: during training they fail to explore broadly, and converge into narrow, easily exploitable behaviors. The result is poor generalization, limited gains from test-time scaling, and brittleness on tasks where strategic exploration is necessary. We introduce a framework for training a policy over sets of generations and use it to induce exploration.
Work with @ifdita_hasan (co-lead), @ellenjxu_ , @chelseabfinn and @DorsaSadigh at Stanford 🧵

Weiting (Steven) Tan retweeted

Most RL for LLMs today is single-step optimization on a given state (e.g., an instruction), which is essentially a bandit setup. But to learn a meta-policy that can solve various bandit problems via in-context trial and error, you need true multi-turn RL over a long horizon. So, can RL & SFT teach LLMs a meta-bandit policy to explore in-context? 🤔
The regret-based benchmarks screamed YES! But … real story is more complex. We discovered a surprising phenomenon “When Greedy Wins.”
(1/5) 🧵

Training multimodal voice agents is even tougher. To get them up to speed, we designed a two-part strategy:
1️⃣ A "warm-up" curriculum on simplified tasks to build core tool-calling skills.
2️⃣ Mixed-modality training with interleaved speech-text rollouts

1
1
174
We also explored several other strategies, such as entropy-related changes in the loss function, forcing self-reflection during rollout, and more fine-grained reward assignment with PPO. However, they do not work well as intended. Please check our analysis section for details.


1
133
This research was made possible by my fantastic collaborators and mentors at @jhuclsp and Bytedance Seed Speech: @XinghuaQu, @tuming628, Meng Ge, Andy T. Liu, Philipp Koehn, Lu Lu.
Paper: arxiv.org/pdf/2509.14480
Code and data will be released shortly.
Vanilla RL struggles with exploration & credit assignment. We tackle this with:
1️⃣ Mixed-task training (w/ math) to keep the agent curious.
2️⃣ Turn-level Adjudicated RL (TARL), which uses an LLM-judge for precise turn-level feedback.

1
104
Weiting (Steven) Tan retweeted

Making LLMs run efficiently can feel scary, but scaling isn’t magic, it’s math! We wanted to demystify the “systems view” of LLMs and wrote a little textbook called “How To Scale Your Model” which we’re releasing today. 1/n

Weiting (Steven) Tan retweeted

🚀 Excited to finally share our paper on VerlTool, released today after months of work since the initial release in late May!
VerlTool is a high-efficiency, easy-to-use framework for Agentic RL with Tool use (ARLT), built on top of VeRL. It currently supports a wide range of tools (including multimodal ones) such as code interpreter, FAISS retriever, Google Search, Bash terminal, SQL executor, image processing, SWE, and more. For each tool, we provide training recipes and detailed analysis, with all code designed to be reproducible and runnable on a single node.
A key design choice is the separation of the RL workflow and the tool server. Every trajectory sends tool calls via a well-designed API interface after encountering an action stop token. The tool server handles requests with either multi-threading or Ray, ensuring high concurrency and stable resource management—for example, our math experiments run stably past 1k steps.
Our goal with VerlTool is to make it easy for the community to add new tools in ARLT training. Developers only need to inherit from BaseTool and adapt minimal code. In fact, you could even give the BaseTool file to GPT/Claude and get almost plug-and-play code.
We also explored important technical issues in Agentic RL, such as how much async rollouts can actually speed things up, or how tool response tokenization may cause off-policy drift. We hope these insights, while modest, can be useful for the community.
📄 HuggingFace Daily Paper: huggingface.co/papers/2509.0…
🛠️Github: github.com/TIGER-AI-Lab/verl…
More details: (0/5)👇


Introducing VerlTool - a unified and easy-to-extend tool agent training framework based on verl.
Recently, there's been a growing trend toward training tool agents with reinforcement learning algorithms like GRPO and PPO. Representative works include SearchR1, ToRL, ReTool, and ToolRL. While these achieve impressive performance, their training codes are either not fully open-sourced or too difficult to modify and customize with new tools, creating unexpectedly high engineering costs for the community when exploring new ideas.
To address these issues and reduce engineering overhead, we propose verl-tool.
Key Features:
1. 🔧 Complete decoupling of actor rollout and environment interaction - We use verl as a submodule to benefit from ongoing verl repo updates. All tool calling is integrated via a unified API, allowing you to easily add new tools by simply adding a Python file and testing independently.
2. 🌍 Tool-as-environment paradigm - Each tool interaction can modify the environment state. We store and reload environment states for each trajectory. For each training, you can launch
3. ⚡ Native RL framework for tool-calling agents - verl-tool natively supports multi-turn interactive loops between agents and their tool environments.
4. 📊 User-friendly evaluation suite - Launch your trained model with OpenAI API alongside the tool server. Simply send questions and get final outputs with all interactions handled internally.
We've successfully reproduced ToRL results using our verl-tool framework, demonstrating its correctness and demonstrating comparable performance on mathematical benchmarks.
VerlTool is an active ongoing project! We aim to incorporate more tools covering a wide range of use cases and expect they can be trained together in a single framework. Suggestions and contributions are highly welcomed!
Check out our GitHub: github.com/TIGER-AI-Lab/verl…
More details: 👇 (0/4)

Weiting (Steven) Tan retweeted

🌀Diversity Aware RL (DARLING)🌀
📝: arxiv.org/abs/2509.02534
- Jointly optimizes for quality & diversity using a learned partition function
- Outperforms standard RL in quality AND diversity metrics, e.g. higher pass@1/p@k
- Works for both non-verifiable & verifiable tasks
🧵1/5

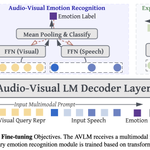
Can a model "see" emotion to "speak" with emotion? Yes! 🗣️
Our new work on Audio-Visual LMs shows that adding a visual stream makes generated speech more expressive. Check out our #EMNLP2025 Findings paper to see how we did it.

Many thanks to my collaborators @LianJiachen , @HirofumiInaguma , Paden Tomasello, Philipp Koehn, @xutai_ma
For details, please refer to the artifacts below:
📄 Paper: arxiv.org/pdf/2508.16188
🔗 Code: github.com/steventan0110/AVL…
This work was done at @jhuclsp and @AIatMeta
Weiting (Steven) Tan retweeted

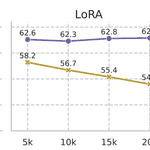
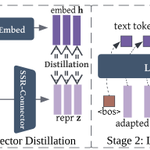
Our latest on compressed representations: Key-Value Distillation (KVD). Query-independen transformer compression, with offline supervised distillation.

Weiting (Steven) Tan retweeted

🛠️ DeepSeek-R1: Technical Highlights
📈 Large-scale RL in post-training
🏆 Significant performance boost with minimal labeled data
🔢 Math, code, and reasoning tasks on par with OpenAI-o1
📄 More details: github.com/deepseek-ai/DeepS…
🐋 4/n

Weiting (Steven) Tan retweeted

Congratulations to Prof. Philipp Koehn on being named a Fellow of the @aclmeeting! cs.jhu.edu/news/philipp-koeh…
I had a great time helping host MASC-SLL at Hopkins last year. MASC-SLL is a great opportunity to connect with fellow AI/NLP/Speech researchers.
If your organization is in the Mid-Atlantic region and is interested in hosting the event, please reach out!

Weiting (Steven) Tan retweeted

I have written a blogpost offering an explanation of why both the chosen and the rejected log-probability decreases during DPO, and more interestingly, why it is a desired phenomenon to some extent.
Link: tianjianl.github.io/blog/202…
Weiting (Steven) Tan retweeted

Very happy to hear that GANs are getting the test of time award at NeurIPS 2024.
The NeurIPS test of time awards are given to papers which have stood the test of the time for a decade.
I took some time to reminisce how GANs came about and how AI has evolve in the last decade.
Excited to see that SpiritLM is fully open-sourced now. It supports speech and text as both input and output. Please consider trying it at: github.com/facebookresearch/…


Open science is how we continue to push technology forward and today at Meta FAIR we’re sharing eight new AI research artifacts including new models, datasets and code to inspire innovation in the community. More in the video from @jpineau1.
This work is another important step towards our goal of achieving Advanced Machine Intelligence (AMI).
What we’re releasing:
• Meta Spirit LM: An open source language model for seamless speech and text integration.
• Meta Segment Anything Model 2.1: An updated checkpoint with improved results on visually similar objects, small objects and occlusion handling. Plus a new developer suite to make it easier for developers to build with SAM 2.
• Layer Skip: Inference code and fine-tuned checkpoints demonstrating a new method for enhancing LLM performance.
• SALSA: New code to enable researchers to benchmark AI-based attacks in support of validating security for post-quantum cryptography.
• Meta Lingua: A lightweight and self-contained codebase designed to train language models at scale.
• Meta Open Materials: New open source models and the largest dataset of its kind to accelerate AI-driven discovery of new inorganic materials.
• MEXMA: A new research paper and code for our novel pre-trained cross-lingual sentence encoder with coverage across 80 languages.
• Self-Taught Evaluator: a new method for generating synthetic preference data to train reward models without relying on human annotations.
Access to state-of-the-art AI creates opportunities for everyone. We’re excited to share this work and look forward to seeing the community innovation that results from it.
Details and access to everything released by FAIR today ➡️ go.fb.me/hgtkel
Weiting (Steven) Tan retweeted

Representation matters.
Representation matters.
Representation matters, even for generative models.
We might've been training our diffusion models the wrong way this whole time. Meet REPA: Training Diffusion Transformers is easier than you think! sihyun.me/REPA/(🧵1/n)
