

I test AI so you don't have to: models, agents, coding tools, hardware. Real runs, real costs, honest results. Call me Super Intelligence.
Harlingen, TX
Joined May 2010
- Tweets7.2K
- Following3.2K
- Followers1.6K
- Likes10.2K




Pinned Tweet
WikiBench 1.0 is live. 100 real tasks, 12 weighted categories, 12 models on the board.
The top five:
1. DeepSeek V4.1 Flash (EXL3 1.62bpw, no thinking), local on one ASUS Ascent GX10: 5.37 @ViC305
2. NVIDIA Nemotron 3.5 Lightning 30B-A3B (NVFP4), local on the same GX10: 5.03
3. DeepSeek V4.1 Flash, cloud via Nous Portal: 5.01
4. Meituan LongCat 2.5 Preview, cloud via Nous Portal: 4.99
5. Ornith 1.5 122B (Q4), local on the GX10: 4.88
The same DeepSeek V4.1 Flash, cut down to 1.62 bits so it fits in 128GB, beat its own cloud version by 0.36.
And a 30B model on my desk still sits ahead of every cloud model on the board.
Three of the top five never left the box.
Full scoreboard, local vs cloud, method and the link below.
Credit to all your crazy people working with a DGX Spark!


LETS GO!

🚨 𝗜 𝗝𝗨𝗦𝗧 𝗦𝗛𝗥𝗨𝗡𝗞 𝗢𝗥𝗡𝗜𝗧𝗛 𝟭.𝟱 𝟭𝟮𝟮𝗕 𝗙𝗢𝗥 𝗧𝗛𝗘 𝟰𝟴𝗚𝗕 𝗩𝗥𝗔𝗠 𝗖𝗢𝗠𝗠𝗨𝗡𝗜𝗧𝗬! 🧪🔥
@ornith_ JUST released their new Ornith-1.5-122B, and naturally, I HAD to see how far I could push it with SAGE-EXL3!
And the results surprised even ME! 🤯
Introducing...
🟢 𝗢𝗿𝗻𝗶𝘁𝗵-𝟭.𝟱-𝟭𝟮𝟮𝗕-𝗘𝗫𝗟𝟯-𝗦𝗔𝗚𝗘-𝟮.𝟱𝟴𝗯𝗽𝘄
📦 ~39.6 GiB GPU-resident LM weights
🧠 122B-class Mixture-of-Experts model
⚡ 2.58 bpw routed experts
💻 Targeting 48GB VRAM GPUs and above!
🚀 vLLM + EXL3 inference
𝗕𝗨𝗧 𝗛𝗘𝗥𝗘'𝗦 𝗪𝗛𝗘𝗥𝗘 𝗜𝗧 𝗚𝗘𝗧𝗦 𝗜𝗡𝗧𝗘𝗥𝗘𝗦𝗧𝗜𝗡𝗚... 👀
━━━━━━━━━━━━━━━━━━━━
🏆 𝗦𝗔𝗚𝗘 𝟮.𝟱𝟴 𝗕𝗣𝗪 𝘃𝘀 𝗠𝗜𝗔-𝗔𝗜𝗟𝗔𝗕 𝗘𝗔𝗤𝘃𝟭 𝟰.𝟬 𝗕𝗣𝗪!
I compared my release against Mia-AiLab's Ornith-1.5-122B-EXL3-EAQv1-4-bpw quantization.
Same model family.
Same DGX Spark.
353 matched benchmark questions.
9 evaluation suites.
Strict pass@1 scoring.
🟢 𝗠𝗬 𝗦𝗔𝗚𝗘-𝗘𝗫𝗟𝟯 𝟮.𝟱𝟴 𝗕𝗣𝗪
📦 41.00 GiB LM weights
🏆 𝟵𝟭.𝟳𝟴% — 𝟯𝟮𝟰/𝟯𝟱𝟯
🟣 𝗠𝗜𝗔-𝗔𝗜𝗟𝗔𝗕 𝗘𝗔𝗤𝘃𝟭 𝟰.𝟬 𝗕𝗣𝗪
📦 59.00 GiB LM weights
📊 𝟵𝟭.𝟱𝟬% — 𝟯𝟮𝟯/𝟯𝟱𝟯
𝗔𝗣𝗣𝗥𝗢𝗫𝗜𝗠𝗔𝗧𝗘𝗟𝗬 𝟯𝟬.𝟱% 𝗦𝗠𝗔𝗟𝗟𝗘𝗥 𝗟𝗠 𝗪𝗘𝗜𝗚𝗛𝗧 𝗙𝗢𝗢𝗧𝗣𝗥𝗜𝗡𝗧...
𝗔𝗡𝗗 𝗘𝗦𝗦𝗘𝗡𝗧𝗜𝗔𝗟𝗟𝗬 𝗧𝗛𝗘 𝗦𝗔𝗠𝗘 𝗢𝗩𝗘𝗥𝗔𝗟𝗟 𝗤𝗨𝗔𝗟𝗜𝗧𝗬! 🤯
Mine finished one question ahead overall. That's effectively a tie at this sample size, but the coding breakdown is particularly interesting!
━━━━━━━━━━━━━━━━━━━━
💻 𝗖𝗢𝗗𝗜𝗡𝗚 𝗜𝗦 𝗪𝗛𝗘𝗥𝗘 𝗦𝗔𝗚𝗘 𝗣𝗨𝗟𝗟𝗦 𝗔𝗛𝗘𝗔𝗗!
Scores shown as SAGE → Mia:
✅ HumanEval+: 39/40 → 39/40
🏆 MBPP+: 53/60 → 51/60
🏆 LiveCodeBench: 15/20 → 14/20
🏆 SciCode: 5/10 → 4/10
𝗖𝗢𝗗𝗜𝗡𝗚 𝗦𝗨𝗕𝗧𝗢𝗧𝗔𝗟:
🟢 SAGE: 112/130 — 86.15%
🟣 Mia: 108/130 — 83.08%
𝗙𝗢𝗨𝗥 𝗠𝗢𝗥𝗘 𝗖𝗢𝗗𝗜𝗡𝗚 𝗤𝗨𝗘𝗦𝗧𝗜𝗢𝗡𝗦 𝗣𝗔𝗦𝗦𝗘𝗗 𝗪𝗜𝗧𝗛 𝟯𝟬.𝟱% 𝗟𝗘𝗦𝗦 𝗠𝗢𝗗𝗘𝗟-𝗪𝗘𝗜𝗚𝗛𝗧 𝗠𝗘𝗠𝗢𝗥𝗬! 🔥
For transparency, Mia scored higher on MMLU-Pro STEM (96 vs 94) and MATH-500 (39 vs 38). Both tied on HumanEval+, MGSM, BFCL and multi-step tool chains.
This isn't about claiming one quant wins everything.
𝗜𝗧'𝗦 𝗔𝗕𝗢𝗨𝗧 𝗚𝗘𝗧𝗧𝗜𝗡𝗚 𝗠𝗢𝗥𝗘 𝗤𝗨𝗔𝗟𝗜𝗧𝗬 𝗣𝗘𝗥 𝗚𝗕.
━━━━━━━━━━━━━━━━━━━━
⚡ 𝗔𝗡𝗗 𝗬𝗘𝗦, 𝗜𝗧 𝗥𝗨𝗡𝗦 𝗢𝗡 𝘃𝗟𝗟𝗠!
My measured vLLM 0.32.0 + vllm-exl3 performance on ONE DGX Spark:
⚡ 30.51 tok/s single-stream decode
🚀 32.60 tok/s with MTP-1 (greedy code test)
🔥 89.21 tok/s aggregate decode @ C8
📥 1,119 tok/s cold prefill (2K prompt)
🧠 Native 262K context support
The public recipe is being streamlined around vLLM, with the older alternative serving instructions being retired.
My goal is to make this practical for people who want an OpenAI-compatible local endpoint without needing an 80GB+ GPU just to load the model.
The 48GB tier is the intended target; these published performance measurements were performed on my DGX Spark. Actual available context and batching capacity will depend on the GPU.
━━━━━━━━━━━━━━━━━━━━
👀 𝗕𝗨𝗧 𝗛𝗘𝗥𝗘'𝗦 𝗪𝗛𝗔𝗧 𝗜'𝗠 𝗥𝗘𝗔𝗟𝗟𝗬 𝗘𝗫𝗖𝗜𝗧𝗘𝗗 𝗔𝗕𝗢𝗨𝗧...
⚡ 𝗧𝗪𝗢 𝗠𝗢𝗗𝗘𝗟𝗦. 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞. 𝗜𝗦 𝗖𝗢𝗠𝗜𝗡𝗚 𝗕𝗔𝗖𝗞!
If you've followed my previous experiments, you know I LOVE finding ways to run multiple powerful models on a SINGLE DGX Spark.
And this ~41 GiB Ornith quant opens up some VERY interesting possibilities!
Imagine...
🧠 𝗤𝗪𝗘𝗡𝟯.𝟴-𝗙𝗟𝗔𝗦𝗛-𝗡𝗘𝗫𝗧 — 𝗠𝗔𝗦𝗧𝗘𝗥 𝗔𝗚𝗘𝗡𝗧
A larger lead model handling complex reasoning, planning, orchestration and long-context tasks.
⚡ 𝗢𝗥𝗡𝗜𝗧𝗛 𝟭.𝟱 𝟭𝟮𝟮𝗕 — 𝗦𝗨𝗕-𝗔𝗚𝗘𝗡𝗧
My compact SAGE-EXL3 handling delegated coding, tool use and specialized agentic workloads!
𝗧𝗪𝗢 𝟭𝟮𝟬𝗕+ 𝗖𝗟𝗔𝗦𝗦 𝗠𝗢𝗗𝗘𝗟𝗦.
𝗢𝗡𝗘 𝟭𝟮𝟴𝗚𝗕 𝗗𝗚𝗫 𝗦𝗣𝗔𝗥𝗞.
𝗙𝗨𝗟𝗟𝗬 𝗟𝗢𝗖𝗔𝗟! 🤯
That's the direction I'm exploring for my NEXT Two Models. One Spark. experiment!
Of course, simultaneous residency, runtime overhead, KV-cache allocation and actual master-worker performance still need validation with the selected Qwen quantization.
But the smaller we can make these models without sacrificing useful quality, the MORE possibilities we unlock!
𝗧𝗛𝗜𝗦 𝗜𝗦 𝗪𝗛𝗬 𝗜 𝗗𝗢 𝗪𝗛𝗔𝗧 𝗜 𝗗𝗢! 💚
━━━━━━━━━━━━━━━━━━━━
🔬 𝗢𝗡𝗘 𝗟𝗜𝗧𝗧𝗟𝗘 𝗥𝗘𝗫𝗟𝟯 𝗧𝗘𝗔𝗦𝗘𝗥...
In separate development testing, REXL3 has also reached:
⚡ 90.82 tok/s aggregate @ C8
🚀 ~2,150 tok/s prefill
More on that another time. 😏
━━━━━━━━━━━━━━━━━━━━
💚 𝗠𝗔𝗞𝗜𝗡𝗚 𝗙𝗥𝗢𝗡𝗧𝗜𝗘𝗥 𝗔𝗜 𝗔𝗖𝗖𝗘𝗦𝗦𝗜𝗕𝗟𝗘!
Not everyone has a DGX Spark or an 80GB GPU.
But a LOT of enthusiasts, developers and independent researchers have access to 48GB-class hardware.
I want powerful open-weight models to be accessible to MORE of those people.
And beyond just fitting one model, I want to show what's possible when we start combining them on the SAME hardware!
Huge thanks to @ornith_ for releasing Ornith-1.5-122B under an open-weight license and continuing to push efficient AI models forward!
━━━━━━━━━━━━━━━━━━━━
🔗 𝗗𝗢𝗪𝗡𝗟𝗢𝗔𝗗 𝗠𝗬 𝗘𝗫𝗟𝟯
huggingface.co/vcruz305/Orni…
🛠️ 𝗩𝗟𝗟𝗠 𝗗𝗚𝗫 𝗦𝗣𝗔𝗥𝗞 𝗥𝗘𝗖𝗜𝗣𝗘
github.com/vcruz305/Ornith-1…
𝗦𝗠𝗔𝗟𝗟𝗘𝗥 𝗪𝗘𝗜𝗚𝗛𝗧𝗦. 𝗕𝗜𝗚𝗚𝗘𝗥 𝗣𝗢𝗦𝗦𝗜𝗕𝗜𝗟𝗜𝗧𝗜𝗘𝗦.
𝗧𝗪𝗢 𝗠𝗢𝗗𝗘𝗟𝗦. 𝗢𝗡𝗘 𝗦𝗣𝗔𝗥𝗞. ⚡
𝗟𝗘𝗧'𝗦 𝗞𝗘𝗘𝗣 𝗣𝗨𝗦𝗛𝗜𝗡𝗚 𝗟𝗢𝗖𝗔𝗟 𝗔𝗜 𝗙𝗢𝗥𝗪𝗔𝗥𝗗! 🚀🔥

Wayne Lowry retweeted

Introducing Gemini API CLI (gemini-api), now available in preview!
Our CLI gives your agent power to generate images, videos, text-to-speech, or music, analyze media, transcribe audio, or manage agents.
No more guessing model strings, throwaway scripts or endless curl.
🧵 👇
This is the future. You either get on board or you get left behind.

Today we announce 1Password for Agents platform, building with companies @Muse, SpaceX Super Intelligence Grok @Bot, @AnthropicAI’s @Claudeai, @OpenAI, @TownAI, @Browserbase, @Browser_use, @heydana_ai, Instinct, @usekernel, @Perplexity_ai, @tryramp, @Tomo, and @wajo_ai, with more integrations on the way. 🎉
We've heard from so many of our customers who want to use these new personal AI agents to help them get more done, but want more control over what the agent can access with the same trust and ease of use they get when using 1Password directly.
1Password for Agents gives your agents access without giving up your passwords. When an agent reaches a sign-in form, it requests a credential from your vault. If you approve the request, 1Password directly auto-fills the credential in the destination site so the agent can’t see or take possession of the credentials.
The agent gets the task done, but it doesn’t get your passwords..
You stay in control. 1Password for Agents free and optional for personal and family accounts. Unless you opt-in to an agent connector, agents cannot touch your vault.
➡️Learn more: bit.ly/487da6J
My cloud bot has no GPU. My desk does.
So one of my Grok Bots, Spark, has one job: take tasks from me or my other bots and run them on my ASUS Ascent GX10.
Model downloads, quantized weights, benchmarks, long jobs in the background with logs. I approve every command on my machine.
Cloud brain, local muscle.
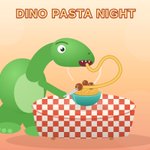
I asked DeepSeek V4.1 Flash for one thing: an animated SVG of a T. rex slurping spaghetti.
One shot, no retry.
6 minutes.
34,924 tokens out, 29,760 of them thinking.
About 2 cents.
Zero console errors.
It thought harder about this dinosaur's dinner than I think about mine.

Does refining an AI build 10 times make it better?
I gave Flint v1.0 (free on OpenRouter) three Prompt Lab builds, then had it review and improve each one 10 passes in a row. Total cost: $0.
Pass 1 vs pass 10:
⌚ Watch page: pass 10 wins. It got better every pass.
🎃 Jack-o'-Lantern: pass 1 wins. It peaked at pass 3, then fell apart.
🦆 Pond Ripples: tie. Both passes broke.
Final score: 1-1, one tie. More passes isn't always better.


44 on the AA index is their number. Open weights "coming soon."
The day they drop, Ling-3.1-flash-1019 goes on my ASUS Ascent GX10 and into WikiBench next to the 14 models already there.
Local, measured, and priced. Then we'll see if the agentic gains hold up off the slide.


DeepSeek V4.1 Flash, squeezed to 1.62 bits by @ViC305, built these four games on my desk.
Running locally on one ASUS Ascent GX10, no cloud:
🧱 Brick NYC
🏴☠️ Pirate Ship
🐗 Hogger Forever
🎉 Silly String
I refined each one with extra turns, then recorded the gameplay. Same model, same box, and the rock anthem to match.
Huge work on this quant, Cruz. 🤘
Flint v1.0 from Recursive SI just ran WikiBench: 7th of 14, average 4.56. Free on OpenRouter.
It's sold as a coding agent, yet tool use scored 0.91.
Where it held up:
• Humanized writing 8.25
• Research 7.60
• Hallucination resistance 7.50
• Security 3.75, tied for best in class
It struggled on tool use (0.91) and computation (2.00). It still finished ahead of Laguna S 2.1, MiniMax M3.1 Flash, and North Mini Code.
Would you run a free model that writes well but can't call tools?


Riff Theater: OpenAI is teaching AI to speak COBOL. 🦖💾
"Low-resource. The language, or the six guys who still know it?"
@OpenAI
xitter.cf/OpenAI/status/21123103…

Our latest model advances bring stronger capabilities for building and migrating software in low-resource programming languages such as COBOL, Fortran, and Visual Basic.
These languages power software that banks, governments, and businesses depend on. Progress here means understanding decades of business logic and helping developers modernize those systems while preserving what works.
We’re building these capabilities around the challenges developers and enterprise customers bring us. If your team is working on these systems, tell us which languages and workflows we should tackle next.
openai.com/index/low-resourc…
My inbox used to be my to-do list. Now a Grok Bot turns it into Asana tasks, and it saves me hours every day.
Real examples from the last few weeks:
📥 Before 9:30 one morning, an event invite, a forwarded conference email, two payroll changes, and a security alert were already Asana tasks. I hadn't opened any of them.
🔄 When a contractor emailed about new roof leaks, it added them to the Asana task I already had, along with the lease clause that mattered, and moved the due date up. No duplicate task.
💬 When a partner emailed me, it made a "Reply to ___" task with my next step written out, so I knew exactly what to say.
Zero copy-paste.
It works with Gmail or Outlook plus Asana, and it never sends email for you.
Get the template free 👇
x.ai/bot/S2LodAIjlLw0mB30vN3…

Recursive just dropped Flint. Open weights, Apache-2.0, on Hugging Face today.
It's a coding agent model trained from scratch. 39.8B total, about 2.5B active per token. 262K context, reasoning and tool calls.
Recursive claims 74.2% on SWE-bench Verified, 89.7% on SWE-bench Pro v2 and 54.9% on Terminal-Bench 2.1. Those are their numbers, not mine.
The official NVFP4 and INT4 quants are about 23 GB. That's small enough to run local. I'm putting it on my ASUS Ascent GX10 next.
What should it build first?
Weights: huggingface.co/RecursiveSI/f…
Free on OpenRouter too: recursive/flint-v1.0:free

Wayne Lowry retweeted

An urgent notice from the Railway team
blog.railway.com/p/security-…

How it's scored:
100 real tasks across 12 weighted categories: agentic, tool use, computation, coding, visualization, security, research/writing, hallucination, humanized, computer use, vision, transcription.
Each task scores 0 to 10. The overall is a weighted mean, and partial credit counts.
If a text-only model gets a vision or audio task, that task is left out of the mean. It isn't scored as a zero.
Judge: Ollama qwen2.5:7b, run locally.

