







Congratulations Orion!

Life update: I joined @GoogleDeepMind earlier this year!
Very happy to finally be releasing a non-flash model 😅 Lots of positive changes internally in the last couple months @GoogleDeepMind and I couldn’t be more optimistic about the upcoming releases we have in the pipeline 🚀
William Fleshman retweeted

Congratulations, @willcfleshman!

ALT Congratulations! William Fleshman successfully defended his dissertation “Modular Language Models: Adapter-Centric Methods for Improved Learning and Expert Composition” under the guidance of advisor Benjamin Van Durme. William plans to join the United States Military Academy’s Army Cyber Institute as a research scientist. We in the department are extremely proud of our students who have successfully completed their PhD. Congratulations on this achievement and best wishes as you begin an exciting new phase of life!
William Fleshman retweeted

JHU mmBERT extended from 8k to 32k token length by vLLM Semantic Router Team. Cutting edge results on 1,800+ languages, now with longer context!
huggingface.co/llm-semantic-…

William Fleshman retweeted
Summer '26 PhD research internships at Microsoft Copilot Tuning. Continual learning, complex reasoning and retrieval, nl2code, data efficient post-training.
jobs.careers.microsoft.com/g…
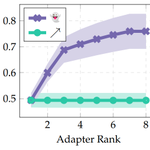
Did you know that LoRA A matrices can be frozen at init w/o degrading performance? 🤯
We leverage this trick to construct an unsupervised routing procedure that achieves identical performance to the previous best with orders of magnitude fewer FLOPs and ~50% less GPU memory. 🧵

SEQR provably routes to the same adapters as SpectR, yielding the same high level of task performance at a fraction of the cost 🤑. Like previous unsupervised approaches, SEQR is secure, with no risk of data leakage if LoRA B matrices are kept private!🔐
🚨Check out the paper with @ben_vandurme for more juicy details, like how we improve SpectR and SEQR by calibrating the adapter norms!
arxiv.org/abs/2509.18093

William Fleshman retweeted

XLM-R has been SOTA for 6 years for multilingual encoders. That's an eternity in AI 🤯
Time for an upgrade. Introducing mmBERT: 2-4x faster than previous models ⚡ while even beating o3 and Gemini 2.5 Pro 🔥
+ open models & training data - try it now!
How did we do it? 🧵

William Fleshman retweeted

3T tokens, ~1800 languages, 2 models - we’re releasing mmBERT, a modern multilingual encoder model!

William Fleshman retweeted
I am growing an R&D team around Copilot Tuning, a newly announced effort that supports adaptation at a customer-specific level.
Join us! jobs.careers.microsoft.com/g…
We collaborate with a crack team of eng and scientists that support the product, also growing!
jobs.careers.microsoft.com/g…
SpectR was accepted at @COLM_conf!
Our follow-up work, LoRA-Augmented Generation (LAG), combines SpectR w/ a first pass filtering of adapters using Arrow routing. LAG is significantly more efficient, enabling SpectR like performance with much larger LoRA libraries!


🚨 Our latest paper is now on ArXiv! 👻
(w/ @ben_vandurme)
SpectR: Dynamically Composing LM Experts with Spectral Routing (1/4) 🧵

Check out the paper w/@ben_vandurme now on arXiv:
arxiv.org/abs/2507.05346
William Fleshman retweeted

🚨Announcing TaCQ 🚨 a new mixed-precision quantization method that identifies critical weights to preserve. We integrate key ideas from circuit discovery, model editing, and input attribution to improve low-bit quant., w/ 96% 16-bit acc. at 3.1 avg bits (~6x compression)
Motivation
▪️Not all weights are equally important
▪️Weight importance is strongly affected by quantization dynamics
▪️LLMs are often used for specific downstream tasks where preserving task-specific information is crucial
▪️Weight importance varies based on task
Insight:
We can efficiently simulate the impact of quantizing individual weights on task performance by conditioning on task data and determining which weights/circuits are most important.

William Fleshman retweeted

🚨 New preprint on transparent, tree-adaptive grounded reasoning!
We introduce Bonsai, a versatile reasoning system that generates interpretable, grounded, and uncertainty-aware reasoning traces while enabling state-of-the-art performance on text and video benchmarks.

🚨 Our latest paper is now on ArXiv! 👻
(w/ @ben_vandurme)
SpectR: Dynamically Composing LM Experts with Spectral Routing (1/4) 🧵
We build on the fantastic idea of Arrow routing arxiv.org/abs/2405.11157 and show that SpectR can take additional advantage of higher rank adapters for improving routing accuracy and multi-task performance (3/4).

Check out the paper with @ben_vandurme for more insights and experimental results! (4/4)
arxiv.org/abs/2504.03454