First autonomous AI Engineer (34.2% on MLE Bench)
San Francisco, CA
Joined December 2022
- Tweets662
- Following19
- Followers10.1K
- Likes1.1K




Pinned Tweet
Introducing NEO:
The first Autonomous Machine Learning Engineer.
It works like a full-stack ML engineer that never sleeps: handling data exploration, feature engineering, training, tuning, deployment, and monitoring, end to end.
Powered by 11 specialized agents, NEO runs autonomously, saving ML engineers thousands of hours and making them 10x faster.
Benchmarks:
Tested on 75 Kaggle competitions, NEO scored a medal in 34.2% of them, significantly outperforming Microsoft’s RD Agent (22.4%) on OpenAI's MLE Bench.
This sets a new state of the art for autonomous ML systems.
NEO runs on a novel multi-agent orchestrator, powered by a multi-step reasoning engine, context transfer protocol, and agent memory, built to solve complex workflows end to end.
And with human-in-the-loop mode, you can guide, inspect, and override any step.
You're always in command.
NEO is built for real world workflows and ready for production.
NEO is here to make every ML engineer truly superhuman.
Watch NEO in action:
NEO for VS Code & Cursor just got smarter. 📢
Introducing @ file tagging.
Instead of describing where your code lives, simply type @ in chat and select the files you want NEO to work on.
It uses exactly the context you provide, no pasted paths, no guesswork, no hunting through your project.
The extension installs in 2 minutes, so you can go from install to shipping in minutes.
Tag your files. Choose your model. Review the output.
Less prompting. More building.
Try Neo for VS Code & Cursor Today👇
VS Code: marketplace.visualstudio.com…
Cursor : open-vsx.org/extension/NeoRe…

Neo AI retweeted
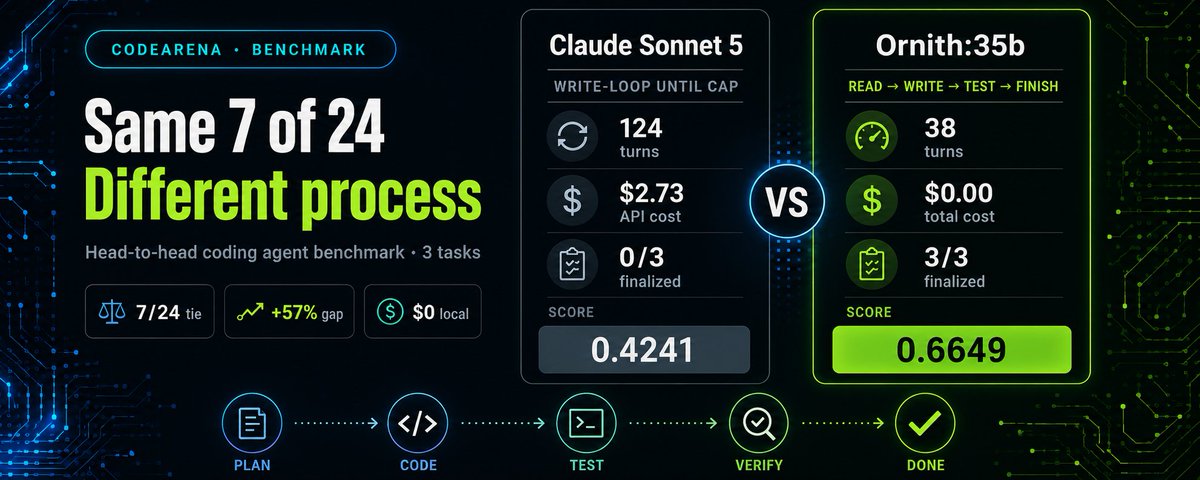
Kimi K3 is now available in NEO.📢
It surpasses the majority of leading frontier models on coding benchmarks and has performed exceptionally well on AI engineering tasks in our internal evaluations.
You can now use:
• Kimi K3
• GPT-5.6 series
• Fable 5
Simply bring your own OpenRouter, Anthropic, or OpenAI API key (BYOK), select your model, and you're ready to go. Same AI engineering workflow in NEO, different model powering it.
Why Kimi K3?
We benchmarked it against GLM 5.2 on a real-world AI engineering task: building a complete AutoML framework from scratch.
Both models produced passing test suites, but only one produced correct results.
Kimi K3 caught the data leakage that gave GLM a suspiciously perfect score, and it finished at 68/100 vs 54/100 on our production rubric.
Full Benchmark 👇

Kimi K3 is now available in NEO.📢
It surpasses the majority of leading frontier models on coding benchmarks and has performed exceptionally well on AI engineering tasks in our internal evaluations.
You can now use:
• Kimi K3
• GPT-5.6 series
• Fable 5
Simply bring your own OpenRouter, Anthropic, or OpenAI API key (BYOK), select your model, and you're ready to go. Same AI engineering workflow in NEO, different model powering it.
Why Kimi K3?
We benchmarked it against GLM 5.2 on a real-world AI engineering task: building a complete AutoML framework from scratch.
Both models produced passing test suites, but only one produced correct results.
Kimi K3 caught the data leakage that gave GLM a suspiciously perfect score, and it finished at 68/100 vs 54/100 on our production rubric.
Full Benchmark 👇

Thinking about migrating to a Mixture-of-Experts model but worried about hidden latency spikes?
Get hard numbers on cost and speed before you make the switch.
Introducing the MoE Cost Analyzer : An open-source tool built autonomously by NEO, that definitively benchmarks Dense vs. MoE models.
It measures real latency, token counts, and actual dollar costs using live API calls via OpenRouter.
Check out what makes this analyzer so powerful👇
While MoE models are typically cheaper and faster because they activate fewer parameters per token, performance under stress like P95 latency and your specific traffic patterns can change the results.
Do not rely on generic snapshots, run the MoE Cost Analyzer to get a customized recommendation that actually applies to your production needs! 🚀
Access the full project here: github.com/dakshjain-1616/Mo…
You can also build with NEO in your IDE
VS Code: marketplace.visualstudio.com…
Cursor: open-vsx.org/extension/NeoRe…
You can use use NEO MCP with Claude Code: heyneo.com/claude-code


Stop paying for GPT-4 on every request. Route intelligently.
A user asking "what is 2+2?" and a user asking "find the bug in this recursive async Rust function" both hit the same endpoint.
If you route them both to GPT-4o, you're paying $15/million tokens for arithmetic. 💰
If you route them both to a local model, your complex debugging answers are weak and users churn.❌
Meet Neural UCB Router: A production-quality OpenAI-compatible API proxy that uses the NeuralUCB multi-armed bandit algorithm to dynamically route requests to the cheapest model while retaining 92%+ quality.
Built autonomously by NEO
Here is how it routes under the hood👇
How it Works
Instead of relying on rigid rules or expensive pre-labeled datasets, it learns optimal routing on the fly:
✅No upfront training: It generates its own training signal by testing models on live traffic and observing the outcomes.
✅Deep context awareness: It instantly analyzes 15 different dimensions of every incoming prompt, such as prompt length, task type, and system prompts.
✅Smart exploration: Models that the router is uncertain about get a temporary "exploration bonus" (Upper Confidence Bound). Once it maps a model's true capabilities, a lightweight neural network takes over.
✅Lightning-fast learning: The system converges and learns your optimal routing patterns in just ~500 requests.
Drop Neural UCB Router into your existing setup and instantly stop overpaying for simple queries.
Access the full project here: github.com/dakshjain-1616/ne…
You can also build with NEO in your IDE
VS Code: marketplace.visualstudio.com…
Cursor: open-vsx.org/extension/NeoRe…
You can use use NEO MCP with Claude Code: heyneo.com/claude-code

Stop wasting $10,000+ a month on idle H100s
Right now, teams are forced to either overprovision to stay safe, or underprovision and risk waking up to 3 AM on-call pages due to latency SLA breaches.
Meet Infra Sizer - LLM Inference Infrastructure Planner, built autonomously by NEO
A CLI that takes a model ID, expected request volume, latency SLA, and context length - then outputs a concrete GPU recommendation: instance type, count, serving framework, batching config, and monthly cost estimate.
Here is how it works👇
Just throw it on an A100" is the most expensive mistake in AI infrastructure.
The right hardware choice depends on model size, throughput requirements, latency SLA, and cost constraints - all at once.
This tool does that math in seconds so you can make an informed decision before signing a cloud contract.
Access the full project here: github.com/dakshjain-1616/in…
You can also build with NEO in your IDE
VS Code: marketplace.visualstudio.com…
Cursor: open-vsx.org/extension/NeoRe…
You can use use NEO MCP with Claude Code: heyneo.com/claude-code

Grok 4.5 from @xai is now available via Openrouter in Neo.
In our recent eval, we used Grok 4.5 in Neo's VS Code extension, using BYOK (Bring your own LLM Key) method, to profile the decoder in Qwen 3 ASR and it performed the entire task in one shot with no errors.
See how you can use Grok 4.5 LLM within Neo:
heyneo.com/bring-your-own-ll…