
NYU master @agentic_ai_lab |Undergrad @sysu_1924
Joined August 2023
- Tweets15
- Following57
- Followers11
- Likes28
Zhenbang Yang retweeted

New from our lab, led by @Jacklu_me and @yangzb159 with @yanii’s group at @UCalgaryML: zeroing <0.1% of an LLM’s weights matches full fine-tuning at scale and avoids forgetting!
The Surprising Effectiveness of Deleting Weights in LLM Post-Training ✂️: arxiv.org/abs/2611.10866


Even the simplest weight edit, a deletion, can teach an LLM new skills!
Meet Deletion Tuning (#NeurIPS2026): just zeroing <0.1% of weights matches full fine-tuning's accuracy at scale. It's thousands of times smaller and avoids forgetting, a step toward continual learning. 🧵👇
Zhenbang Yang retweeted

Even the simplest weight edit, a deletion, can teach an LLM new skills!
Meet Deletion Tuning (#NeurIPS2026): just zeroing <0.1% of weights matches full fine-tuning's accuracy at scale. It's thousands of times smaller and avoids forgetting, a step toward continual learning. 🧵👇
Zhenbang Yang retweeted

PRO TIP: search for robotics papers on rednote (chinese instagram).
unlike X, which has a lot of noise, here u get detailed paper breakdowns, robot demos and great discussion in comments.
the chinese robotics scene is at the frontier, and going on rednote is like accessing their private group chat
(p.s. for better results search in chinese instead of english)

Zhenbang Yang retweeted

Deconstructing Scaling Laws: The Triad of Optimization, Architecture, and Data
kexue.fm/archives/11833
Zhenbang Yang retweeted
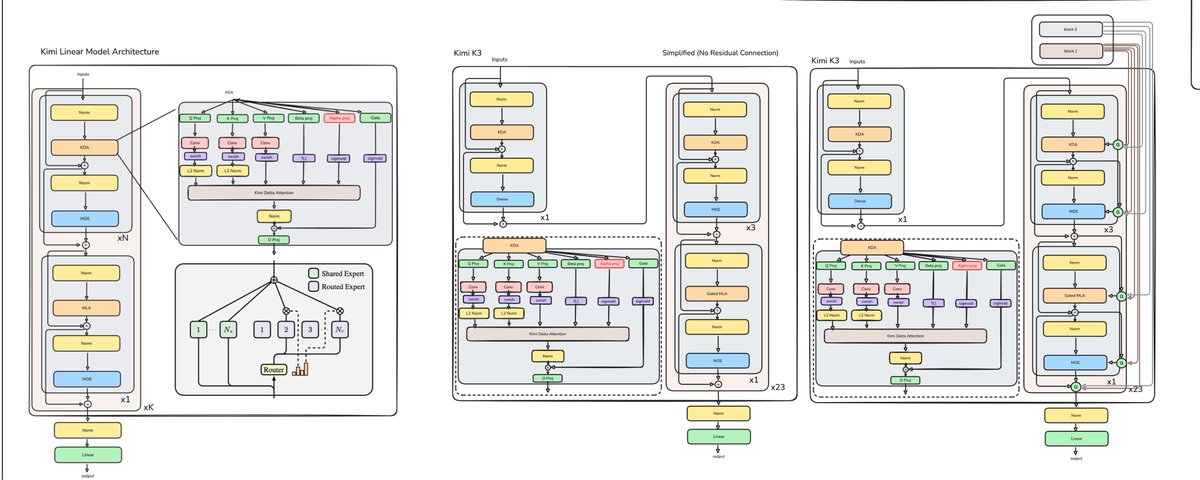
A Brief Look at K3's MoE and Attention
kexue.fm/archives/11848

Zhenbang Yang retweeted

Warm take: Your world model should never stop learning
Introducing AdaJEPA, an adaptive WM that plans, acts, and adapts in a closed loop. Every action leads to a new observation, and every transition refines the latent representation and prediction.
📝: agenticlearning.ai/adajepa/

Zhenbang Yang retweeted
Happening soon @ 2pm Room 318!
Surprising result: matching post-training gains with just weight pruning.


Bit-Mask Tuning: The Surprising Effectiveness of Deleting Weights in LLM Reasoning and Adaptation
@Jacklu_me @yangzb159 @yanii @mengyer
We show that deleting <0.05% of the weights can unlock full post-training performance.
openreview.net/pdf?id=Jnfolz…

Zhenbang Yang retweeted
Bit-Mask Tuning: The Surprising Effectiveness of Deleting Weights in LLM Reasoning and Adaptation
@Jacklu_me @yangzb159 @yanii @mengyer
We show that deleting <0.05% of the weights can unlock full post-training performance.
openreview.net/pdf?id=Jnfolz…
Zhenbang Yang retweeted

Giving a keynote on "Always Learning Machine" at the Global AI Frontiers Symposium in Seoul.


Zhenbang Yang retweeted
Context Tuning accepted to ICML 2026 🎉
See you in Seoul.
arxiv.org/abs/2507.04221
It’s a neat LLM adaptation method with minimal implementation overhead and great scaling behavior. Hoping to add it in the PEFT library, and will do a follow-up post with lots of new results.
Also excited to share my new LLM reasoning/adaptation work 🔜

This quoted post is unavailable.
Zhenbang Yang retweeted
What does it mean to create a new concept rather than retrieve a familiar one?
I propose that creativity is what's unfamiliar at first but quickly learnable by an adaptive observer, and show that meta-learning through a frozen Diffusion model produces stylistic & conceptual creations.


Zhenbang Yang retweeted

LoRA makes fine-tuning more accessible, but it's unclear how it compares to full fine-tuning. We find that the performance often matches closely---more often than you might expect. In our latest Connectionism post, we share our experimental results and recommendations for LoRA.
thinkingmachines.ai/blog/lor…

Zhenbang Yang retweeted
For too long, users have lived under the software lottery tyranny of fused attention implementations.
No longer.
Introducing FlexAttention, a new PyTorch API allowing for many attention variants to enjoy fused kernels in a few lines of PyTorch.
pytorch.org/blog/flexattenti…
1/10
