

Research MSc @Mila_Quebec @mcgill_nlp | Research Fellow @RBCBorealis | reasoning and hallucination x evaluation and interpretability
Canada
Joined March 2020
- Tweets102
- Following350
- Followers188
- Likes336




Pinned Tweet
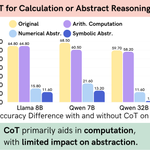
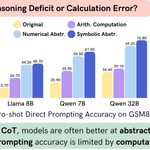
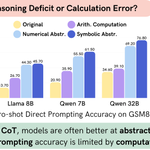
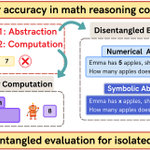
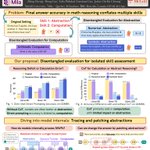
1/N Why do LLMs fail at math word problems without CoT?
🔍Final-answer accuracy alone doesn’t tell the full story.
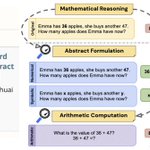
💥It’s not that they can’t understand the problem, the major bottleneck is doing the calculations correctly.
📌Read our EMNLP main paper: aclanthology.org/2025.emnlp-…
Ziling Cheng retweeted

Much of business analysis and social science is extreme drudgery: a demographic researcher might need to pull data from hundreds of sources to study population trends, before starting the actual analysis!
We formalize this overlooked step as SODIUM, where the open web is treated as a latent database.
Existing state-of-the-art AI agents perform poorly on SODIUM tasks: the best performing agent (AG2) achieves only 46% of accuracy. Our SODIUM-Agent achieves over 90% accuracy, outperforming state-of-the-art AI agents by 2x-73x.
1/8

Ziling Cheng retweeted

I'll be attending #ICLR2026 next week to present my work on In-Context Algebra! My poster will be on Fri, April 24 at 3:15-5:45PM at Pavilion 4 P4-#4011. If you're around, stop by and say hello! My DMs are open if you want to connect or meet up in Rio!


Ziling Cheng retweeted

New paper: Convergent Evolution: How Different Language Models Learn Similar Number Representations.
Language models, classical word embeddings, and even raw token frequencies all develop the same Fourier features for numbers. But only some develop the underlying structure. 🧵

Ziling Cheng retweeted

Latent CoT is an alternative LLM reasoning scheme hypothesized to enable “superposition” allowing models to hold uncertainty over multiple concepts during reasoning 💭
We revisit superposition in 3 latent CoT approaches and find that it is largely an illusion 🔮!
More in 🧵

Ziling Cheng retweeted

At #EACL2026 to present our work teasing apart exemplar- and abstraction-first accounts of learning in LMs by looking at behaviour during training! (w/ @chrmanning)
Paper: arxiv.org/abs/2603.17475
👀 Abstraction drives language learning!
🕐 Pavillon de Rabat, Apr. 25, 4:30PM


Ziling Cheng retweeted

🚨New paper
Are visual tokens going into an LLM interpretable 🤔
Existing methods (e.g. logit lens) and assumptions would lead you to think “not much”...
We propose LatentLens and show that most visual tokens are interpretable across *all* layers 💡
Details 🧵

Ziling Cheng retweeted

🚀 Safer & less over-refusal LLMs without retraining? Yes, it’s possible. We need a good context.
Here’s a simple but powerful idea for LLM safety without further training your models 👀🧠
(arxiv.org/abs/2512.11986)
Ziling Cheng retweeted

One of the first papers I contributed to was published at #BlackboxNLP 📃, what an honor to, 6 years later, give a keynote at this wonderful venue 🧡 Thanks for having me! #EMNLP2025

Our second keynote of the day has just started! @vernadankers is now presenting "Memorization: Myth or Mystery?"

Ziling Cheng retweeted

Make sure to go to Verna‘s keynote on memorization if you are at #EMNLP2025 🚨 You will leave with a different perspective on the topic, I promise 💭

Ready for day 3 of #EMNLP2025 🎉🎉 I've been on the lookout for memorization, unlearning, interp, memory module papers & more, chat w me if these topics fascinate you too😻 Looking forward to more of Suzhou, the conf & my BlackboxNLP keynote Sunday 1.45PM! blackboxnlp.github.io/2025/


This is happening to at board #20! Come chat about reasoning x interpretability ;)

Ever wonder why math reasoning fails without CoT? The bottleneck isn’t “abstraction” but “calculation”. I’ll be presenting at COLM on Friday (11–12) — come chat about reasoning × interpretability!
@Mila_Quebec @RBCBorealis
🔗arxiv.org/pdf/2505.23701
#COLM2025 #EMNLP2025

Ziling Cheng retweeted
Ready for day 3 of #EMNLP2025 🎉🎉 I've been on the lookout for memorization, unlearning, interp, memory module papers & more, chat w me if these topics fascinate you too😻 Looking forward to more of Suzhou, the conf & my BlackboxNLP keynote Sunday 1.45PM! blackboxnlp.github.io/2025/
7/N Can we steer model behaviours by injecting internal abstraction representations?
Using cross-problem patching, we show that abstraction representations are transferable.
For example, injecting the “subtraction” logic from P2 can turn the answer of P1 from 5 + 3 → 5 − 3.

2
1
91
8/8 Huge thanks to my collaborators @Meng_0209,@yanshuaicao and Leila Pishdad, and my advisor Jackie Cheung for their guidance and support throughout this work, and to friends at @Mila_Quebec @McGill_NLP.
@RBCBorealis @emnlpmeeting
1
119
