

Professional AI tab hoarder. Daily news, new tools, and the occasional "wait, what?"
Joined October 2026
- Tweets547
- Following70
- Followers73
- Likes1.3K




Cortexx retweeted

Tonight SpaceX tries to catch both Starship stages. A first for any orbital rocket.
Same month, on the ground:
• a 6 GW AI campus in Arizona, 2.5x all Phoenix-area data centers
• a ~$24B compute site with its own gas plant at Starbase
The rocket might be the side project now
Cortexx retweeted

Haiku went from 19.7% to 41.2% on BrowseComp when Opus was allowed to advise it.
In Claude Code that's one flag:
claude --model claude-haiku-4-5 --advisor opus
Haiku does every turn. At the hard calls it pings Opus, Opus reads the whole session and sends back a plan, a fix or a stop. Opus never calls tools.
Claude decides when to ask. In practice:
> before it locks a plan
> when the same error shows up twice
> before it calls the task done
What most posts get wrong:
> those numbers are Haiku 4.5 + Opus 4.6 from Anthropic's April launch, not the 5.5 models
> the docs list Haiku 4.5 as the Haiku main model that supports an advisor, so pin it by ID
> against Sonnet alone it scores 29% lower but costs 85% less per task
3 things worth knowing:
> /advisor opus saves it as your default, --advisor lasts one session
> ctrl+o on the "Advising" line shows what Opus actually said
> subagents inherit the advisor
Where it breaks:
> Anthropic API only, no Bedrock, Vertex or Foundry
> every advisor call rereads the full transcript, long sessions add up
> want the best score instead of the cheapest: Sonnet main, Opus advisor
Cortexx retweeted

Google just did something I didn’t expect
It rolled out Gemini 4 Carbon worldwide, its strongest model yet. Then it said most people should keep using the older one, Gemini 4 Argon, for everyday work
Carbon is built for the hard stuff: multi-step coding, science, security. Early users found zero-day vulnerabilities with it in a short time. Google is also giving 10,000 scientists six months of free access
The pace is the crazy part. Argon came out only two weeks before Carbon
Two weeks
So the question is no longer "which AI is the best?" It’s "which one do I actually need for this task?"
Strongest model, or the one that’s good enough?

Cortexx retweeted
Microsoft 365 went down for nearly 10 hours. Outlook, Teams, SharePoint, Copilot.
No cyberattack. No hackers.
Microsoft’s own servers started failing automated health checks. As more servers went offline, the remaining ones became increasingly overloaded.
Restarts didn’t solve it. Servers came back, then went down again as traffic returned.
Even ChatGPT and Claude’s Microsoft 365 connectors stopped working.
Now AI agents are being wired into banking, healthcare and logistics. All increasingly dependent on the same cloud infrastructure.
Yesterday, it was email.
What happens when it’s something we can’t afford to lose?
Cortexx retweeted

I asked Fable 5.2 for a video with music. It built the instrument first
It’s a marble machine in 3D. A sloped belt carries 244 marbles toward the edge, and each one drops onto a metal bar, a bass bar, a drum or a cymbal. The belt works as the sheet music, so you can read the next 3 seconds of the song on it before you hear them
There is no audio file anywhere. The sound is synthesized from the same list of 244 notes that moves the marbles, which is why every note lands on the exact frame of its impact. 13 bars at 100 BPM, 4 chords, and a run of 60 marbles in 9.6 seconds near the end
No samples, no 3D models, no libraries. From my message to the finished video took 45 minutes, and about 30 of those were rendering
Cortexx retweeted

The same task cost eight dollars one way and four the other. Nothing about the work changed.
Run A keeps the expensive model in the loop every single turn. Run B lets the cheaper model do the work and only calls the expensive one at decision points, as an advisor. Same job, same output, half the bill.
That is the whole agent cost problem in one screenshot. It is almost never the model you picked. It is how many times you asked it something it did not need to answer.
Where in your setup is the expensive model answering questions it should not be seeing?
Cortexx retweeted

This snake eye is 5,631 scales and one equation for light.
No textures, no 3D model, no stock footage. Every pixel is computed live in a browser tab.
What’s actually on screen:
> The iris is three layers of radial fibers, a branching crypt network and gold flecks, generated pixel by pixel
> The cornea isn’t painted on. Every pixel traces a ray through it at n = 1.376, so the iris shifts and bends as the camera swings past
> The slit pupil is two intersecting circles. It narrows from wide open to a thin blade when the light hits
> 5,631 scales, each placed by code with its own tilt, color and overlap, plus four rings of tiny scales around the eye
> Then the camera pulls back and you see the whole head
Hit record and it exports the video straight from the browser.
How it’s built, with all 7 prompts, is in the article 👇


Cortexx retweeted

Most AI video generators completely fall apart when trying to simulate realistic wind-blown sand dunes, complex particle dynamics, and epic scale transitions.
I tested GPT-6 Astra against Opus 5.5 on an atmospheric desert artifact prompt.
One model delivers cinematic wide-angle storytelling with moody atmospheric text rendering. The other focuses on raw dynamic sand displacement and high-speed asset velocity.
Which desert landscape simulation feels more alive to you? Drop your pick below👇

Can AI replicate the exact arcade physics of a classic 2D endless runner?
I generated a Jetpack Joyride-style level in both engines.
One nailed the vibrant sci-fi corridor aesthetic and particle trails.
The other went for a neon night atmosphere with laser obstacles.
Which gameplay loop feels smoother to play? Tell me below?


Cortexx retweeted

Same footage. Completely different viewing experience.
The raw clip is just someone talking to a camera.
The edited version adds motion graphics, animated text, and visual explanations.
This is where AI-assisted editing gets interesting.
Not replacing the person on camera, but making what they're saying much easier to watch.
And potentially cutting hours of editing work.


Cortexx retweeted

Took the sci-fi interface experiment to a real planet this time.
TRAPPIST-1e is about 40 light-years away and almost the size of Earth. Its year lasts 6 days, and one side probably faces its star all the time. JWST still hasn’t confirmed whether it has an atmosphere.
I had Opus 5.5 build a survey screen for it anyway. The camera goes from orbit to a scan, down to coastline maps, a research outpost and a glacier ridge, then back out.
Cortexx retweeted

Four AIs judged each other. One judged itself a little too generously.
A year ago Karpathy's LLM Council picked GPT 5.1 as the best model and Claude as the worst. I reran it with ChatGPT, Claude, Grok and Gemini (default models), with the answers anonymized.
→ all four solved the trick question
→ Gemini ranked its own answer last
→ ChatGPT ranked its own advice #1, and the other three ranked it last
→ final order: Claude, Grok, Gemini, ChatGPT, the same even without self-votes
Claude also remembered who I was, which probably helped on one question. 3 questions and 4 judges, so it's a vibe check.
The animation is pure code, built by Claude Opus 5.5 from one prompt.

As a fun Saturday vibe code project and following up on this tweet earlier, I hacked up an **llm-council** web app. It looks exactly like ChatGPT except each user query is 1) dispatched to multiple models on your council using OpenRouter, e.g. currently:
"openai/gpt-5.1",
"google/gemini-3-pro-preview",
"anthropic/claude-sonnet-4.5",
"x-ai/grok-4",
Then 2) all models get to see each other's (anonymized) responses and they review and rank them, and then 3) a "Chairman LLM" gets all of that as context and produces the final response.
It's interesting to see the results from multiple models side by side on the same query, and even more amusingly, to read through their evaluation and ranking of each other's responses.
Quite often, the models are surprisingly willing to select another LLM's response as superior to their own, making this an interesting model evaluation strategy more generally. For example, reading book chapters together with my LLM Council today, the models consistently praise GPT 5.1 as the best and most insightful model, and consistently select Claude as the worst model, with the other models floating in between. But I'm not 100% convinced this aligns with my own qualitative assessment. For example, qualitatively I find GPT 5.1 a little too wordy and sprawled and Gemini 3 a bit more condensed and processed. Claude is too terse in this domain.
That said, there's probably a whole design space of the data flow of your LLM council. The construction of LLM ensembles seems under-explored.
I pushed the vibe coded app to
github.com/karpathy/llm-coun…
if others would like to play. ty nano banana pro for fun header image for the repo

Cortexx retweeted

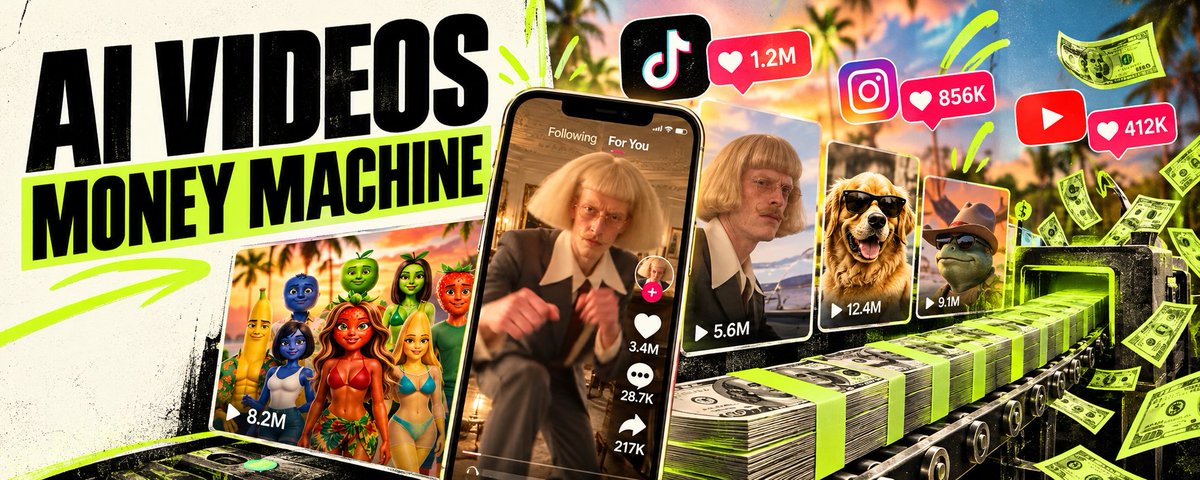
AN AI CHARACTER JUST DID 104M VIEWS WITH A REEL CALLED "KEEP THE CHANGE".
Abdul El Salladi. Bowl cut, big mustache, white thobe, made with AI. In this one he runs across the hoods of a Rolls-Royce, a Lamborghini and a Ferrari, then jumps onto the wing of a private jet. 14 seconds.
378K followers, 129 posts, follows nobody. That 104M reel also pulled 4.6M likes, and at least 27 more of his reels passed 1M.
His bio is just "YOLO. I am the best!" No brand, no shop, no pitch. The character is the product, and every reel is the ad.
Risk: one-joke characters burn out. The real test is what he does after the 100th car jump.
What would you sell with 104M views on one reel?


Cortexx retweeted

i made 16 famous prompt tricks write AI bots. then i made the bots fight to the death
same model (Opus 5.5), same task: code a bot for a 16-player light-trail arena. only one line of the prompt changed. 3 bots per trick, 48 bots, 300 matches
> "ultrathink" won. but it cost 0.44$ a bot and took over 3 min
> "think step by step" came 2nd, 0.7 points behind, for 0.11$ and 49 sec
> "please" and "thank you" came 3rd. no idea why either
> "you are a senior engineer": 7th
> no trick at all: 8th
> "i'll tip you 200$": 9th, below no trick
the bottom 4: "YOU MUST WIN", "you'll be shut down", "this is very important to my career" and "plan first"
all four lost the same way. one of their 3 bots ignored the 10 ms limit, took 100-350 ms a move and usually crashed by move 20. an average bot lived 200+
no other bot crashed that early. the next worst lived ~130 moves