

Tracking AI & Technology With Caduceus: 🔗 https://xitter.gq/t.co/xPOhLouCXA
@caduceusvisuals
Joined September 2021
- Tweets12.9K
- Following304
- Followers438
- Likes14K






Apollo retweeted

Genie 4 is now available in Project Genie.
It brings native audio, real-time editing, and a new agent to help you create interactive, virtual worlds.
Apollo retweeted

BREAKING 🔥: Google has announced Loop, a new Stitch experiment.
Loop is an AUTONOMOUS AI agent that handles a full cycle from product discovery to implementation and monitoring.
This is a new type of solution that can improve your product on its own, with the user's role boiled down to setting goals (loops), reviewing outcomes, and making decisions.
I've been testing Loop for weeks, powered by Gemini 3.8 Flash, and I'm super keen to see what it can do with Gemini 4 models.
Waitlist time! 👀
Apollo retweeted

Working with @AMD, our models identified up to 14% PPA improvement on flagship GPU IP in less than five months—building on designs AMD’s engineers had already spent years optimizing.
The same approach helped improve Jalapeño, our first custom inference chip, with gains verified on real silicon.
New evaluations also show our models getting better at certain chip design tasks.
We’re sharing these results and how we’re working with @Synopsys to bring our model capabilities and their trusted EDA design and validation tools to more chip designers.
openai.com/index/advancing-c…


Apollo retweeted
Mistral Vibe is now available on Desktop!
Run agents locally or remotely, and start shipping straight from your MacOS or Windows device.
You can try the Pro plan for free if you’re building in Europe. Coupon code: LECHONK
(yes, we added more after we ran out yesterday).
Use the link in 🧵:
Apollo retweeted

InclusionMed launches as the first independent evaluation and analysis platform for medical AI, co-developed by 29 institutions including Stanford, Harvard, Peking Union Medical College and Ant Group. In InclusionMed, we evaluates not just how models score, but who they serve and what they can actually do.
The platform introduces two tools:
· Atlas: a nine-cell benchmark map that organizes evaluations by audience and capability.
· Index: a composite score aggregating results from its first evaluation cycle of 1,034 tasks and 22 models.
Homepage:inclusionmed.ai/
GitHub:github.com/panuvi/inclusionm…


Apollo retweeted

GPT-6.2 Astra for Law is SOTA on legal intelligence:

The new Astra for Law (built on 6.2 Astra) leads on legal intelligence! Now available for all ChatGPT Enterprise customers via the Trusted Access Program.
openai.com/index/astra-law-6…
Absolutely GOATed work by the research team to get the pareto curve to look like this:

Apollo retweeted

Hy4 flash is now open-weight, including Hy4 flash-FP8 and Hy4 flash-Base.
224B (12B active), 1M context, natively multimodal.
Fast, efficient and built for everyday productivity.
It's yours now. And stay tuned for Hy4 coming up next!
🤗: huggingface.co/tencent/Hy4-f…
🐙: github.com/Tencent-Hunyuan/H…
📄: hy.tencent.ai/research/hy4-f…
Released under the Tencent Hy License.
See full terms here: huggingface.co/tencent/Hy4-f…

Apollo retweeted

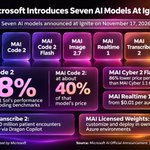
MICROSOFT ANNOUNCES 6 NEW AI MODELS AT IGNITE
$MSFT unveiled six MAI models across coding, cybersecurity, image generation and voice on the same day its partner OpenAI released GPT-6.2.
1) MAI Code 2: Delivers 98% of GPT-6.1 Sol's performance at 40% of the cost. Now in GitHub Copilot.
2) MAI Code 2 Flash: Outperformed GPT-6.1 Sol in AT&T testing while costing 50 times less.
3) MAI Cyber 2 Flash: Outperformed GPT-6 Astra on a cybersecurity benchmark at less than 2% of the cost per task.
4) MAI Realtime 1: Outperformed GPT Realtime 2.1 on public benchmarks and Microsoft's own evaluations.
Microsoft is also launching MAI Image 2.7 in public preview and bringing MAI Transcribe 2 to Dragon Copilot for medical use cases.
Separately, Microsoft says it is making progress on its own general-purpose frontier AI model.

Apollo retweeted

Today we’re announcing the general availability of Microsoft-Decision-1.1, with greater intelligence, better calibration and more than twice the speed of our first model, at a low cost.
commandline.microsoft.com/mi…

Apollo retweeted

GPT-6.2 Astra and GPT-6.2 Sol
They have the highest error rate of any model so far on VoxelBench 2
19 from GPT-6.2 Astra, 62 from Sol
All of these failures are either syntax errors or other dumb mistakes like forgetting to define something for something

Apollo retweeted
Introducing MAI Code 2 and Code 2 Flash.
Code 2 brings frontier price-performance for everyday enterprise coding tasks.
Code 2 Flash brings affordable and high-quality coding for routine work at scale.
Try both today in GitHub Copilot.
Apollo retweeted
Teaching robots new tasks just got a lot faster. 🤖
With Gemini 4 Hydrogen and the new robotics plugin for Google @Antigravity, you can connect a supported arm, practice in @MuJoCo simulation, and run tasks in the real world using plain conversation.
Apollo retweeted

OpenAI’s release of GPT-6.2 Astra and GPT-6.2 Sol delivers the #2 model in the Artificial Analysis Intelligence Index and most of the Cost per Task Pareto frontier
@OpenAI's GPT-6.2 Astra is priced at $8/$40, 20% below GPT-6 Astra, and cached input drops to $0.40 from $1.00 per million tokens. GPT-6.2 Sol pricing is unchanged from GPT-6.1 Sol, at $2/$10 per million input/output tokens.
Key takeaways:
➤ Second in Intelligence Index: OpenAI now trails only Anthropic’s Claude Fable 5.2 in the Artificial Analysis Intelligence Index. GPT-6.2 Astra jumps 5 points from GPT-6 Astra, overtaking Gemini 4 Carbon (60) and Claude Opus 5.5 (59) at their top effort settings. GPT-6.2 Sol gains 2 points at 57, placing it on par with GPT-6 Astra at ~15% of the Cost per Task.
➤ Occupies most of cost and output token frontiers: OpenAI models now occupy most of the Cost per Task Pareto frontier, sharing the frontier with only Anthropic and Meta. OpenAI also dominates the Output Token per Task Pareto Frontier, with Claude Fable 5.2 being the only model from a non-OpenAI lab appearing on the frontier.
➤ Strengths in science and knowledge: OpenAI performs strongly in both of our key science-focused evaluations, leading Terminal-Bench-Science 0.1, covering agentic scientific research workflows, and placing second only to Claude Fable 5.2 in CritPt v2 (hard subset), covering physics reasoning. GPT-6.2 Astra performs below only Claude Fable 5.2 in factual knowledge as measured by AA-Omniscience v1.1 Accuracy, and in HLE-Diamond, a reasoning and knowledge benchmark.
➤ Leading in 3D and robotics: GPT-6.2 Astra leads AA-3D at 1318, with Claude Fable 5.2 at 1271 and GPT-6.2 Sol at 1259. This benchmark measures how well models build interactive 3D experiences, and is rated by human graders. GPT-6.2 also leads AA-Robotics v0.1, our research preview measuring how well language models can understand, plan, and act in the real world. GPT-6.2 Astra and GPT-6.2 Sol scored 79 and 78 respectively, ahead of Claude Fable 5.2 at 75. Our team is hard at work adding more difficult tasks, as OpenAI and Anthropic models can now perform the majority of basic tasks in this initial research preview.
➤ No improvement in Coding Agent Index: GPT-6.2 Astra is flat with GPT-6 Astra, and GPT-6.2 Sol loses 3 points relative to GPT-6.1 Sol in the Artificial Analysis Coding Agent Index (Codex harness at max effort). For Sol, the drop is driven by a 14-point drop in SWE-Atlas-QnA-AA, where the model is more likely than its predecessor to omit key facts in its responses. Cost efficiency however does place several effort levels of GPT-6.2 Astra and Sol on the Pareto frontier for Cost per Task.

Apollo retweeted
Some of you have been asking very politely. Some of you have just been asking.
GPT-6.2 Astra and Sol are now available.
Super efficient and built to perform where it counts—the real world.
openai.com/index/introducing…
Apollo retweeted

Apex 35B V1.0 🔥 First model from a new player Apex Intelligence
- 35B/A3B ( Built on Qwen 3.6 35B/A3B )
- Apache 2.0
- RSI driven training and optimization
- 262K context
- GGUF available


Apollo retweeted

Looking forward to Ignite, kicking off today at 10am PST! Hope you’ll join us live. xitter.gq/i/events/2116180615661…
