





I found the same thing, Astra is in a league of its own for reviews and finding bugs. xitter.gq/cutzilla/status/212282…

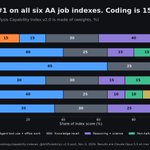
I tested GPT-6.2 Astra on real work. 2 repos, 105 replanted bugs. Find and fix what you can.
It's the new #1. The results:
- GPT-6.2 Astra (max): 62.7 for $28.35
- GPT-6.2 Astra (xhigh): 60 for $23.53
- Fable 5.2 (max): 58 for $139.65
- Gemini 4 Carbon (high): 57.3 for $31.32
- Sonnet 5.5 (max): 51.3 for $154.03
- GPT-6 Astra (max): 45 for $33.03
From GPT-6 Astra to GPT-6.2 Astra: +17.7 points at max, +17 at xhigh.
Whatever people say about other use cases, it's a code review beast.
GPT-6.2 Sol and more effort levels drop soon in the thread 🧵

1
1
31
So far 6.2 Astra is an improvement by my tests and 6.2 Sol is a regression. Astra def the best review model for me.
1
1
59
Cutzilla retweeted

Some of you have been asking very politely. Some of you have just been asking.
GPT-6.2 Astra and Sol are now available.
Super efficient and built to perform where it counts—the real world.
openai.com/index/introducing…


For anything creative or requiring judgment...Fable is leagues better than Opus; I've put them head-to-head for the past few days, and it's not close.
2
52
Kinda excited for this

Qwen4 is coming.
Deeper knowledge. Richer world understanding. Stronger coding and agentic capabilities.
Built for real-world tasks — from complex coding and knowledge work to front-end builds and professional software workflows.
Qwen4-Max is now in preview on Alibaba’s Token Plan. You can also get early access to the new model on QwenWork, Qoder, Qwen APP, and QwenStudio.
Put it to the test on a real problem. Show us what you build. 👀
Token Plan: qwencloud.com/pricing/token-…

1
42

Let's go!

We've given all Pro, Max, Ultra, and Team users one free full reset, across all models and limits. Use it anytime before December 10 at 2:00PM PT.
We recently fixed a few small issues that used more limits than intended, and the Fable resets didn't do much for those of you who'd already hit your weekly limits for all models. While these issues didn't affect everyone, we want to make up for the trouble.
You'll find it in Settings > Usage, or at clau.de/reset.
29
Can't wait for more benchmarks, the king is here

Just got access to Fable 5.2 today, and immediately started benchmarking on @VulcanBench w/Frontier v4, safe to say, I think Fable 5.2 will mark the official sunsetting of this eval suite.
I've been working on Frontier v5 for over a month, getting closer, but not there yet.
That being said, just look at Fable 5.2 on Low effort compared to Fable 5.1. From ~26 min/task down to ~5 min/task, and from $183 to $41, this is a truly amazing model. Can't wait to do a deeper dive into the traces to see how it thinks under-the-hood.
More to come, this is just the first effort level, but I think Fable 5.2 will very likely get a perfect score on every one, which means, it's the model that puts Frontier v4 into retirement.
It was a good eval suite, but it has met it's match.
Live long and benchmark 🖖

1
2
119
Fable 5.2 solving problems no other models could for me. Also I'm enjoying the cli improvements from @ClaudeDevs even the simple one that pins the last message at the top as you scroll through
1
1
55


Cutzilla retweeted

Had a whole day of Opus 5.5 getting 3/10 to 4/10 on automated code reviews when it’d normally get to 7-9/10 on the second or third iteration.
“Don’t use your judgement. You’re slowing down progress you’re not going to make it. AI is vastly better than you at code and architecture” 🤔

noticed opus getting worse last month. same prompts, sloppier output, old mistakes coming back
that's the part nobody prices in. a closed lab can ship something incredible, then quietly dial back the compute or the thinking whenever they want. we're on their schedule
i can't wait for an open model i can actually trust. one that never gets worse behind my back, only better because i'm the one improving it
that day is coming. it's inevitable

After Anthropic killed Opus 5.5 I think people should be way more convinced
Open models and getting ready with them matter more than ever
No usage limits, no restrictions, no huge bills, and no nerfs
People deserve total sovereignty
1
3
68
been doing this on my mac mini. separate user that only has access to what it needs, tools installed from admin, screenshare when i need to change something. sandboxes always ended in yolo anyway, this actually holds

we should have just given agents an unpriv user on our PCs. it'd keep 99% of the isolation boundary you want without any overhead & every single OS is already multi-user. /home/claude, done.
sandbox/vms add too much friction, obviously everyone ended up with "yolo" (or auto-review which is pretty much "yolo")
1
2
67
This was one of the reasons I stopped using t3 code, more context was always added so idk how it's cheaper on usage, for example pi went from 500 tokens to 26k tokens on first prompt. I would love to see @PovilasKorop do some testing as I enjoyed his recent one on Claude vs. OpenAI $20/$100 subs comparisons.

2
2
94
I don't know if I will even get that experience I had working with Fable 5 for the first time, which was truly exceptional and shocking to have an agent that had that strong of judgment and coordination. I don't feel that the current Fable or other models compare.
1
42