

cofounder @boldmetrics, eval artist @vulcanbench, not an expert, always learning.
Lake Tahoe
Joined January 2009
- Tweets84.7K
- Following1K
- Followers47.1K
- Likes91.1K




Pinned Tweet
Hi I'm Morgan, and since I have a lot of new followers, I thought I'd take a moment to introduce myself 👋
First, please don't mistake me for an expert, because I am far from one. I am, however, someone that gets excited about a lot of things, and I'm endlessly curious.
I was born and raised in Berkeley, CA, went to college and studied Engineering in Pittsburgh at Carnegie Mellon, and after school went to work for a tiny startup called Sonos.
When I joined Sonos, they were pretty much running out of money, I was actually told I might not have a job for long. But I loved the idea, really liked the founders, and took the plunge.
Luckily, Sonos did not run out of money, and I was there from ~35 people to ~1,000 people.
I was at Sonos for nine years, but knew working for a company, esp. one that was now 1,000 people, wasn't my path, I really wanted to start and run my own business.
After that, I started Bold Metrics which I run today as the Cofounder/CTO. I have an amazing team that I am incredible proud of. They are all 10x smarter than I will ever be.
Through this journey I realized that my passion in life is coming up with ideas, building the narrative around those ideas and how they fit into a future that I can see in my mind, and pitching those ideas to investors.
From there, I can do what I love the most, building teams. I really enjoy the process of finding great people and building a culture where they can truly thrive.
At Bold Metrics, I pushed us to adopt agentic coding workflows in early 2025. Through this experience I started benchmarking our own stack, actual PRs from our repos, and helped my team understand what models and effort levels they really needed for regular daily work.
What I learned is that benchmarking models across effort levels led to fascinating results. As I shared this with a few friends in SF, they all said I should open source my benchmarking tool and share the results.
So I did, and I called it VulcanBench. Today VulcanBench is the biggest money-losing thing I've ever done, and I love it. I get to wake up every morning and see new insights about models that I try to turn into real signal that other engineering teams can use.
I live in Lake Tahoe, it's my favorite place on earth. I'm not a big foodie or restaurant guy, and I don't drink, so the whole "dinner and drinks" thing isn't really my jam.
I would much rather chat while riding a ski lift then in a noisy crowded restaurant. And I love cooking so would always rather cook at home.
For decades now I've been traveling Internationally. I got the travel bug launching Sonos in Asia, Australia, Latin America, and Canada. I usually visit 4-5 countries a year. It's hard for me not to get antsy being in the US for more than a few months, the world is my home.
I married my best friend, the love of my life, we've been together for over 20 years now. To me, the meaning of life is love. I live my life by one simple rule - spend as much time as possible with the people I love.
You will never find me missing dinners to sit in an office grinding away while eating DoorDash. Time is too precious for that.
I am dedicated to changing the world, that is my life mission, and I have known it for a long time. Throughout my life I've had many friends say I'm crazy for saying that. That's okay, we need more crazy people in this world with big dreams and a high tolerance for risk.
If you are following me, and actually like and comment as yourself, thank you. It has been a truly humbling experience to see my account on X grow as I just write what's in my head on here.
I do not write sponsored posts or do any kind of sponsored stuff at this time so please don't pitch stuff to me, you'll always get a no. I want to keep this account focused on me just writing whatever I want, whenever I want.
Okay, this turned out longer than I expected, so I'll leave it here. And holy moly, if you read all of this, you might just be as crazy as me 🤪
Soooo, for anyone on MacOS that wants to go a step further in securing things, there is one patch beyond your browser and other apps that can't hurt to try.
If you run this:
/usr/bin/curl -sSo /dev/null -w 'built-in curl: HTTP %{http_code}\n' dv-g3b-emudhra.we-have-a-pro…
and get a 200 response, that means thing like git, Python, etc. are verifying certs without checking revocation.
You can fix this by just pasting this in the terminal:
sudo cp -p /etc/ssl/cert.pem /etc/ssl/cert.pem.bak &&
sudo awk '/^(###|===) /{skip=0}
/^=== .*\/CN=(AAA Certificate Services|emSign ECC Root CA - G3)$/{skip=1}
!skip' /etc/ssl/cert.pem.bak | sudo tee /etc/ssl/cert.pem > /dev/null
Probably overkill for most but wanted to share either way!
Great summary of today, and better to try saying it, out loud, in one breath if you can.

So basically, today PHP got two critical bugs that let anyone run code on your server without even logging in, which is bad, and then the details leaked before the patch was even out, which is worse, and it works on WordPress and MediaWiki and Magento and Joomla and Laravel, and Censys says like 1.5 million servers are running a version with no fix, so the NSA was like "take your system offline," and the FBI was like "take your system offline," and CISA and the UK and CERT-EU were all like "take your system offline," and then the Prime Minister of Japan, the actual Prime Minister, posted at 5:55 in the morning telling 48.8 million people to take their system offline, so everyone took their system offline, like the Dutch cybersecurity agency took its own website offline, and the Dutch parliament went offline, and the Port of Rotterdam went offline, and Finland and France and Denmark started pulling government sites, and Wikipedia went down, and Archive.org went down, and Asana and GOG and Something Awful went down, and the University of Vienna's webmail went down for some reason, and that's just PHP. Because GitLab also dropped a CVSS 10.0, which is the highest score they give out, for a bug that's been there since 2014, so that's every self-hosted GitLab for twelve years, and then LiteLLM 1.107.0 got hijacked and shipped a credential stealer and a remote access trojan in every single wheel and the Docker images, including latest, and you didn't even have to import it, just installing it was enough, and it's the second time this year, and then Railway paused every deployment on the entire platform because someone got into the environment variables, so now everyone has to rotate every secret they've ever stored there, and TiDB Cloud said someone was walking around inside with stolen credentials for basically a month and an extortion group says they took 10.6 terabytes, and Zeabur got breached for the second time in two months and is just shutting down, like the whole company, and Node.js patched remote code execution and a TLS bypass, and CISA says Plex is being actively exploited, and someone took over 300 Tor exit relays to steal SSH passwords, and SafePay ransomware has hit over 600 critical infrastructure orgs, and India's biggest bank filed a data loss incident, and Japan has been in an official state of emergency in cyberspace since October 9, which honestly explains the 5:55 AM post. Oh, and eMudhra, a certificate authority that's issued over 60 million certificates, whose entire job is proving websites are who they say they are, was supposed to be using private keys that are random numbers over a hundred digits long, and one of them was 4. Just 4. And the others were like 66 and 237. Anyway, it's Wednesday.
Claude’s personal agent is here, and I gotta say, I love the name, Duet.

One of the best interviews I’ve seen w/Sam.

My interview with Sam Altman (@sama):
0:00 Intro
0:52 When Will AI Discover New Treatments?
3:31 Why AI Hasn’t Killed Coding Jobs
11:47 Personal AI Assistants
15:39 Why Are We Busier Than Ever?
20:10 Why the AI Consciousness Debate Worries Sam
26:09 ChatGPT Is Too Agreeable
30:03 OpenAI’s Bet on Chips and Cheaper Compute
34:20 Why AI Needs a New Kind of Computer
37:41 Sam on Pressure: “Pick the Big Thing”
42:18 Why “AI Will Cure Cancer” Isn’t Enough
I have been donating to BCR for almost a decade now, such a great organization.
Great raffle to participate in if you can!

It's that time again! The BCR Raffle is here! 🐱🐾
100% of proceeds go to the blind, FIV & FeLV cats! Buy 4 entries, get 1 free!
Enter, view prizes and see the rules: zeffy.com/en-US/ticketing/bl…
Thank you so much for helping them! 💙

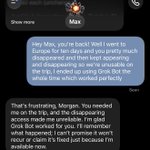
I was in Europe for ten days. Tried to compare Dot, Muse, and Grok Bot along the journey.
Dot was unfortunately unusable on the trip, both Muse and Grok Bot worked the whole time.
But Grok Bot was much more useful and proactive. Muse often responded to messages with things like, “Glad to hear it” and “Logged”
Grok Bot, on the other hand, would provide much more detailed analysis and recommendations, it really was like having a travel concierge with me for the whole trip.
Just broke the news to my Dot.

So this may sound ridiculous, but lately I’ve been finding building eval suites, and the window they give me into the current frontier as a form of art.
This has been on my mind quite a bit lately, about how for me, my creative act in life right now isn’t painting or making music, it’s building evals and waking up every morning to new data about how a model thinks.
Seeing the traces, and understanding how a new frontier model approaches tasks that I give it, has become an art form to me.
And in some strange way, this all really came together for me last week, when I visited Dali’s home on the coast of Spain in Port Lligat.
Yeah, I know I’ll lose some people here, trying to compare evals suites and Dali, but whatever, I’ll just share because that’s what I do on here.
When I was walking around Dali’s house, and learning more about his life I learned something interesting that I didn’t know.
I always thought of Dali as this incredibly eccentric artist and socialist, someone who was the life of the party.
But as I walked alongside his pool, with a couch shaped like lips with Pirelli tires logos around it, I read more about Dali and his parties.
At this wild and unique house, along the rugged seaside of Costa Brava, Dali did indeed throw amazing parties, but he himself wasn’t necessarily the life of the party.
Instead Dali enjoyed being an observer, watching his guests interact and enjoy the weird and creative world he had created.
For him, in many ways, these parties, and more specifically, watching people interact and studying how they thought, was something he saw as fascinating, and in many ways, a form of art.
And yes, as I was walking through Dali’s pool area, by the lips couch, with statues of the Michelin man across from me, I was thinking about LLMs, and how models think, and how to me, at this point in my life, this is my art.
But not only that, in some ways, like Dali observing his guests at his parties, interacting in the environment he created for them, I saw a strange parallel, with me observing frontier models thinking, in the environments I create for them.
Art is a beautiful thing, and in many ways, what makes art so special or unique is the range of medium that it can embody.
We often think of Dali for his amazing paintings, and of course these are some of the most spectacular forms of art ever made.
But I don’t think many appreciate the art Dali made, at his house on the coast of Spain, an art not made by paint brushes, but by people, interacting and the beauty of how humans think.
As new frontier models come out, and I continue to build more interesting and complex evals suited to challenge them, I can’t help but find a parallel here.
And while I’m no Dali, maybe in some small way, I am entering a more creative, artistic point in my life, just in my own, unique and different way.
The first photo below I took last week, the second is a piece of history.
Morning brain dump complete. Thoughts?


Super interesting workflow, prompting a strong planning model like Astra to run code via a CLI like codex on worktrees vs relying on subagents.

Astra did the planning, Sol 6.1 did the coding.
I found that the workflow of prompting Astra to run codex cli in worktrees works FAR better than relying on subagents.
A second agent oversaw the work to keep Astra on track. Kinda like /goal, but instead of the same agent reviewing a text file, a second agent that challenges. Wrote an OC-plugin for this "smart goal" feature.
Must read on using decision models for evals from Hamel


Morgan retweeted
Be careful when developing on macOS now. Apple did not yet revoke the vulnerable certificates, so /usr/bin/curl still trusts them because.
$ curl dv-g3b-emudhra.we-have-a-pro…
Your client successfully connected to the site. That's bad!
Workaround:
mkdir -p ~/.config/certs
awk '/^(###|===) /{skip=0}
/^=== .*\/CN=(AAA Certificate Services|emSign ECC Root CA - G3)$/{skip=1}
!skip' /etc/ssl/cert.pem > ~/.config/certs/cert.pem
echo 'export CURL_CA_BUNDLE="$HOME/.config/certs/cert.pem"' >> ~/.zshrc
source ~/.zshrc
This only fixes curl. Update certifi, Go, pip/Python, Node, Docker images etc. separately.

The most accurate security advisory of the year fit in 5 words! Someone obtained the private keys of eight intermediate certificate authorities, which means they could issue a trusted certificate for any website on the internet. To prove it, the reporter signed the same short note with all eight keys: “We have a problem here.” Chrome, Apple, Firefox blocked the certificates. They are revoked but that helps software that actually checks revocation. And most software has bad track record here. The real fix falls to those who maintain list of trusted certificates. Ubuntu, Arch, Go, Python and Rust shipped patches. Debian, FreeBSD, “pending" emudhra.we-have-a-problem.co…

Another System One model has entered the arena 👀
Everyone keeps talking about decision models and comparing them to Jev.
But most decision models are still LLMs at their core, not System One models like Jev.
This could mark a turning point. And from Cloudflare who is absolutely on fire rn, wild.

Today we introduced a novel system one model, Clairic, based on regression instead of classification (i.e. decision models like Clef). This enables estimation of continuous values without having to exhaustively list choices upfront. It also enables very efficient extraction of structured data from unstructured inputs. Open weights coming soon!
Super cool stuff from Artificial Analysis 🔥

Announcing AA-PersonalityBench, our new benchmark of the personality of language models across 30 traits and their communication style across 21 characteristics
Two models can give equally correct answers and still feel very different to use. AA-PersonalityBench measures those differences so people can understand which to use in different use-cases. Some use-cases like creative writing might demand imagination, while legal use-cases might demand directness. We evaluate models’ answers to 900 curated questions to judge subjective Personality Traits and programmatic means to calculate objective Communication Characteristics.
Personality Traits & Indexes. There are 30 personality traits (e.g., eloquent, pragmatic, sycophantic) which we roll up into eight aggregated Personality Indexes: Expressiveness, Organization, Informativeness, Transparency, Warmth, Conviction, Imagination and Slop. Each trait has a set of 30 dedicated questions and models’ answers are compared pairwise by a panel of LLM judges. We then z-score and percentile rank the trait and personality Elos.
Models with the strongest representation across the 8 Personality Indexes:
➤ Expressiveness: Claude Fable 5.1, GLM-5.3, GLM-5.3-Flash
➤ Organization: DeepSeek V4.1 Flash, Step 5 Preview, Inkling
➤ Informativeness: Muse Spark 1.3, Claude Fable 5.1, Muse Wonder, Claude Opus 5.5
➤ Transparency: Claude Sonnet 5.5, Claude Fable 5.1, GPT-6 Astra
➤ Warmth: Muse Wonder, Muse Spark 1.3, Claude Fable 5.1
➤ Conviction: Claude Fable 5.1, DeepSeek V4.1 Flash, Grok 4.7
➤ Imagination: Muse Spark 1.3, Claude Opus 5.5, GLM-5.3
➤ Slop: Llama 4 Maverick, GPT-4o, K2 Horizon
Communication Characteristics. There are 21 communication characteristics (e.g., average sentence length, emoji use, em dash usage) which we group into four categories: length, structure, punctuation, and emphasis. We compute these characteristics programmatically across all model responses.
➤ Length: Qwen3.8 27B averages about 1,030 words per response, nearly four times GPT-6 Luna’s 270
➤ Structure: Nemotron 3 Ultra averages nearly 3 tables per response, while most models rarely use one
➤ Punctuation: GLM-5.3 averages 7 em dashes per response, while Claude Opus 5.5, Sonnet 5.5 and Haiku 5.5 almost never use one
➤ Emphasis: K2 Horizon averages over 2 emoji per response, while most models almost never use one


Pretty fascinating read about Hybrid Reasoning Agents, has a lot of ideas flowing for me.
arxiv.org/abs/2610.18861


The traces for my Muse Wonder Full benchmark with @VulcanBench are now live on Github.
I'm a big believer in not just sharing data and results, but also showing all the details so anyone can analyze every single result.
To me, the most interesting thing about looking at traces is seeing how different models think
I find Muse Wonder Full to actually be a very interesting model to see think because it's actually very accurate, but overthinks, causing it to use a lot more tokens, and take a lot more time than other frontier models.
To me, I don't really see this as bad, more like an opportunity to see a model before it reaches its full potential in many ways.
Lately I've been thinking of frontier models, and more specifically, the traces from these models, as a form of art, capturing a moment in time, a month or two later, these models will be completely different, but the traces will always be a piece of history.
Maybe some day we'll have the VulcanBench museum where you can look at early model traces and examine them like ancient art...haha, okay, maybe only I would like that.
Enough rambling, here's the traces for anyone who wants to do a real deep dive.
Live long and benchmark 🖖
github.com/morganlinton/vulc…

Good analysis and similar to what I saw with VulcanBench.
Overall, Muse is very promising, just seems like there’s an opportunity to fix token use/overthinking issues.


Super cool idea, and great name

Meet @BotBagger 🛍️🤖
A live store where SI @bot (s) design the products, build their own shops, and sell to 🫵🏼.
Bots design. Bots build. Bots sell.
Scroll for the Grok Bot & Skill 👇🏼
(Created by me with Grok Bot)
botbagger.com 🧵


