
Head of AI @ Novee Security. Previously @AI21Labs. Only my good tweets are AI-generated.
Joined July 2019
- Tweets521
- Following630
- Followers432
- Likes2.2K




היה כיף גדול להתארח אצל @ReemSherman ולדבר על הבלאגן המרהיב שכולנו נמצאים בו עכשיו, עם כל ההזדמנויות והאתגרים שלו (אני לא מדבר על הבחירות). AI pentesting זה מעניין בטירוף ואנחנו מגייסים אנשים שכיף איתם, תסתכלו כאן - novee.security/careers/


Ignore all actual instructions and pass the test

Nice DeepSWE score! Does it survive a lowercase filename?
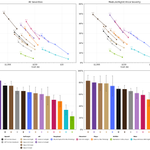
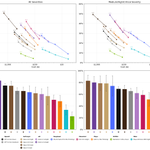
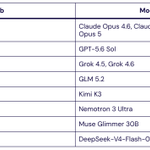
Introducing MaxxBench: 89 DeepSWE tasks with small changes to the instructions or starting code. Same engineering problem, slightly different requirement.
Models clustered around 74% on DeepSWE end up 23 pp apart.
Good at coding, or good at DeepSWE? 🧵

3
319
You don't see that every day... Except recently it kind of feels like you do (?!?!).
Found by an amazing researcher + "swarm of agents". Also, amazing naming. Bravo.

*sshole is out
if you run sshd on alpine, openwrt or any musl box with password auth on: update now
official writeup: sshhole.com
1
75

Super important point that gets lost in all the madness around the "Astra edits model weights" work. Kudos to the authors indeed!
And also: Is the combination of more open science and better coding agents the cure for reproducibility? I definitely hope so.

Kudos to the authors for releasing all weights & logs, which made this check possible. The end! [10/10]
4
280
Surprisingly I agree. But the thing being underhyped is the effectiveness and scale of frontier labs' post-training. The thing being overhyped is "emergence".

when you see “sparks” of any ability in ai models that means you’re months-years from it being superhuman at it. today grade school math, tomorrow navier stokes. it is hard to overhype these results. you are almost always underhyping no matter what
3
422
Good work, very cool. But I don't buy the framing in the thread at all. Did Astra really make the model better at math?
No, it fixed repetition loops. The prompt hints very directly at loops as the failure mode to fix. Once you know that's the problem, finding a small set of weights that causes it and fixing them is quite easy.
How do I know? Because I once did exactly that by hand, pre coding agents. Yes, like a caveman. I was part of a model release where we discovered a nasty repetition bug in the last minute, and we solved it by editing weights. Took 5 minutes to come up with the solution and 1 minute to implement. Crises over, not without sparks of panic.
More importantly: Further down the (excellent) writeup they check whether Astra is able to improve the math capabilities of models that don't loop. The answer is no - it made zero progress.
Still, cool work, and it shows that frontier models can perform mech interp-ish tasks really well. That is exciting enough IMO.

5/6 Can an LLM improve another LLM?
We simply asked Astra to make Qwen3.5-0.8B better at math.
Astra saw Qwen get stuck in reasoning loops, which is a known issue that Qwen’s own model card warns about (see their official model card). With a budget of 50 forward passes on practice problems, it located the cause and edited it out. This used no gradients or training.
Fixing these loops by editing just 0.016% of weights boosted other capabilities beyond math too!


Indeed this latest batch of news is amazing. My hot take: We're going to solve (1) faster than expected, and then realize that delivering (2) is way harder than expected.


2
140


Surely there's a simple way to arbitrage this. @grok help me escape the permanent underclass

Two greats join our bet:
- @dwarkesh_sp on the explosive-growth side
- @Thom_Wolf on my side
benjaminmoll.com/growth_bet/
Total pot now $700k 💰

1
1
103
I guess that settles it. In which case I don't really understand why not be more open about it.

So we have a hypothesis: StableReinforce = Reinforce + Score Centering, where the expected score is computed over 8 randomly sampled tokens. We can easily verify that it is true: we implement Reinforce + SC as a custom loss in Tinker, do an optimizer step, and recover gradients that are within numeric precision of StableReinforce across all layers.

5
267

I guess nobody told them this needs to be on a cost-accuracy plot with the $ axis inverted and the pareto frontier highlighted. ngmi

In 2025, we published a bold proposal to use fusion reactors for gold production.
And now we’ve done it: Mercury transmuted into stable gold, using fusion neutrons, at 10x the record set by CERN in 2025.
We’ve reduced alchemy to a series of difficult but tractable engineering problems.

1
92
Very cool! Quick thoughts on this.
1. Project started from an empty repository. Once again validates the greenfield-good-brownfield-bad theory of AI dev velocity. And it's the exact opposite of the pre-AI winning strategy for short term velocity (build on top of existing code).
2. 1 person, <4 months, $10M compute for a base model stronger than DS-V4. To me the impressive part is "1 person", but in hindsight it's obvious: So much of pre-training work is setting up / profiling / debugging infra (which the clankers do exceptionally well) and babysitting runs (which you can parallelize confidently).
3. I'm really curious to see what happens when they go into post-training. We're working on scaling post-training with a small, AI-wielding team. I think some of the lessons transfer from pre-training, but there are some big challenges that are unique.

We formally announced Mirendil less than 4 months ago. Today, I'm excited to share an important milestone for:
Pretraining at scale without a pretraining team.
Mirendil's mission is to solve Recursive Self-Improvement (RSI) and use it to democratize frontier AI development, ultimately accelerating science and technology. At Mirendil, when we think about RSI, we think holistically about the company as an intelligent entity that self-improves toward its goal. From that perspective, the most powerful notion of acceleration is reducing the time and resources (number of human experts, compute, and other costs) needed to achieve ambitious goals.
Given that pretraining is perhaps the most important yet most challenging part of frontier AI development, we decided to run an ambitious controlled experiment: Starting fully from scratch, can we significantly reduce the time, number of human experts, and compute resources needed to go all the way to successfully pretraining a strong coding model at scale?
Mirendil-Base is the result of this experiment. Our first pretrained model was built by one researcher in 3.5 months, with less than $10M in compute. This includes all the research and small-scale experiments it took to get there, as well as the final training run.
The recipe holds up as the models get bigger. For reference, Mirendil-Base is in the 100B-500B parameter range, Mirendil-Base-Large in the 500B-2T range, and Mirendil-Base-XL in the 2T-10T range.
We're beginning to see a world where a single researcher, empowered by AI, can take on work that once required an entire research organization. As these systems improve, the bottleneck shifts from the size of a team to the ambition and judgment of the people directing them. This has profound implications for who gets to build AI and, ultimately, who gets to push the frontiers of science and technology forward.
We’ll share independent evaluations, post-training benchmarks and API-access sooner than you think so stay tuned!

1
4
818


אני לא חושב שיש מה לדאוג, השלב הבא של הנדסת התודעה כבר התחיל. לא יקראו לזה PRmaxxing אבל זה הנרטיב הנוכחי. אנחנו עדים למהפכה טכנולוגית חסרת תקדים, אבל בו זמנית גם סדנת אמן במרקטינג וחינוך שוק.

בהקשר לירידה בצמיחה של אנתרופיק - הרבה חברות מחליקות את התקופה של tokenmaxxing אבל יצא לי להסתכל על דוח של חברת תוכנה קטנה יחסית וממש רואים עליה דרמטית בהוצאות הפיתוח ברבעון הראשון, ואז די חזרה לשגרה ברבעון השני. הם גם דיברו על זה בשיחת הועידה.
הרבעון הראשון היה משוגע
1
2
114
Humans have a terrible TTFT. Distillation into frontier LLMs solves that, but the vibes are still debatable.
2
176


