

Salt life | Florida Fishing | Still have no idea what twitters for...
Florida, USA
Joined July 2016
- Tweets1.1K
- Following282
- Followers79
- Likes21.7K




finally a mid-size open MoE…
Inkling 2 Mini: 26.4B, ~3.4B active, Apache 2.0
llama.cpp + vLLM on day one
5070 Ti 16GB: UD-IQ4_XS is 14.65 GiB, fits
2x B60 48GB: Q8_K_XL is 21.3 GiB, room to spare
running it on Arc this weekend. anyone got B60 numbers yet?


Run Inkling 2 Mini, the strongest 26.4B model that runs on 16GB RAM.
Thinking Machines’ Apache 2.0 MoE model uses a looped transformer arch & scores 48.2% on DeepSWE v1.1, the best for size.
Run on Unsloth, llama.cpp
GGUF: huggingface.co/unsloth/Inkli…
Guide: unsloth.ai/docs/models/inkli…

30
Daniel retweeted
Give it a try!

🚨 JUST IN 🚨
Announcing the @NousResearch Hermes adapter for @Alibaba_Qwen Qwen3.8-27B!
Much more efficient and accurate agentic development with Qwen3.8-27B + Hermes!
- SWE-Bench Pro (hard 51) pass@1: 29.4% → 43.1% | with xhigh thinking: 45.1% → 51.0%
- Terminal-Bench 2.1 pass@1: 44.7% → 58.8% | with xhigh thinking: 58.8% → 57.6%
With thinking off, it matches the base model thinking at xhigh, while using 3.5-4.4x fewer tokens
huggingface.co/harness-hub/Q…
Daniel retweeted

これめちゃくちゃ面白いな
Piハーネスに特化したQwen3.8 27BのためのLoraアダプタで、タスクあたりのツール呼び出し数が5〜6割くらい減るらしい...
主張するベンチだとthinking offでもめちゃくちゃ性能上がってるw
実現するなら個人でもできる範囲でGPU借りて好きなハーネス特化のLoraくらいなら作れそうだな!!!!
めちゃくちゃワクワクする!!!
↓モデルカードにあった学習深度によるモデルのツール呼び出し回数のグラフ
Announcing harness adapters for @Alibaba_Qwen Qwen3.8-27B on Pi harness!
We're releasing a LoRA adapter that makes Qwen3.8-27B a much better and efficient agent behind Pi harness.
SWE-Bench Pro (Hard 51 subset) pass@1: 29% -> 63%
Terminal-Bench 2.1 pass@1: 40% -> 56%
Much more efficient: 55-62% fewer tool calls per task 🤯
huggingface.co/harness-hub/Q…
The era of harness-specific adapters is now on! More harness adapters to come in the next days 🧵




Daniel retweeted

any ladies out there disgusted by the jensen huang cheating allegations?
if you own an RTX 5070 or higher, it’s time to take a stand
sell that disgusting piece of hardware to me for $50
don’t let that man’s GPU sit in your house. know your worth ladies
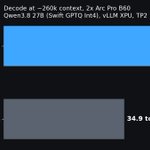
wrote my own attention kernels for Arc B60…
260k context, 2x B60
dense: 34.9 tok/s
my QSA kernels: 46.9 tok/s
Qwen3.8 27B (my Swift bake) on vLLM XPU
int8 K / int4 V cache
still experimental. short context and prefill still lose to dense
but long context finally goes the right way
github.com/Wrapzii/k8v4-xpu/…
anyone else writing kernels for Arc?

Qwen 4 is "here"…
Max is API only. no weights
the one I actually want is the 27B
2x B60 is still running Qwen3.8 27B at 138 tok/s
the moment 27B weights drop I'm running it
you care about Max at all or just the 27B?


Qwen4 is coming.
Deeper knowledge. Richer world understanding. Stronger coding and agentic capabilities.
Built for real-world tasks — from complex coding and knowledge work to front-end builds and professional software workflows.
Qwen4-Max is now in preview on Alibaba’s Token Plan. You can also get early access to the new model on QwenWork, Qoder, Qwen APP, and QwenStudio.
Put it to the test on a real problem. Show us what you build. 👀
Token Plan: qwencloud.com/pricing/token-…

2
1
162



last year's frontier, running under my desk…
Qwen 3.8 27B on 2x Intel Arc B60
138 tok/s at 2k
117 at 32k
77 at 128k
62 at 200k
my own 4-bit bake, zero API bill
what's the cheapest rig you've got running it?


Just a reminder that DeepSeek V4.1 Flash 1017, GLM 5.3 Flash, Qwen 3.8 Next Flash, and even Qwen 3.8 27B are all outperforming (in both intelligence and capabilities) every model that was considered "frontier intelligence" in Xmas 2025 (just 11 months ago)
Opensource AI is on fire
92


Daniel retweeted

> need new machine quickly
> call the manufacturer, no answer
> email sales team
> next day they ask where we’re located
> Texas
> that’s X’s territory, here is his email
> email X
> auto responder, traveling and won’t be responding to emails
> call manufacturer, say I want to talk to different sales guy, they say I have to talk to X
> call X and he answers
> says he has machine in stock, great!
> says in stock means 4 week lead time
> how can in stock mean 4 week lead time I ask
> he says that’s the standard lead time
> I say any chance to make it faster?
> he says might be able to get it down to 2 weeks to ship out a machine that’s in stock
my 27B Intel bake hit 1,171 downloads in the last month…
Swift 1.5 Qwen3.8 27B, 4-bit, built to fit 2x 24GB Arc cards on vLLM XPU
did not expect that many people running Arc for LLMs
if you're one of them, what card and what tok/s?
huggingface.co/Wrapzii/Swift…

47
same 27B, Intel vs AMD…
Swift 1.5 Qwen3.8 27B decode
2x Arc Pro B60 (mine): 138 tok/s at 2k, 117 at 32k, 77 at 128k
1x RX 7900 XT 20GB on RDNA-FAST: 67 at 4k, 61 at 41k
a single 20GB AMD card holding 96k ctx with 2 agent slots is honestly sick
mine is two cards and 48GB so yea, not a clean race
who's got this model on NVIDIA? drop your tok/s at 32k+
AMD numbers: github.com/serrynaimo/RDNA-F… (via @dextune)

1
125
everyone says DeepSeek V4.1 Flash is the best open model rn…
so does it fit my rigs?
763B MoE, 6 of 384 experts active per token
smallest real build: 121GB of weights + 111GB lookup tables that just sit on the SSD
(ISTA-DASLab GSQ-RCO IQ1_M, llama.cpp b11870+)
5070 Ti box: 16GB VRAM + 64GB RAM = 80GB
2x B60 box: 48GB VRAM + 32GB RAM = 80GB
neither holds even the 1.75 bit weights
@dextune still got 10 tok/s on a 7900 XTX + 60GB DDR5 with the 2.25 bit one…
anyone running it on 16GB yet?

72
