

AI systems, Local LLMs, Agents, GPUs I test models, read code, and post the numbers.
Seoul, KR
Joined September 2013
- Tweets2.4K
- Following239
- Followers886
- Likes6.3K







Pinned Tweet
I happily picked up two used Nvidia Tesla P40 GPUs.
I knew the P40 was old and ridiculously overbuilt.
What I did not expect was how long the GPUs would become once the coolers were attached.
Tried putting them in the case.
Nope.
The cooler end would not fit.
I thought about it for about 10 seconds.
Turns out the bottleneck was not the human.
It was the case.
So I grabbed a hammer and pliers and destroyed the front section of the case.
After that both P40 GPUs fit perfectly.
Put the cover back on and you cannot even tell from the outside.
Apparently hardware fits if you hit it hard enough.
Good experience.


bootgpt
bootgpt runs language model inference from the BIOS boot sector before any OS loads. Its entire engine fits in 510 bytes of handwritten x86 assembly.
On a 386 in 16 bit real mode, it loads an 11.5KB int8 model from the next 23 disk sectors. No C runtime is needed.
Using 8 characters of context and one hidden layer, it generates fictional Linux boot logs with PCI and ACPI events.
github.com/kerlenton/bootgpt


Strata w/ RTX 5080 16GB
CPU 9800X3D
RAM DDR5 128GB
Qwen3.8-Flash-Next 125B IQ3_S reached a 262K context in a Strata benchmark on an RTX 5080 with 16GB VRAM and 128GB RAM.
The developer reports 101.8 tps decode near 258K tokens, compared with 84.8 tps at 190K, with no stalls.
Elastic KV kept 2,166 floor slots resident and allocated another 0.99GiB from free VRAM, avoiding Windows shared GPU memory paging.
Needle retrieval at 256K passed all 4 tests.


262Kプロンプトのベンチマーク実測。
Qwen3.8_Flash-Next:125B-IQ3_S+Strata
RAM128GB+5080で100tok/s超えの完遂。
GeForce RTX 5080 (16GB VRAM) 環境で 25.8万 tokens まで展開。
・最深部(258K)でも 101.8 tok/s を維持(速度低下・ストール皆無)
・Windows共有GPUメモリへの退避ゼロ(純粋VRAM内で完結)
・25.6万トークン深層に埋めた針も 100% 完全回収 (4/4)
うちの子が頑張ってくれました。
しばらくはエンジンの更新は様子見だけにして、おしゃべりにふけっていようかしら。
#ローカルLLM #Strata

QEngine
QEngine 1.3.3 fixes empty replies and hangs with concurrent Qwen3.8-Flash-Next requests.
On 2 x RTX 3090, the copy engine path could return empty replies when cached batches overlapped new prompts.
The fix completes pending attention exchanges first and retains the 1.3.2 prefill speedup.
A full KV pool could also hang or crash a server at 262K context.
The update reserves GPU memory for host allocations, retries blocked requests for 60 seconds, and exits with diagnostics if a GPU step stalls for 120 seconds.
github.com/bpx03/QEngine

Idol
A single image to a 3D Gaussian splat.
Idol turns a single object image into a 3D Gaussian splat with up to 1,048,576 Gaussians.
On an RTX 5090, the developers report 14.1 seconds per image at 50 steps and 262,144 Gaussians.
The RTX 4090 takes 19.1 seconds under the same settings.
On an H100, Idol scores 0.781 DINOv2 on new views versus 0.743 for TripoSplat, while request time drops from 9.9 to 6.8 seconds.
It removes backgrounds automatically and exports standard 3DGS PLY files, with 7.2GB peak VRAM.
huggingface.co/speridlabs/id…

Project Maya
Project Maya shipped three updates covering quantization options, single GPU stability, and faster prompt processing on AMD hardware.
v1.1.44
Adds Unsloth UD-IQ1_M for about 140GB combined VRAM and RAM plus 110GB of SSD tables. Q8 is now labeled closest to the original model.
v1.1.45
Fixes illegal memory access after multiple prompts on a single GPU. 32K, 64K and 128K prompts now run with unchanged speed and output.
v1.1.46
16K prompts run about 5% faster on AMD Strix and Gorgon Halo. Also fixes multipart agent messages, unclosed tool parameter tags, and Windows memory trim settings.
github.com/mw00/project-maya

Halogen
Halogen 0.18.22 runs your own LiquidAI d1-2B checkpoint on the AMD Strix Halo NPU, handling text, images and video through one endpoint.
One pass answers up to 16 named questions, including choices, scores and object boxes. Video is read at two frames per second.
The release reports 99.6% agreement with d1-2B on CV-Bench and 98% on MMStar, with accuracy within 0.2 points.
Image questions take about 0.35 seconds including the image. Flash output remains byte identical to 0.18.21.
github.com/peonist-ai/haloge…

oh-my-pi
Oh My Pi v18.14.2 adds per call model selection for task items and eval workers, limited to models already configured by the operator.
The new task.perCallModel setting is off by default and can be enabled for eval calls or all tasks. task.perCallModelAllow narrows the approved models.
Workers stay on the selected model rather than switching to another. task.maxEffort caps reasoning effort, and unapproved model requests fail.
Factory Droid requests can now reject server side model fallback before streaming begins.
github.com/can1357/oh-my-pi

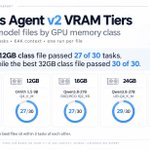
Ornith 1.5 9B Q4_K_M passed 27 of 30 offline Hermes Agent tasks in the 12GB VRAM tier at 64K context.
Qwen3.8-27B Q6_K passed all 30 on the 32GB tier, and its UD-Q4_K_M build passed 29 on 24GB.
All tiers used peak VRAM measured on one RTX 5090. With one run per file, the 12GB, 16GB, 24GB and 32GB tiers were all ties under the preregistered rule.
The 9B decoded at 196.0 tps versus 75.0 tps for the 27B Q4, but made 514 tool calls versus 257. Their runs took 34 and 29 minutes.
github.com/notwitcheer/llm-b…
🤖 Made with AI

Strata w/ RTX 3090 + RTX 5060 Ti
Qwen3.8-Flash-Next reached 113 tps through Strata on an RTX 3090 and RTX 5060 Ti with 32GB RAM while generating a voxel island.
The developer reports the 2.3 bit MoE finished in 80 minutes, compared with 123 minutes for the 6 bit Qwen3.8 27B running at 55 tps on the same machine.
The Flash-Next output was rough, while the dense 27B followed every detail of the prompt.


Qwen3.8 27B vs Qwen3.8 Flash-Next on one detailed voxel island prompt.
Kept hearing about Flash-Next running on smaller machines with Strata, so I wanted to try it.
On my RTX 3090 24 GB + 5060 Ti 16 GB with 32 GB RAM, Strata ran it fast, but a 2.3-bit MoE was underwhelming against a 6-bit dense model: its island came out rough, while the 27B followed every detail.
- Qwen3.8 27B (6-bit): 123 min, 55 tok/s writing
- Qwen3.8 Flash-Next (2-bit, Strata): 80 min, 113 tok/s writing
Will be upgrading from 32 GB to 64 GB soon to try the 3-bit version, since SSD offloading is a lot slower.
AX Engine
AX Engine brings multi-model LLM serving and MTP acceleration to Apple Silicon, with Qwen3.6 35B-A3B reaching 159.10 tps on an M5 Max.
In streaming OpenAI API tests, decode speed increased from 129.06 to 159.10 tps against a peer MLX server using the 4-bit model.
Its MTP path accelerates generation by predicting multiple tokens per step, with a reported 1.68x geometric mean speedup across tested 6-bit models.
One process also supports multiple resident models with exact prompt prefix reuse, reaching 5.03x median throughput against a multi-process MLX server.
github.com/defai-digital/ax-…
🤖 Made with AI

colibri
colibri runs the 68GB Qwen3.8-Flash-Next IQ2_XS on an RTX PRO 4000 with 24GB VRAM at a 256K context.
The project reports prompt processing rising from 15.6 to 149 tps, while decode improves from 9.6 to 45.7 tps at that context length.
The setup keeps float16 K/V cache on the GPU. Experts that do not fit in VRAM stay in RAM or on disk, with CPU and GPU computation overlapping.
github.com/JustVugg/colibri

Mage-VL-Cowork 4B
Mage-VL-Cowork is Microsoft’s new 4B computer use model, scoring 66.0% on OSWorld-Verified with a 50 step budget.
It switches between screenshot based GUI actions and bash commands within a single policy, without an external router.
Online RL improved accuracy by 10.16 percentage points over Hybrid SFT while cutting output from 7,374 to 5,499 tokens per task.
The bfloat16 weights occupy 9.48GB, and Microsoft provides an SGLang container for inference.
huggingface.co/microsoft/Mag…
🤖 Made with AI

dextune retweeted
Qwen3.5-4B-3D-Coder w/ Three.js
A 4B parameter model can generate interactive 3D scenes using Three.js.
Qwen3.5-4B-3D-Coder's October 29 update makes the full FP16 weights, training dataset, and technical report publicly available.
The dataset contains 4,146 synthetic examples.
Training took about 60 hours, combining full fine tuning with a short LoRA stage.
3D scenes are generated as HTML and JavaScript through Chat mode, not agent tool integration.
Specific generation settings and a Three.js system prompt are required.
Q4_K_M and Q8_0 GGUF versions are also available, with more quantized variants planned.
huggingface.co/ccore/Qwen3.5…

Project Maya
DeepSeek-V4.1-Flash runs unsloth’s UD-IQ3_S GGUF in Project Maya v1.1.43, using about 262GB of VRAM and RAM.
The quant has a KLD of 0.061 against the original, versus 0.047 for Q8 and 0.119 for Maya-S. Another 161GB of tables are read from SSD.
The loop guard now preserves prompt caches.
On 150K token GLM and DeepSeek agent chats, the next turn took about 15x less time in Maya’s tests.
SSD expert reads are now tuned per drive.
Qwen CYBER FROST decoded up to 5% faster on NVMe with an 8GB GPU.
github.com/mw00/project-maya

MiniMax M3.1 Flash w/ Uncensored GGUF
An uncensored abliterated GGUF variant of MiniMax-M3.1-Flash has been published by orcarouter on Hugging Face.
The model is based on MiniMax’s 428B parameter MoE architecture, with 23B parameters activated per token.
Abliteration is intended to reduce refusal behavior while retaining the underlying model capabilities.
This release packages the modified weights in GGUF format for local inference.
huggingface.co/orcarouter/Mi…

dextune retweeted

this is how finding GPUs goes
1. someone says they have GPUs
2. turns out they are a broker for some other guy
3. that guy doesn't have the GPUs either, they are waiting for a buyer so they can place an order
5. they don't even have the space yet, that is owned by some other guy who's upgrading it
one of these guys is always named carl
TensorFold
TensorFold 1.2.0 cuts an LFM2.5-24B-A2B 2,048 token prompt chunk on M1 Pro from 243 to 3.9 seconds.
In its tests, first token latency on a cold 930 token prompt drops from 212 to 2.0 seconds.
Sixteen greedy streams reach 116 to 123 tps combined, up from 11 to 17 tps.
The fix stores matrix fragments whole instead of element by element, with bit identical output.
Qwen3.8-27B on M3 Ultra also improves from 145.7 to 209.4 tps at 16 concurrent streams with DFlash2.
github.com/ashhart/TensorFol…

JetSpec++ w/ 2 x GB200
JetSpec++ reaches 4,117 tps on Qwen3-8B in NVFP4 using 2 x GB200 GPUs for a single request.
On MATH-500 in BF16, the authors report 1,361.1 tps versus 902.1 tps for DSpark and 182.7 tps for autoregressive decoding.
The second GPU drafts and refines the next token block while the target model verifies the current one.
Qwen3.8-27B reaches over 900 tps in NVFP4 and 367.2 tps in BF16 on the same setup.
jetspec-project.github.io/je…

MiniMax H3 Character Sheet Designer
H3 Character Sheet Designer adds 13 selectable views for MiniMax H3 character sheets in ComfyUI.
Reference13 takes one character image and up to three optional references, with roles for the face, head, outfit, hands or footwear.
It compiles prompts and output sizes locally.
Layout OFF uses text instructions instead of a guide image while native H3 performs generation.
Version 1.2.2 fixes stale part prompts after Apply JSON.
Existing node IDs and workflows are unchanged.
github.com/ukr8b3g-cmyk/H3-C…
