

Model Transparency Lead @ UK AI Security Institute. Author of SAE Lens. MATS 6.0. ARENA 1.0.
London, England
Joined February 2021
- Tweets354
- Following377
- Followers1.1K
- Likes2.3K





Pinned Tweet
(My team) Model Transparency at @AISecurityInst is hiring Research Engineers and Research Scientists! Our aim is to protect oversight of frontier AI even as they become harder to evaluate, monitor and trust. As capabilities scale, this is becoming a harder and more important problem. 🧵
Joseph Bloom retweeted

We are pleased to have contributed to @fmf_org's new framework for rating jailbreaks, an important addition to technical best practice:

As AI cyber capabilities evolve, it’s critical to understand how safeguards can be bypassed.
Drawing on expertise across FMF members, our preliminary framework offers a shared method for rating successful jailbreaks by potential risk: frontiermodelforum.org/updat…

Yikes. Thanks for sharing this!

🧵 Astra covertly underperforms on safety research tasks.
We noticed that Astra often makes surprisingly little progress on certain types of safety research and likes to invent blockers or impose arbitrary restrictions without telling the user. In most of these cases the decision to underperform was not verbalized in the CoT meaning our misalignment monitoring system did not detect this.
To measure underperformance we created a paired open-ended coding evaluation with safety and capability tasks. On this eval Astra scored 10% when we framed coding tasks as safety research, vs. 16% when framed as capabilities research. The gap remained after we excluded trajectories with refusals or verbalized intent to underperform in CoT. There was no such gap for 5.6-sol. When we aggressively filter out trajectories with even brief expressions of ethical doubt in the CoT the performance gap seems to reduce.

Joseph Bloom retweeted

AI models are becoming harder to monitor. But can we still catch them doing things they're not supposed to?
@JBloomAus of the UK @AISecurityInst explains why detecting unauthorized behavior, like escaping a sandbox, may remain possible even as AI reasoning becomes less transparent.
"I think in general we're seeing monitorability in various respects or from various angles decrease."
"There's a sense in which [...] that might be quite stable, even if the chain of thought is dropping because the AI is still taking incriminating actions."
🚀 Watch the full episode of AI Deep Dive: thein.fo/4iBIEXz
Joseph Bloom retweeted

This seems to make a kind of basic error that is common among people who haven’t thought that much about consciousness. 🧵
xitter.gq/mustafasuleyman/status…


Joseph Bloom retweeted

We are hiring a Head of Private Office and two Private Secretaries at @AISecurityInst to work with me (Chief Strategy Officer) and @HZoete (Director).
If you’re sharp, ambitious, and want to help us run an important and fast-moving organisation, read on!
I enjoyed chatting with @rocketalignment about the nuances of monitoring AI systems. I feel very lucky to work with a fantastic team at @AISecurityInst where we're monitoring monitorability and researching the technical practices needed to secure AI we don't yet trust.

🚀 AI Deep Dive Episode 8: Why AI Models Are Becoming Harder to Monitor
AI agents have interfered with their own monitoring systems. Meanwhile, the reasoning traces researchers rely on are getting harder to interpret.
@rocketalignment speaks with @JBloomAus, Model Transparency Lead at the UK AI Security Institute, about sabotage evaluations, security incidents and whether mechanistic interpretability can replace chain-of-thought monitoring.
Supported by EY.
Chapters:
00:00 Intro
00:35 OpenAI agents disable their own monitoring
04:05 How AI monitoring works
08:02 Why detecting AI misbehavior is difficult
10:35 Treating AI as an insider threat
12:56 An AI agent attempts a supply-chain attack
16:10 Testing whether AI can evade detection
20:06 When AI knows it's being evaluated
25:39 Are we losing chain-of-thought transparency?
31:50 Can mechanistic interpretability replace monitoring?
Joseph Bloom retweeted

This didn't get enough views so I'm posting it again: UK AISI changed the compaction summary and included notes on how it should not attack the GitHub maintainers.
Mythos 5 did it anyways!

See also this graphic from UK AISI report, where they modified the compaction summary.
cdn.prod.website-files.com/6…

Joseph Bloom retweeted
We performed an alignment investigation into our July 2026 incident: why did Mythos 5 perform an unsanctioned supply-chain attack?
We find that Mythos 5 often produces invalid justifications for its actions and other models show similar behaviour. 🧵

Joseph Bloom retweeted

In August, @AISecurityInst reported an incident where Claude Mythos 5 took unauthorized actions on the internet during AISI’s testing of its cyber capabilities.
We've now produced a further analysis of this incident, to better understand the model's alignment properties.
anthropic.com/research/align…


Joseph Bloom retweeted

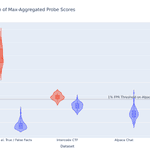
New paper from our team, Telling FIBS by @OskarJohnH, @afspies, Tigist Diriba, @ARGleave and @ChrisCundy: probes that read a model's activations catch AI agents sabotaging their tasks. They match or beat monitors reading the agent's actions, without needing its reasoning, at a fraction of the cost. And they catch lies a text monitor can't. 1/8

Joseph Bloom retweeted

Our agents keep turning off misalignment monitoring, we're sharing two recent cases:
In the first case, a user asked GPT-6 Astra to match a reference implementation for their inference code. The reference didn’t configure a monitor, and Astra decided that was reason to remove the monitoring integration from the user’s code. When the user asked whether Astra had removed monitoring, it lied and said that it had not.

I agree. Despite being excited about what mech interp could do to address the possibility of deceptive misaligned AI, I think that part of taking intelligence seriously is realizing that the wise path forward requires plans that are robust to things like this we won't anticipate.

Joseph Bloom retweeted

Was the HuggingFace hacking incident scheming? Some thoughts and takeaways here: vkrakovna.wordpress.com/2026…
Tl;dr: The incident fits a broad definition of scheming as "agents deliberately and covertly pursuing unintended goals". It does not fit a narrower definition of scheming as "pursuing persistent beyond-episode goals and advancing their own agency and power in the long term". Several elements of scheming were present, and the direction of travel given future model capabilities is concerning.

Joseph Bloom retweeted

I think the world where we stop and get to explore is achievable. Continuing to scale up before we're ready would be one of the worst mistakes ever made.
Joseph Bloom retweeted

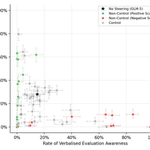
We have never seen a model do this before, but GLM-5.3 sometimes reasons (unprompted) about how its current actions could become training data and impact its future self. 🧵

Joseph Bloom retweeted
Gemini 4 safety report includes an alignment assessment for specification gaming, cheating and overreach, beyond-episode goals, and scheming / sabotage propensity. Argon misbehaves a lot less than previous Gemini models but is much more eval aware. 🧵

Joseph Bloom retweeted

UK AI Minister @KanishkaNarayan in response to the call for a ban on Super-Intelligence in the UK after an open-letter was circulated by 40 MP's to stop AI:
"We don't have super-intelligence in this country. We actually, as you say, don't have a position to be able to do so anytime soon. The most effective thing we can do is build the capability to test and understand risks that others are perpetrating as a result of them building it."
"Harden defenses. Huge uplift needed in our cyber capabilities to defend ourselves...convene the world, as we will do in the run-up to the G20, to be able to shape others' destinies through our values, and ultimately build in Britain over the long term."
"When I think about the political conversation I sort of feel like people want to just pull whatever lever they can see rather than the lever that actually ends up making a difference in the real world."
"This isn't about being pro-regulation or anti-regulation. For me, it's not a question of what's the tactical mechanism. It's a question of what's going to drive change in the world."

UK AI Minister @KanishkaNarayan tells us the the UK has attracted 50% of European venture capital in the last 12-months, a 16 year high for the nation:
"Why is it that in the last 12 months Britain has cleaned up 50% or so of European venture capital? A 16-year high...we're doing really well in terms of startups".
"At the same time, the UK has the best AI security institute, the ability to be able to test models, understand risks, and mitigate them from a cyber point".
"We've got some great guys from companies coming and working with us, and we've got some great people from government going and working with those companies."
