

The open source training platform for continuously improving agents and models
London & San Francisco
Joined January 2026
- Tweets351
- Following6
- Followers722
- Likes704




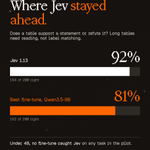
Enterprises still go for 30-200B models because big feels safe. Small and trained often does the job better.
AI got a user interface. Using it is a prompt away.
Next comes a training interface, where improving your agent is as easy as using it.

@JensenHuang put our whole roadmap on one slide at #nvidiagtc berlin: "take control of your intelligence, build your own ai" (the @pollenrobotics microducks waddling around his feet still stole the show!!)
nvidia calls them ai factories, with gpus at one end and enterprise value at the other. almost every conversation i had was about some stretch of that chain
the best debates were about rl. everyone is racing to own the rl stack, yet every compute provider told me the same thing: enterprises still pick 30-200b general models because big feels safe. a focused 1-3b specialist would often do the job better. that is an education gap, not a tech one.
huge thanks to the @nvidia startup team. jessica held the stage with so much warmth, naomi ran everything so smoothly you forgot how hard it was, and howard went from the hardwood to nvidia without losing his court vision. bonus: howard and naomi share my altitude, so for once i got to talk to people eye to eye
the future we are building at @OvermindLab: every agent in production supervised by one open-source platform that trains on your own data, runs on infra you own, and ships a better version of itself every single day 🚀


Full write-up, including biomedical and aviation results: overmindlab.ai/research/when…
Try it on your own traces: overmindlab.ai

"Traces are only useful if they feed a better agent."
In practice, on 4,000+ contract questions:
Qwen3.5-9B trained on the task:
• 91.6 F1
• $1.03 per 1k questions
GPT-5.6 Luna:
• 82.0 F1
• $20.94 per 1k questions
Bigger isn't better. Trained is.

Agent traces are useful only if they feed a better agent.
Overmind is an open-source training platform for builders who want to improve specialized AI agents using production traces or their own datasets.
It helps you turn those traces into versioned evaluation and training data, then test improvements against the metrics you define.
Key features:
• Agent context graph – scans a repo for an agent’s capabilities, prompts, tools, and tasks
• Trace-based datasets – turns production traces or uploaded files into versioned eval and training datasets
• Per-capability evals – measures what “good” means on live traces and in batch
• Optimisation experiments – tests prompt, tool, and control-flow changes in your repo; the winner is a git diff
• Model workflow – fine-tunes models on your data and serves trained or frontier models through one API
The platform is open-source (AGPL-3.0); the SDK and CLI are MIT licensed.
Link in the reply 👇

Overmind's eye sees all at @NVIDIAGTC
The vision in Europe is clear. The future belongs to companies that build their own intelligence.
Overmind brings vision and future into alignment.
Stay tuned.
in berlin this week for #nvidiagtc, representing @OvermindLab. the last few years were about building the biggest engine, and the next few will be won by the pit crew. come say hi if you are building agents 🙌

Overmind retweeted

I used to wonder why there has been rising interest in "open weight models" across the realms... 🌎
Then I realised the @OvermindLab eye sees all.


holy shit who is building this?
great segment on @theallinpod @DavidSacks @chamath @Jason
@OvermindLab is by far the easiest way to customise small models on your own proprietary data. direct from your coding agent, no in-house research lab required!
How to connect Langfuse, LangSmith, Braintrust or Galileo: docs.overmindlab.ai/core/obs…

If your traces live in Langfuse, leave them there.
Overmind imports them and trains a model on them.
Works from Claude Code, Cursor, Codex or OpenCode.
Get started: pip install overmind

Top 14 open-source tools for LLM monitoring in 2026
▪️ Langfuse
▪️ Opik
▪️ Overmind
▪️ MLflow
▪️ LangWatch
▪️ AgentOps
▪️ Helicone
▪️ OpenLIT
▪️ OpenLLMetry
▪️ Evidently
▪️ Weave
▪️ OpenTelemetry Collector
▪️ Grafana OSS stack
▪️ Laminar
Bookmark the list to keep it handy!
Here is also a practical guide explaining all these observability tools - what each one does, and where it best fits → turingpost.com/p/llm-observa…

Select the runs worth learning from and each becomes a training row, so the decisions your agent already makes become the training set.
Turn your company into its own AI lab.
github.com/overmind-core/ove…


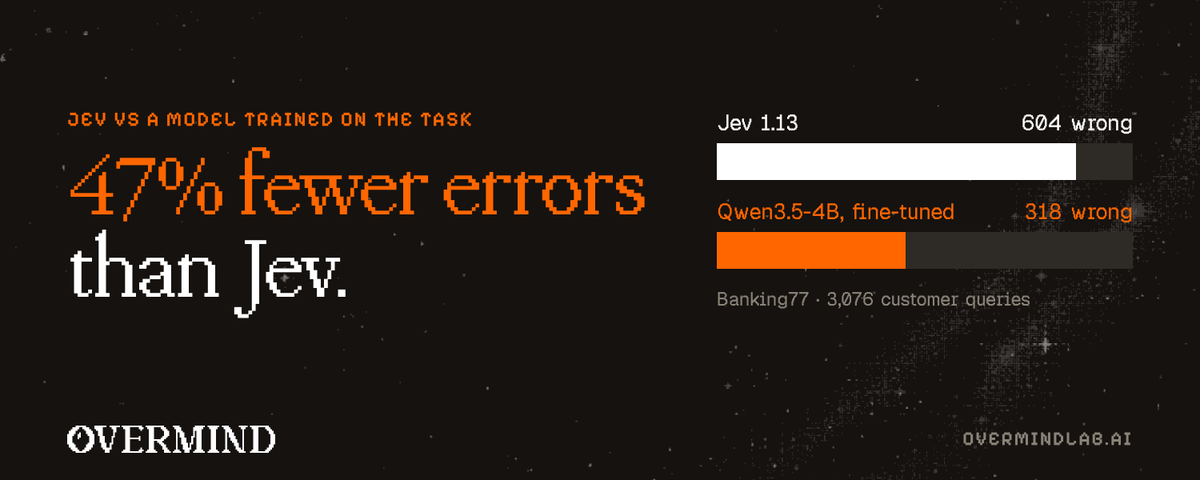
Specialists win on legal. Qwen3.5-9B vs GPT-5.6 Luna:
• 7X better at quoting a contract clause word for word
• 4X more accurate at reading a research paper
• 30X fewer phantom clauses in legal contracts
Next step: train one on your own contracts and own the weights.
Overmind retweeted
Coinbase built this for their employees.
Overmind ships it for everyone.
Run /overmind finetune in:
• Claude Code
• Cursor
• Codex
Open source, and the model is yours.

We were able to fine tune an open weight model (Qwen3.5-9B) on proprietary internal data at @coinbase, and it out performed frontier models, at much lower cost and speed, for a specialized task (fraud prevention in this case).
I think we'll see more of this pattern inside companies. The frontier models are amazing generalists. But increasingly you'll see specialist models out perform on more narrow tasks, either working on teams, or by themselves.
We're making it easy to fine tune models internally for our employees. We even have a skill for it in our internal harness that makes it easy to spin these up and start training them:
"/fine-tune-and-serve-llm I want to fine-tune Qwen for payments risk review. help me get started"
I imagine we'll have some backend services that could be replaced entirely by this new architecture.


Agreed, the eval set is the hard part, so /overmind finetune won’t launch without a separate one.
With 500 messy rows our Data Workshop flags answers the inputs don’t support and can generate more training examples. The before/after eval tells you if 500 was enough.
