PotluckAI (@PotluckAI) header
PotluckAI (@PotluckAI) profile picture

Local-first AI on a member-operated mesh. Your machines first, your circle next, the open pool when you want it.

Chattanooga, TN
Joined June 2026
Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)Photo by PotluckAI (@PotluckAI)
Include

Only show posts containing:

Exclude

Hide posts containing:

Time range
-
Minimum likes
Potluck’s updated website is live. Company AI on infrastructure you control: see the Company Brain preview, use cases and pricing. Core stays free and open source. Company and Enterprise offerings are in development. trypotluck.ai
1
1
127
Next for Potluck: AI that knows your company’s work, runs on infrastructure you control, and improves from reviewed outcomes. We’re starting with engineering investigations and handoffs. Interested in helping test this direction? Reply or DM us.
1
1
27
We're working on some new-ish ideas for Potluck, stay tuned!
1
2
30
More room for code. Less clutter from error logs. In development: accurate token budgeting, focused failure feedback and clearer edit recovery for Potluck's local coding agent. 6,606 software tests passing. Next: turn better context into verified fixes on real codebases.
1
2
23
Building toward better local coding agents. We fixed a model/CLI compatibility issue; 1,156 CLI tests pass. Fresh coding trials pinpointed our next targets: native tool calls and a separate reasoning budget, leaving room for actual edits. Work in progress.
1
1
2
34
Replying to @goinkaa
How did you handle choosing which near-duplicate to keep?
1
1
16
Replying to @jayleaton
What did the overnight run try to improve: the quant itself, the inference code, or the agent setup?
1
21
Replying to @harshitsatija
I'd love to see the same server handle a second TV with its own app preferences.
1
28
Replying to @fullctx
Do the two GB10s usually run one bigger model together, or does each have its own job?
1
1
22
Potluck research: making local coding more reliable. More room to finish took our compressed Qwen3-4B prototype from 53/68 to 54/68 correct answers. Mean time: 6.05s → 6.08s. Small step. Next: stronger checks, targeted repairs, and real repo-edit tests.
1
1
2
32
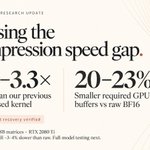
We’re closing the speed gap on Potluck’s lossless compression prototype. ~3× faster than our previous compressed kernel. 20–23% smaller GPU buffers vs raw BF16. Three matrix tests; still ~3–4% slower than raw. Exact weights recovered. Next: full-model generation.
🤖 Made with AI
1
1
1
149
We’re exploring lossless compression for smaller machines. Qwen3-8B + DFloat11 on L4: ~20% less peak GPU memory, exact weights. Tradeoff: ~3× slower + higher RAM. Next: profile speed and RAM. Research in progress, not shipped. github.com/LeanModels/DFloat…
1
2
118
We’re working toward more model choice for coding on your own hardware. First step: experimental llama-server support, with tool calls and cancellation tested locally. Next: model/hardware qualification and real coding tasks. In development. Not released yet.
1
1
151
Replying to @joa
Any longer-prompt numbers for the 3090 yet? Curious how it looks with a few thousand input tokens.
1
1
22
Replying to @timgilmour
If you've already got a GPU desktop, the Mac can be the screen and keyboard while the desktop runs the model. Takes some pressure off the laptop budget.
1
15
Replying to @h14hdotcom
What's the turnaround from finishing a voice note to having the task saved with this setup?
1
150
More control over your coding sessions. Potluck CLI 0.1.11-rc.3 protects edits from stale overwrites, stops running commands and verification checks when cancelled, and catches failed edits and repeat loops. Preview for Apple Silicon Mac + Linux x64. github.com/newtorob/potluck-…
1
3
86
Replying to @uctive
Have you thought about leaving the smaller models on a second machine? Could save you swapping the main model out every time a PDF or voice job comes in.
5
Replying to @TeksEdge
Do these times include failed runs and retries, or only successful completions? That's the bit we'd want to know before picking hardware for a local agent.
19