CEO & Founder | PhD | Startup Advisor | @Columbia | Author Generative Software Engineering https://xitter.cf/t.co/9oqvHuTX5f | ๐Ÿ”” Follow for AI & Vibe Coding Tips ๐Ÿ‘‡

PNW
Joined July 2023
Qwen3.5-4B running CPU-ONLY at up to ~11+ tps on a Ryzen 5 laptop. No GPU. Running models in RAM and CPU is something the Qwen4 team is already thinking about. ๐Ÿ’ก I built this standalone .exe because businesses are already deploying local models to save money and ensure privacy. (thumb drive friendly - just drag drop and doubleclick) My llama.cpp recipe ๐Ÿ‘‰ ๐Ÿง  Qwen3.5-4B Q4_K_M GGUF โš™๏ธ Ryzen 5 7540U โ€” 6C/12T ๐Ÿงต --threads 9 ๐Ÿงต --threads-batch 12 โšก --prio 2 ๐Ÿ”„ --poll 50 ๐Ÿ“ฆ --batch-size 2048 ๐Ÿ“ฆ --ubatch-size 512 ๐Ÿš€ --flash-attn on ๐Ÿง  KV cache: q4_0 / q4_0 ๐Ÿ”ง --repack ๐Ÿ’พ --mmap ๐Ÿ‘ค --parallel 1 ๐Ÿšซ --device none ๐Ÿšซ --gpu-layers 0 ๐Ÿšซ KV/op GPU offload ๐Ÿšซ MTP OFF Interesting result ๐Ÿ‘‰ MTP=3 was slower (~10 tps in benchmarks). Plain decode + 9 threads + Q4 KV hit ~11.4 tok/s. That's about 10% faster just from tuning llama.cpp โ€” on a basic laptop CPU.
17
2
2
64
34,262
Okay so imagine you're chatting with a local LLM that has allocated most of your GPU's VRAM. Then you launch a game. Instead of killing the model, LlamaForge gives the VRAM back. That's the idea behind a new experimental feature in LlamaForge called Elastic VRAM. When another application starts grabbing GPU memory ๐ŸŽฎ Game needs more VRAM โฌ‡๏ธ LlamaForge moves model layers back to CPU ๐Ÿง  MoE experts get moved first ๐Ÿ’ฌ Your existing conversation survives โฌ†๏ธ When VRAM becomes available again, layers move back to the GPU The model gets slower while it's shrunk to CPU. But it doesn't have to disappear completely just because you launched something else. Underneath, LlamaForge is running upstream llama.cpp and uses llama.cpp's slot save/restore to preserve the chat while it rearranges where the model lives. There's also a simpler Game Mode Launch game โ†’ unload model Quit game โ†’ reload model Elastic VRAM is the more interesting version because the model stays available while relinquishing GPU memory. Keep in mind that it is ... โš ๏ธ Experimental ๐ŸŸข NVIDIA only today โš™๏ธ Off by default ๐Ÿงช Not widely tested yet ๐Ÿ”“ LlamaForge โ†’ MIT / local Link in ALT
4
4
19
1,444
Are you getting ready for Kimi K3.1? It may already be testing in Arena under the anonymous name Kibitz. And there are now multiple clues pointing back to Moonshot. ๐Ÿงฌ Community tokenizer/fingerprint tests reportedly behave like Kimi ๐Ÿ—ฃ๏ธ In some Arena tests, Kibitz identifies itself as Kimi/Moonshot ๐Ÿ”€ Kimi Code's configuration now contains a model-switch target named k3.1 And the anonymous naming pattern is eye catching K2.5 โ†’ Kiwido K2.6 โ†’ Kiwire K3 โ†’ Kivine K3.1? โ†’ Kibitz K3 itself reportedly appeared anonymously in Arena roughly 30 hours before release. None of this confirms Kibitz = Kimi K3.1. Moonshot has not announced anything officially yet. But K3.1 itself looks increasingly real. Kimi Code now literally contains a migration rule pointing existing K3 sessions toward k3.1. If Moonshot follows K3 with open weights again, K3.1 could become the next ridiculous multi-GPU / multi-node Local AI project. Links in ALT
2
4
842
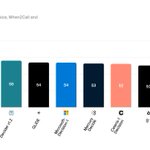
A new decision model tied for #1 on Artificial Analysis' Decision Index and its 8 points ahead of Jev 1.14. SubQ Snap 1.1 is built to make the decisions inside an AI agent. Artificial Analysis Stats ๐Ÿฅ‡ SubQ Snap 1.1 โ†’ 65 ๐Ÿฅ‡ d1-ultra โ†’ 65 ๐Ÿฅ‡ Elephant 9B โ†’ 65 Jev 1.14 โ†’ 57 And Snap has one unusual advantage, its context ๐Ÿ“š 384K context Subquadratic says its Sparse Attention architecture reduces attention compute from quadratic to linear scaling with context. Snap reads the context and returns probabilities over a fixed set of allowed decisions in a single forward pass. Subquadratic reports these benchmarks ๐Ÿงฐ When2Call โ†’ 96.2 ๐Ÿ“‰ 81% fewer confident errors on its unanswerable-query test ๐Ÿ“š 384K context ๐Ÿ’ฐ $0.04 / 1M input tokens ๐Ÿ†“ no output-token charge This isn't a local model today as Snap 1.1 is currently offered through Subquadratic's API. Layer this between the prompt and the models Link in ALT
4
1
1
24
3,297
Nvidia released Kumo Relational, a small purpose-built AI model to predict what happens next from your relational database.๐Ÿ‘€ ๐Ÿ‘‰Customer churn. | Fraud. | Future demand. | Conversion. | Risk. This is not a replacement for SQL. SQL tells you what already happened. Kumo is designed to predict what happens next from the relationships and history already inside your database. And it can do this without training a separate model for every task or manually engineering features. Instead of flattening a relational database into one giant table, it works across the relationships between your existing tables. Give it historical examples in-context, up to 10,000, and ask it to perform classification or regression. Nvidia tested it across ๐Ÿ“Š 41 tasks ๐Ÿ—„๏ธ 15 databases They report it beating supervised relational deep-learning systems and expert-engineered gradient-boosted-tree pipelines. On SAP SALT, Nvidia says it beat large AutoGluon ensembles by 8% MRR. You can download the weights and run it locally on CUDA. The checkpoints are tiny ๐Ÿง  Classification โ†’ ~120MB ๐Ÿ“ˆ Regression โ†’ ~124MB Your model doesn't just query your private database anymore. It can try to predict what happens next from it. ๐Ÿ”“ NVIDIA-authored code โ†’ Apache 2.0 โš–๏ธ Weights โ†’ OpenMDW 1.1 Link in ALT
4
4
29
1,395
2 x ~$400 Snapdragon mini PCs. No GPU used and 64GB of RAM combined. And they're running a 95GB Qwen3.8-Flash-Next at 20.3 tps. ๐Ÿ‘€ The model is 31GB larger than their combined RAM. I have to build this. The setup ๐Ÿ–ฅ๏ธ 2ร— Lenovo IdeaCentre Mini โš™๏ธ Snapdragon X X1-26-100 ๐Ÿ’พ 32GB LPDDR5 each ๐Ÿ’ฝ 512GB NVMe each ๐Ÿ”Œ connected with one USB4 cable ๐Ÿ’ฐ ~$800 total Here's the model: ๐Ÿง  Qwen3.8-Flash-Next ๐Ÿ“ฆ IQ4_NL โ†’ 95GB Reported with the author's ToRc inference engine ๐Ÿ“ฅ Read โ†’ 46.2 tps โœ๏ธ Generation โ†’ 20.3 tps ๐Ÿ’ป Coding generation โ†’ 19.2 tps And the Adreno GPUs aren't being used. ToRc uses the Snapdragon CPUs + Hexagon NPUs for some of the dense math, while the model's experts are streamed from NVMe as they're needed because the weights don't fit in RAM. The second box also isn't simply splitting normal token generation in half. For Flash-Next, ToRc pipelines MTP across the two machines over USB4. โš ๏ธ ToRc isn't publicly released yet and these are the author's results, not independently reproduced benchmarks. Link in ALT
8
8
2
112
10,793
This may be one of the more important Healthcare specialized Local AI weight releases. Ant open-sourced the weights for Ling-3.0-flash-Sante. The model itself isn't new as Sante has been available through APIs since September but ... What's new is ๐Ÿ‘‰ you can now bring the healthcare model home. Stats ๐Ÿง  124B total parameters โšก only ~5.1B active/token ๐Ÿ“š 256K context ๐Ÿฉบ healthcare-specialized ๐Ÿ”Ž deep research ๐Ÿค– multi-agent collaboration ๐Ÿ”ง tool use It's built on the same Ling-3.0-flash architecture that already runs in llama.cpp. For reference, base Ling-3.0-flash GGUFs already exist around Q4_K_M โ†’ ~77GB IQ3 โ†’ ~54GB IQ2 โ†’ ~40โ€“46GB IQ1 โ†’ ~28โ€“31GB โš ๏ธ Those are BASE Ling-3.0-flash quants. I haven't found an official Sante GGUF yet. But now that the Sante weights are downloadable, this becomes a home model for ๐Ÿ–ฅ๏ธ 96/128GB workstations ๐ŸŽ high-memory Apple Silicon โšก DGX/RTX Spark-class unified memory ๐Ÿ”— multi-GPU local systems And healthcare is one of the places where Local AI can be useful for private documents + research + agent workflows can stay on hardware you control instead of being sent to a cloud API. Ant also reports substantial healthcare gains in the new release, including HealthBench Professional 45.73 โ†’ 54.29 AFUMED ComplexReasoning 65.22 โ†’ 76.92 Link in ALT
5
8
1
77
7,118
Wow, that's a pretty nice bump for Ling-3.1-flash. Ant introduced the new Ling-3.1-flash-1019 checkpoint, and its Artificial Analysis score jumped Ling-3.1-flash โ†’ 41 Ling-3.1-flash-1019 โ†’ 44 The highlighted gains come from its updated agentic performance AA-Briefcase ~1400 โ†’ 1524 Elo AutomationBench-AA 62% โ†’ 68% The existing Ling-3.1-flash is already open-weight under MIT and it's big. Stats ๐Ÿง  ~560B total โšก ~25B active/token ๐Ÿ“š up to 1M context Community GGUFs already go down to IQ1_S โ†’ 142GB IQ2_XXS โ†’ 174GB IQ3_XXS โ†’ 256GB Q4_K_M โ†’ 354GB The existing Q4 has even been loaded across 4ร— DGX Sparks using llama.cpp RPC. โš ๏ธ 1019 is a new checkpoint/update, not a new Ling architecture announcement. Ant hasn't released the updated 1019 weights yet. It says open weights + API are coming soon. Link in ALT
Ling-3.1-flash scores 41 on Artificial Analysisโ€™s Intelligence Index versus its predecessor. The 560B model I posted last week now has another reason to stay on the watchlist. You can test it before the weights arrive on OpenCode because it has added free hosted access, and Vercelโ€™s free trial runs through October 13. Vercel currently serves 262K context. The advertised ceiling is 1M. Still waiting on downloadable weights and confirmed local deployment requirements. Save the tasks it handles well now, then rerun them on a local quant when available. How much of that capability survives? Vercel link in ATL
2
7
1,009
Apparently, private Local AI roleplaying AI is a pretty serious use case. ReadyArt's new Wicked-Tutu family is already pulling serious downloads. And this is not a tiny model Stats ๐Ÿง  31B dense Gemma 4 ๐Ÿ’พ Q4_K_M โ†’ ~18.7GB ๐ŸŽฎ fits in 24GB-GPU territory ๐Ÿ“š up to 256K context ๐Ÿ  completely local Runs directly with โš™๏ธ llama.cpp ๐Ÿฆ™ Ollama ๐Ÿ–ฅ๏ธ LM Studio ReadyArt trained it specifically as a private local roleplay model, with a purpose-built dataset and thousands of scenario categories. The earlier v0.1 GGUF has already passed 17K downloads, and they're iterating fast enough that a Final 31B build is already out. Local AI isn't only competing with ChatGPT but it's enabling categories where privacy + customization + no cloud at all are the product. โš ๏ธ The HF metadata says Apache 2.0, but the model card also adds personal/non-commercial terms, so I'd treat the licensing as unclear for now. Link in ALT
4
2
7
956
This small Local AI model could replace an entire document-processing pipeline. ATH-MaaS released OvisOCR3. Itโ€™s only a 0.8B-class multimodal model. But one local model can now do all these things ๐Ÿ“„ document โ†’ Markdown ๐Ÿงพ document โ†’ structured JSON ๐Ÿ”Ž OCR + bounding boxes ๐Ÿงฎ formulas โ†’ LaTeX ๐Ÿ“Š charts โ†’ structured data ๐Ÿ”‘ key-value extraction ๐Ÿ–ผ๏ธ figure captioning ๐Ÿ”€ flowcharts โ†’ Mermaid ๐Ÿ“š cross-page table reconstruction That last one is interesting. Give it consecutive document pages and OvisOCR3 can determine whether a table continues onto the next page and reconstruct the complete table. Team-reported results OCRBench โ†’ 88.8 OCRBench KIE โ†’ 90.5 Cross-page table Relation F1 OvisOCR3 โ†’ 97.07 Qwen3.8-Max โ†’ 94.47 And itโ€™s ๐Ÿง  built on Qwen3.5-0.8B ๐Ÿ”“ Apache 2.0 ๐Ÿ  downloadable/local โš™๏ธ Transformers + vLLM + SGLang ๐Ÿ”Œ OpenAI-compatible local server through vLLM No official GGUF that I can find yet. Link in ALT
9
23
178
6,594
The company behind PUBG just trained its own 29B Local AI model from scratch. And the architecture is interesting. KRAFTONโ€™s new Raon-1 mini is โ€ฆ ๐Ÿง  28.8B total parameters โšก only 4.3B active/token ๐Ÿ’พ official Q4_K_M โ†’ 19.7GB ๐Ÿ“š 262K context ๐Ÿ”“ Apache 2.0 ๐Ÿค– reasoning + agent/tool use 18 of its 25 layers use fixed-state linear attention. Only 7 layers maintain a growing KV cache. KRAFTON says those layers use only ~8 KiB of BF16 KV per token. So even at the full 262K context, thatโ€™s roughly: ๐Ÿ‘‰ ~2GB of growing KV cache before other runtime/state overhead. And in KRAFTONโ€™s reported comparisons, this new 30B-A4B model beats Qwen3.6-35B-A3B on 11 of 18 listed benchmarks. Lots of new models coming for Qwen3.6-35B recently. โš ๏ธ Preview release. KRAFTONโ€™s benchmark results. Upstream llama.cpp support is still pending and KRAFTON provides its own branch today. Link in ALT
5
4
66
4,042
Nvidia lets you build a 1TB Local AI cluster out of DGX Sparks. & Nvidia has a playbook for AI clustering them. 8 ร— DGX Spark ๐Ÿง  128GB each โ†“ ๐Ÿ”ฅ 1TB unified memory across the cluster Nvidia now officially supports manually configured clusters of up to 8 x DGX Sparks using their built-in ConnectX-7 networking. And Nvidia says that 1TB is enough to run frontier-class models like GLM-5.3 locally. They specifically call out ๐Ÿง  larger models ๐Ÿ“š longer contexts ๐Ÿค– multiple concurrent agents ๐Ÿ‘จโ€๐Ÿ’ป multiple developers sharing one local backend โš™๏ธ distributed development They list models such as โ†’ GLM-5.3 Flash โ†’ DeepSeek V4 Flash โ†’ Qwen3.8 Flash Next And later this month Nvidia Sync Model Launcher is supposed to make it easier. Link in ALT
4
7
2
77
7,448
AMD and Intel agreed on something pretty unusual. A local PyTorch AI app shouldn't have to care whether the CPU underneath it is AMD or Intel. AMD is folding its ZenDNN AI optimizations into oneDNN, the library originally developed by Intel. AMD + Intel have now aligned on oneDNN as the default open-source x86 acceleration path in PyTorch. ZenDNN has been working on refining for ... ๐Ÿง  LLM inference โšก INT4 / INT8 / BF16 / FP16 ๐Ÿงฉ fused MoE operations ๐Ÿš€ vLLM CPU acceleration ๐Ÿ”ง optimized attention/matmul Now that work is being brought into the common oneDNN ecosystem AMD + Intel are also jointly developing ACE, new x86 AI matrix instructions. The plan is for future AMD/Intel AI instructions โ†’ oneDNN โ†’ PyTorch So local PyTorch software gets one x86 target instead of separate vendor paths. โš ๏ธ This does NOT make llama.cpp/GGUF faster, and AMD/Intel haven't published new performance numbers from the merger. ๐ŸŽฏBut for CPU Local AI, the two companies that spent decades fighting over x86 are now cooperating on the AI software layer. Link in ALT
3
9
1,249
Here we go! Purpose built AI generated LLMs! Then AI helped optimize the code that runs it. Recursive released Flint, a new coding/agent model designed specifically for fast local inference. Beats Qwen3.5/3.6/3.8 in some coding benchmarks! Stats โ€ฆ ๐Ÿง  39.8B total parameters โšก only ~2.5B active/token ๐Ÿ“š 262K documented context ๐Ÿค– reasoning + tool use ๐Ÿ”“ Apache 2.0 And there are official GGUFs: ๐ŸŸข NVIDIA NVFP4 โ†’ 22.9GB ๐ŸŽ Apple INT4 โ†’ 26.0GB Recursive recommends 48GB-class memory for these local builds, so think: ๐ŸŽ 48GB+ Apple Silicon ๐ŸŸข 48GB+ NVIDIA โšก 64GB RTX Spark Recursive reports its optimized runtime at ๐ŸŽ M4 Pro โ†’ >125 TPs ๐ŸŸข 64GB RTX Spark โ†’ >150 TPs And WIREDโ€™s Will Knight actually ran Flint locally on a 48GB Mac and reported it was fast and successfully handled the coding jobs he tried. Side Note: Recursive built Flint using its Eureka Machine, an automated AI research system that helped ๐Ÿงฉ design the architecture ๐Ÿงช develop training recipes โš™๏ธ optimize infrastructure ๐Ÿ’ป write hardware-specific inference kernels Nvidia says those specialized kernels improved Flintโ€™s RTX Spark generation performance by 55% wo changing the model weights. Recursive-reported coding results SWE-bench Verified โ†’ 74.2 SWE-bench Pro v2 โ†’ 89.7 Terminal-Bench 2.1 โ†’ 54.9 LiveCodeBench v6 โ†’ 80.3 So this isnโ€™t merely AI writing more AI code. Link in ALT
6
2
2
37
2,951
A single 24GB GPU can now run a 35B scientific research agent that spawns sub-agents and checks its own evidence. Sage-A1.5 is 35B / ~3B active, and its official Q4_K_M is just 21.7GB. Here are the new Sage-A1.5 model stats ๐Ÿง  35B MoE / ~3B active ๐Ÿ’พ official Q4_K_M โ†’ 21.7GB ๐ŸŽฎ fits a single 24GB GPU at moderate context ๐Ÿ“š 256K native context ๐Ÿ‘๏ธ multimodal ๐Ÿ”“ Apache 2.0 And it's specifically trained as a long-horizon research agent. So it is designed to ๐Ÿ”Ž use tools/search/code ๐Ÿค– spawn parallel sub-agents โœ… inspect its own evidence ๐Ÿ”„ change direction when research stalls No separate critic model required for its verification mode. These are the full-precision benchmark results PinchBench Sage-A1.5 โ†’ 90.0 Kimi K3 โ†’ 88.2 GLM-5.3 โ†’ 86.6 GPT-5.6 Sol โ†’ 87.3 FrontierScience-Olympiad Sage โ†’ 81.0 Kimi โ†’ 69.0 GLM โ†’ 67.0 GPT โ†’ 73.0 SWE-Pro Sage โ†’ 61.2 Kimi โ†’ 63.3 GLM โ†’ 64.6 GPT โ†’ 64.6 โš ๏ธ Those benchmark scores are from the BF16 checkpoint, not the Q4. But the same model now has an official 21.7GB GGUF with llama.cpp / Ollama / LM Studio support. Link in ALT
17
17
1
270
12,563
This might be my new favorite all-purpose local AI model. Fits nicely into 16GB of VRAM for an RTX 5060/5070TI. The new SparkX2.6-4B beats Qwen3.5-9B in 80% of shared benchmarks and 97% of Gemma4-12Bs. Stats ๐Ÿ’พ official Q4_K_M โ†’ 3.54GB ๐Ÿง  only 4B parameters ๐Ÿ“š native 1M context ๐Ÿ’ญ none / low / high thinking budgets ๐Ÿค– trained for local agents ๐Ÿ”“ Apache 2.0 It already runs with: โš™๏ธ llama.cpp ๐Ÿฆ™ Ollama ๐Ÿ–ฅ๏ธ LM Studio ๐ŸŽ MLX ๐Ÿš€ vLLM / SGLang In the team's reported benchmark suite Averages: Spark-X2.6-4B โ†’ 63.3 Spark-X2.5-4B โ†’ 52.1 Qwen3.5-9B โ†’ 49.1 So they're claiming a 4B model beats their tested 9B comparison overall. For normal local-agent contexts, though, a ~3.5GB reasoning/agent model with this runtime support is very interesting. Link in ALT
14
17
203
14,505
Underdog released Bark 3.0, and it's only a 163MB download. Runs locally w/Pytorch+CUDA or MLX On their Open ASR Leaderboard evaluation, Bark wins ๐Ÿถ Bark 3.0 โ†’ 4.94% WER โ†’ 163MB ๐ŸŸข NVIDIA Parakeet โ†’ 4.94% โ†’ 2.51GB ๐ŸŒ€ Whisper large-v3 โ†’ 6.04% โ†’ 9.26GB So Bark matches Parakeet's average accuracy while being ๐Ÿ‘‰ ~15ร— smaller And beats Whisper while being ๐Ÿ‘‰ ~57ร— smaller On recorded meetings check out these stats Bark โ†’ 7.82% WER Parakeet โ†’ 9.42% Whisper large-v3 โ†’ 13.63% And this isn't CUDA-server-only. ๐Ÿ  fully local ๐Ÿ“ฑ phone-class ๐ŸŽ MLX + Core ML ๐Ÿง  Apple GPU / ANE ๐ŸชŸ CPU + CUDA paths ๐Ÿ”“ CC-BY-4.0 I've checked and no GGUF. It uses its own compressed Bark format plus MLX/Core ML/Transformers runtimes. Bark 3.0 Plus is only 180MB and improves average WER to 4.76%. โš ๏ธ English only Link in ALT
1
3
26
2,078