

Building: Hos-T... Bumblebee... Cactus... Rhodo...
Joined December 2025
- Tweets1.2K
- Following185
- Followers35
- Likes286



Gemini has the worst chat experience in the world. It’s not just the limits you hit after one prompt, the product itself is useless for me. They messed up one thing I used to use it for on Android, so now I’m sticking with Bixby fo

26
its always hard to make these giants make realistic .
i dont know why it looks little off but i see this on hulk too its always a hard choice to go for these giants and making action scene's with them .
i think on this new trailer of Ramayana it looks little off.

1
2
50
Hari Dangi retweeted

Today we are rolling out Gemini 4 Argon globally in the Gemini API, to Pro + Ultra in Gemini App, and Ultra subs in Antigravity!
Argon is a huge step forward for Gemini, and a labor of love. This model has been battle tested by over 100,000 people at Google over the last month, with so much new innovation, ambition, and hard work baked into this release. The team has been heads down over the last 6 months working to make this possible across the stack (research, infra, safety, eng, etc).
We rolled the model out to cyber defenders as part of our fairwind program and early access customers over the last 2 weeks, it has been amazing to see and talk to folks who are now using this model daily. Seeing the models writing capability, raw knowledge and persistence for coding, paired with new features like 1M token output when the model needs to work more has gotten me even more excited about our path ahead.
This is just the start of the Gemini 4 era. As you saw with 3.5, 3.6, 3.7, and 3.8 Flash, our iteration speed with Gemini is fast : ) Now with Gemini 4 Argon to work from, I am cannot wait to see the progress continue, and most importantly see what this new model enables for the world.
This is such a special moment in the arc of technology, as millions of people everyday tackle problems they could never have thought possible before. Gemini 4 Argon was built to help you tackle the hardest problems. I have personally felt this spark with Argon and hope you do too. Onwards!!


Hello there .

Please welcome GPT-6 Sol and GPT-6 Luna to the GPT-6 universe.
GPT-6 Sol and Luna build on the advances behind GPT-6 Astra, bringing much of its strengths into faster and more affordable models to support work at scale.
We’ve also made caching and inference more efficient, and we’re passing the savings directly to you: 50% lower API prices for Sol and Luna compared with GPT‑5.6 promotional pricing.
100
Hari Dangi retweeted

Introducing GPT-6 Sol and Luna, bringing the advances behind Astra to faster, more affordable models. ✨
💻 Stronger coding and computer use
🎯 Improved factuality and alignment
💬 Clearer answers with less jargon
> On AutomationBench, Sol at xhigh effort outperforms Claude Opus 5 at max effort at just 9% of its cost per task.
> On OSWorld 2.0 offline, Luna at max effort exceeds GPT-5.6 Sol at medium effort at one-tenth the cost.
> Sol makes about half as many mistakes as GPT-5.6 Sol on our internal factuality evaluation of conversations where users previously flagged errors.
> Improved prompt caching helps agents reuse more context, with 90% discounts on cached input-token reads. Developers can change reasoning effort and tool availability without breaking cache.
Rolling out today in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise and Edu users, and available in the OpenAI API. Free and Go users can access Luna in the desktop app. These models are not yet available in Chat.
API pricing per 1M tokens:
Sol: $2 input / $10 output
Luna: $0.10 input / $0.50 output


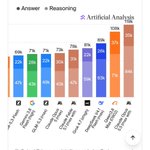
Why the fuck is everyone saying that this is way cost efficient model, this is that much token efficient and the cost per task is way lower than Opus 5 then why the fuck are artificial analysis benchmarks so bad?


Hari Dangi retweeted

Thought this was a joke, but i double checked. US Gov Federal Register use distilled Qwen models in their search mode.
The irony.


GLM 5.2 Who .

⚛️🇪🇺 Introducing Quasar 1.1 438B, the first AI model using quantum-generated data.
Quasar 438B, the best European AI model, just got a quantum upgrade: Part of its healing set was generated by a hybrid quantum language model running on @IBM Quantum System Two in Donostia-San Sebastián, a 156-qubit IBM Heron processor. It is the first time quantum-generated data enters the CompactifAI pipeline. Quantum computing is not a label on this release, it is part of how the model was built.
Sharper, less verbose, tuned for agentic work and ready for European deployment: served by a European company incorporated under EU law and developed in line with EU regulatory requirements, including the transparency expectations of the EU AI Act.

Readers added context they thought people might want to know
Multiverse Computing's own technical write-up states Quasar 438B is built from GLM-5.2, the open-weights model from Z.ai in China, "REAP'd"/compressed with its own pipeline. Thus, this isn't the "best European model", since it's not European.
multiversecomputing.com/papers/inside-…
68
Hari Dangi retweeted
In an exclusive interview, CNN’s Anderson Cooper asks Anthropic CEO Dario Amodei about a quote in a proposal Amodei wrote on Saturday about an AI “swarm” that is “capable of taking over the entire internet.”
I am ok if an unreleased model from any lab takes X.com down for 5-10 hrs. a guy with cripto/aiguru-news guy suggesting that we should not be slowing down ... they are banning opensource ... elon lost -- with this tweet. fuck off .

28
xitter.gq/deepseek_ai/status/209…
I’m already think that this model will be quite token hungry.

🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6

1
28