

Too alive to be organised
London, England
Joined June 2011
- Tweets22.1K
- Following1.3K
- Followers1.1K
- Likes5K


Pinned Tweet
My curated list of good follows for GenAI / ML
xitter.gq/i/lists/16576767776641…

Zengineering retweeted

You can't ship what you can't verify. Distributed systems are hard to verify because, like, 50% of the semantics have to be learned operationally. This is even true of something super vibe-able, like Raft. Here are some things prod will teach you the hard way:
* Raft's "correct behavior" is to livelock under even extremely vanilla scenarios, like "one node in your quorum is partitioned from another one." Yes, really. You'll have to adjust Raft itself to fix this. (And we did. This is why we introduced PreVote/CheckQuorum, etc.)
* Raft's simplicity largely comes from restricting recovery choices. There are lots of refinements of raft that account for common failure modes (e.g., LogCabin, which makes it possible to repair corrupted logs on many Raft nodes, which is super hard in vanilla Raft). But not all the fixes you'll want are well-understood, and you might have to implement a "shadow" protocol on top of normal Raft primitives. And you will have a lot of trouble proving that it really, verifiably, actually works.
* Storage substrates can and do lie to you about acknowledged writes. Can you hack around this? Maybe! Often goes in the "shadow protocol" though.
* Healing/failure recovery is its own "shadow protocol," and is often dependent on, e.g., traffic projections. A common failure mode is: if a node becomes unhealthy and then recovers, the system itself may never fully recover, because it has a bunch of queued work that it can't evacuate faster than normal work coming in. In this example you have to shed load, but in Raft that might mean starting over consensus, which is in direct conflict to point (2).
And on and on and on.
So, can distsys experience the 10x productivity uplift that the frontend does? Maybe! I think we'll have to fundamentally improve testing infra (@AntithesisHQ-style DST, prop testing, etc) and modeling infrastructure (TLA+ finally has its heyday?). I think there will be evolutionary pressure to deliver systems that do fewer things, but better. But none of these things is a real substitute for thinking about the semantics and learning about the system against real, prod workloads.

Me working on my side project: "Claude implement this huge feature and merge it when its done"
Me working on WarpStream: "We're super busy right now, but we can probably deliver that in Q1"
Why? Because WarpStream is a real business and even though the Agents can whip something up in a few hours, I can't just yeet that our the door to customers.
Zengineering retweeted

labs are def RLing on mech interp guys if you think otherwise you’re smoking something


We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Zengineering retweeted

Note the Twitter thread doesn't include the *failures* of LLMs to improve other LLMs.
So edits help for Qwen 3.5, which *has the preexisting visible flaw* of reaching the token limit in 93% of cases; but edits don't help Gemma 270m, which doesn't have this flaw. --

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…
I have a feeling anthropic does things like this already and that explains why Opus is so good
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…
If a model can be trained to understand and edit it's own weights then that becomes a form of meta cognition and continuous learning.
Could such a loop in humans explain our self consciousness ?
Zengineering retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…
Zengineering retweeted

You really think you can combat the onslaught of ai-enabled offensive cyber attacks with your artisanal, hand-crafted code?
Adorable.
Zengineering retweeted

Evolution doesn't benchmaxx. It optimizes for generality and robustness, because overspecialization makes a species fragile when the environment inevitably shifts.
Zengineering retweeted

The world's first great economic superpower was Indian, fed by the world’s greatest river system.
Its key drivers were its ports.
This area sustained the first long-haul trade network in history, lasting over a thousand years.
Episode 3 of The True Cradle.
1/45 🧵

Zengineering retweeted
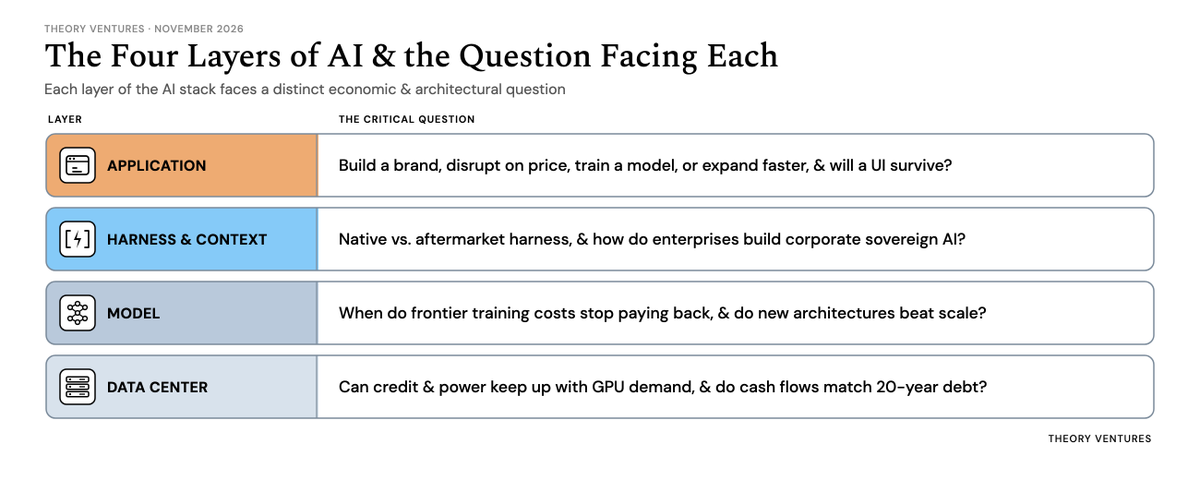
There are 4 layers in the AI stack, each with a fundamental question before it.
Zengineering retweeted
From the outside, few people have understood the type of internal tooling Uber has.
There's a tool called CAPRI that can capture production traffic, then replay it on-demand.
Building this system took years!! (evolved from other internal systems called Deputy + Cerberus)

How Uber replays real production traffic with CAPRI. From @udaykiran, Distinguished Engineer at Uber:
"If I want to test a new thing, how do I know every combination of these has no regression?
We have different businesses, different product lines, different cities. If you were to create all permutations across this, you would have to maintain thousands and thousands of tests across the stack. That alone is a really hard problem.
For some of our most complex platforms, we use capture replay. You can capture real production traffic with just one middleware, because now we have standardized language frameworks across all the services. It will capture not just the inbound and outbound at that service layer, but also any of the downstream APIs that service calls.
Let’s say I’m working on a bug that’s only affecting San Francisco Uber Eats trips. I fix that bug and then I can create a Slate environment for that bug for my code changes. I can say: replay just this request on my Slate environment and show me the delta and I’m expecting the fix.
See more of Uber’s latest AI Infra on the podcast: xitter.gq/GergelyOrosz/status/21…
Zengineering retweeted

Any company who publishes a benchmark, offers consulting, "loss analysis", databooks, etc associated with said benchmarks either directly or indirectly
Run any public benchmark and look at a failing task. Odds are you will encounter the following on the first trace you look at:
- Test is too narrow: Grader fails model, even though model did the right thing.
- Test is too broad: Grader fails model for something that is completely open to interpretation and not clearly specified.
- Harness sucks: needs no explanation LOL
- Ground truth was clearly written by another model, introducing bias
- Tests the format, not the right answer content (despite not requiring a specific format).
Pretty soon you understand that the only reasonable way to hill climb is to memorize the answer. This is just the tip of the iceberg.
Other vendors will take many of these poor quality benchmark, and combine them together with an arbitrary weight and combine them into a "single score", and people eat it up.
It's turtles all the way down
Zengineering retweeted

i'm seeing so much performance slop in the timeline.
> "How can we use data-oriented design principles"
> "Can we turn this pointer into an index"
Perf eng is get CPU flamegraph, maybe some heap , disk , and network profiles.
Make biggest bar on these profiles smaller, if not move to the next biggest bar.
Zengineering retweeted
Own your intelligence.
Anyone that opposes this has something to sell you (perhaps your own intelligence back to you.)
Local models need to continue proliferating. The “absolute unit” massive models may be out of reach for now locally, so your best option is to, indeed, keep your options open. Own your harness, data, connections, runtime: your agents. Embrace open source.
Zengineering retweeted

recommended reading. had the good fortune to talk with @tianyi a little while ago, and the DSH folks are one of the not so many teams doing innovative stuff in the harness space.
the below largely aligns with what we are gravitating towards at earendil as well. single, long lived entity, ad-hoc, freeform, possibly recursive delegation for actual tasks, cross-system event ingestion and triggers.
good stuff.

Zengineering retweeted

many creatives think of the absolute best creative people and how ai couldn’t possibly produce their level of work, and apply this conclusion to themselves. but you aren’t jk rowling or a gabriel garcia marquez, so it’s not useful to think like that


