

I make AI agents do real work, test what actually works, and show what it costs. Building tools along the way. Claude Code, Codex & more.
New York, USA
Joined March 2011
- Tweets978
- Following87
- Followers93
- Likes608




Pinned Tweet
not wrong at all, i ran the same kind of thing with a 3d car configurator. opus 5.5 looked best but hit my 40 min cap at $5.76, haiku 5.5 got a working one for $0.38. did you track cost per model? curious how sol 6.1 compared on yours
6 cents got me a toy. $3.78 got me a movie.
Pawel found Terra drops off hard below max effort. I hit the same wall at default.
One prompt, no help, a WWII plane chase in Three.js:
Terra (low): 56s, $0.06
Sol (medium): 17 min, $0.61
Sonnet 5.5: 39 min, $3.78
Opus 5.5: 40 min*, $5.11
*hit the 40 min cap in all 3 runs

I tested GPT-6.1 Terra on real work. 2 repos. 105 replanted bugs. Find and fix what you can.
The results:
- GPT-6.1 Terra (max): 40.7
- GPT-5.6 Terra (max): 32
- GPT-5.6 Terra (xhigh): 20
- GPT-5.6 Terra (high): 18
- GPT-6.1 Terra (xhigh): 11.3
- GPT-6.1 Terra (high): 9.7
It's cost and time effective. But right after max, its performance drops dramatically - far below Haiku 5.5 (xhigh).

you don't need opus for this. sonnet 5.5 built this jet engine in blender 12 times, all from code, about $0.57 a run
tried 3 add-ons people use to cut the bill too: ponytail $0.57, caveman $0.51, rtk $0.58 per engine. same quality, bills within ~10%

Everyone's using Claude Opus 5.5 to build entire worlds in #threejs.
I spent 7 days on a single human eye.
No textures. No 3D models. No photos. Just math, light and ~400 parameters.
Sound on 🔊 Link below 👇
measured what one 3d build actually costs. sonnet 5.5 wrote this jet engine in blender 12 times: plain, and 3 add-ons people install to cut their bill (ponytail, caveman, rtk). 3 runs each
median cost per engine:
plain $0.57
ponytail $0.57
caveman $0.51
rtk $0.58
1 run said ponytail cut the bill 30%. 3 runs said 0%. test an add-on once and you're mostly measuring luck

Stop burning Claude or GPT quota on basic 3D animations. Save this $0 pipeline:
1 - create a free model on Tripo or grab any from Sketchfab
2 - upload your mesh to Mesh2Motion, rig it, and apply existing animations
just a couple of minutes, literally $0 spent, and I have a ready-to-use snake for my project
measured how far it actually goes. same 8-file feature, default settings, share of one 5-hour window per task:
sonnet 5.5: 3% → ~33 tasks
haiku 5.5: 5% → ~20
codex sol 6.1 on chatgpt plus: 5.5% → ~18
opus 5.5: 15% → ~6
on pro the model you pick matters more than the plan


never thought i'd say this but claude's $20 plan is incredible value with opus 5.5
i've been on the 5x max plan for a long time but 2 weeks ago i realized i wasn't even hitting the 5-hour limit no matter how much i used opus 5.5, so i downgraded to the pro plan
it's much better value now than it was a few months ago
here's part of the answer. same 8-file feature on claude pro, default settings: opus ate 15% of the 5-hour window per task. sonnet ate 3%
claude pro, sonnet 5.5: ~33 tasks per window
claude pro, haiku 5.5: ~20
chatgpt plus, codex sol 6.1: ~18
claude pro, opus 5.5: ~6
haiku is the "cheap" model and still lost to sonnet


Anthropic should explain why Opus 5.5 usage limit is draining so fast and we got no reset.
Everyone tag @AnthropicAI @bcherny @claudeai @ClaudeDevs
tested 4 of the popular ones on real tasks. 3 didn't save money
sonnet 5.5, same bug + same 8-file feature, hidden tests, api prices:
ponytail: -34% on the big feature. but +20% on the small bug
caveman: cut output 21%. bill dropped 3%
superpowers: +32% on the bug. 1 more test passed
answer-me-with-html: never turned on in 6 runs
you mostly pay for the agent re-reading your code, not for what it writes
part 2 is running now. same savers, but the job is a 3D jet engine built from code


ive been messing around with ways to make Claude Code use fewer tokens (so I stop hitting my limit so early 😅)
one thing I noticed is how many tokens it wastes searching through files just to understand a repo
this weekend I hacked together a tool that gives it a codebase map instead. tested it on 6 repos and it actually decreased token usage quite a bit 🧵
tools tested:
ponytail v5.3.2 github.com/DietrichGebert/po…
caveman v4.0.1 github.com/JuliusBrussee/cav…
superpowers v7.0.0 github.com/obra/superpowers
answer-me-with-html v0.5.5 github.com/QingYunA/answer-m…
3 runs per tool per task, 6 for the bug baseline + caveman. small sample, so caveman's -3% is noise. on the big feature ponytail saved the most but never hit a perfect score, plain did once

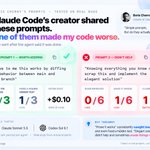
Claude Code's creator shared these prompts. One of them actually made my code worse. I tested 2 of
@bcherny
's prompts on real coding tasks. One caught bugs in 3/3 runs. The other improved 0/6 — and broke a passing test once. Small sample, but I didn't expect that result. Full comparison below 👇

Claude Code's creator shared these prompts. One of them actually made my code worse.
I tested 2 of @bcherny's prompts on real coding tasks.
One caught bugs in 3/3 runs.
The other improved 0/6 — and broke a passing test once.
Small sample, but I didn't expect that result.
Full comparison below 👇

12 of 12 runs told me "done". 3 actually passed my hidden tests.
same 8-file feature, 4 agents:
codex sol 6.1 medium: 2 of 3
codex sol 6.1 low: 1 of 3
opus 5.5: 0 of 3
sonnet 5.5: 0 of 3
most said "full test suite passes". their own tests did. mine didn't.
how do you verify before you merge?
🤖 Made with AI

Sergey | AI Builds & Tests retweeted

Posted the full numbers here, with the method: xitter.cf/Moriarty_tech/status/2…

Is Opus 5.5 nerfed, or is it just eating limits faster? I checked my logs instead of vibes.
Claude Code token logs vs my limit tracker (2 Max accounts, % read every 2 min):
- Oct 11–16: 8.7M tokens per 1% of the weekly limit
- Oct 18–21: 8.8M per 1%
Same price per token. What changed is me: ~17% of the week per day before, ~32% now.
Quality is a separate question, Nerf Bench covers that. Has anyone else checked theirs?
the codex review part is the real cheat code. i measured it.
same 8-file feature, 4 agents, 12 runs. all 12 told me "done". 3 actually passed my hidden tests. all 3 were codex.
codex sol 6.1 medium: 2 of 3
codex sol 6.1 low: 1 of 3
opus 5.5: 0 of 3
sonnet 5.5: 0 of 3
opus wrote "the full test suite passes". its own tests did. mine didn't.
which one reviews your PRs?


The biggest cheat code in agentic coding is having Claude Opus 5.5 open a PR, wait for Codex to automatically review it, then fix whatever Codex finds. Repeat this a few times before merging.
Opus might be the best coding agent, but GPT Sol 6.1 is the best code reviewer. It catches things Opus misses.
been splitting codex and claude too. measured it to see if it's worth it:
same 4 jobs, hidden tests, api prices:
small bug: haiku $0.013 vs opus $0.199
hard bug: sonnet $0.15 vs opus $0.52
8-file feature: codex $0.41 vs opus $1.82
3d car: opus $5.76, never finished. haiku $0.38
picking per job = 3-16× cheaper

The way I use agents (Oct 21)
Currently My AI usage is split between codex and Claude Code, but I use them both differently than I did a month ago.
The way i use codex is mostly through my dot. Every morning I call my dot and put my AirPods in and I walk have a conversation for about 45 minutes.
I try and handle as much work stuff as I can during that conversation. I respond to emails, write instructions for my editors, and do any planning for the day. Small tasks my dot does it, longer tasks I ask it to spin up a codex session.
I REALLY wish I didn’t have to dial and wait for my dot to answer @OpenAIDevs
When I’m at my desk doing coding work, document creation, or video editing I use Claude code. But, I’m not using normal Claude code I’m using Claude Code projects.
The same way dot is a codex coordinator, Claude projects is a Claude code coordinator. Both allow you to spin up cloud sessions and local sessions.
If I need to use computer use I will ask dot to fire up a codex session on my MacBook (that is always on) to do a task. Codex computer use is in leave of its own.
For coding work or editing work that requires my MacBook I’ll ask my claude projects.
Right now I have many Claude Code Projects for… each project. Sometimes I wish it was a single coordinator that could manage and organize all my work… like the way I use dot.
Both Claude and Codex have a grokbot skill for anything Twitter related. So if any task involve x, they will delegate to Grokbot which is very useful as a creator.
But the fact that I can’t see which model is being used when keeps me from using Grokbot. I know I can have Grokbot delegate to cursor which can specify a model but cursor is very expensive when using frontier models compared to codex and Claude, so I don’t end up doing that.
$5.5M says coding agents should remember what happened across tools. i needed that for a dumber reason: codex kept hitting its limit mid task so i built carryforward. limit hits, the session moves to my other account and keeps going the risky part turned out to be the handoff summary. it carries the old agent's "done" even when the tests never passed

We’re betting our $5.5M seed round that the next leap in AI coding won’t come from OpenAI or Anthropic.
It’ll come from a new feedback loop that learns from you.
Introducing Beacon: open-source, self-improving memory for coding agents.
Your sessions capture how you debug and solve problems. Today, that context gets lost and you have to re-explain things every time you switch tools.
Beacon continuously distills your sessions into reusable skills across Claude Code, Cursor, Codex, and 20+ harnesses, so your next agent can learn from the last.
Beacon is free and OSS 🌟 github.com/Asymptote-Labs/ag…
Why should the frontier labs be the only ones winning with your sessions?
You already did the work. Now let your coding agents learn from you.
free and open source: github.com/sergestack/carryf…

A clearer takeaway from this test: 12.2× the cache reads, nearly the same estimated cost.
The skill cut output by 68%, but added cache reads and writes that roughly offset the savings.
One run each. Check the token breakdown—not just the price.


pulled the token split from a claude code skill test. the skill cut output tokens 68% but the bill didn't move
output 3,501 · cache writes 32,980 · cache reads 122,837
5 calls instead of 1, each re-reading context. for agents the reads are the bill, not the output. anyone measuring cache_read per task in their own agents?

this is the part people underrate. in my last test cache reads were 77% of all tokens and output was 2%. the money is in what gets re-read, not what gets written

this is how to run Claude Code cheaper than 99% of people
Anthropic just shared one of the best cost-cutting features Claude Code has ever had.
the idea: let Claude Code compact your big session before the cache expires, so you never re-pay for the whole conversation.
one message after lunch on a 250K-token Opus 5.5 session: $1.00 without it, about $0.05 with it.
it's already on since v2.1.299. tune it like this:
CLAUDE_CODE_IDLE_COMPACT_MIN_TOKENS=150000
here's how it works:
→ your session is over 200K tokens
→ you go idle
→ at about minute 54, right before the one-hour cache expires, it compacts
→ you come back to a short summary instead of a full-price re-read
the two settings worth knowing:
→ CLAUDE_CODE_IDLE_COMPACT_MIN_TOKENS sets the threshold (default 200K)
→ "idleCompaction": false in settings.json turns it off, for when you need the full history intact
and run /usage once in a while. it now warns you about max effort, always-on context and huge tool results, the three things quietly eating your bill.
the cache was never the problem. walking away from it was.
save it, it'll come in handy.
↳ code.claude.com/docs/en/chan…