

Data Engineer | Azure & Databricks | Data Warehousing & Lakehouse
Logfile
Joined October 2023
- Tweets3.8K
- Following4.1K
- Followers1.3K
- Likes5.8K




тЗх | هندسة البيانات retweeted

“The AI models are getting smarter and smarter... But inside the enterprise, we’re not seeing the same level of progress.” — Databricks Co-founder and CEO @alighodsi
The missing piece is business context.
Enterprise knowledge is siloed across systems, and not everyone should have access to all of it. Searching everything on demand is slow, costly, and incomplete.
At DATA + AI LIVE, Ali explains how Genie Ontology automatically builds a permission-aware metadata graph across enterprise data and connected systems, so AI agents know where to look and deliver better answers, faster, for fewer tokens.
Watch on-demand: youtube.com/live/BsVfRCNI8IY
тЗх | هندسة البيانات retweeted
More ways to build, validate, and manage data preparation workflows in Lakeflow Designer 🫡
Our October roundup highlights the latest enhancements:
• Guardrails for data quality checks, with control over what happens when checks fail
• No-code operators for cleaning and deduplication
• Multi-table joins in a single operator
• Parameterized inputs and outputs
• Visual version history to easily review workflow changes
databricks.com/blog/whats-ne…
тЗх | هندسة البيانات retweeted
[DEMO] With the Databricks Excel Add-in, bring the right Databricks data into Excel with more flexibility and less repetitive work:
→ Generate cascading filter values to narrow data before importing
→ Reuse existing Databricks SQL queries directly in Excel
→ Use custom functions like DATABRICKS.SQL and DATABRICKS.Table to import data into your workbook
Watch the full demo to see how they work: youtu.be/GKQt543lGDg
тЗх | هندسة البيانات retweeted

من على الرمضا مشى حافي القدم يستاهلك
توحيد السعودية (23 سبتمبر 1932م) 🇸🇦
тЗх | هندسة البيانات retweeted

Very few people will actually notice the step change from GPT 5.6 to GPT 6 Astra. The reason is simple: most everyday tasks are already saturated. AI is already at 100%.
I can ask ChatGPT to find the email of a babysitter, email her, send a calendar invite, then text my wife. Or take a photo of my bike tire, have it identify the exact tire, research it, and tell me the right PSI.
It already does all of this extremely well. There is no 120%.So if I switch to Astra, I may see almost 0 difference. Maybe it is faster and cheaper, but with a subscription you barely feel either.
The capability jump will be obvious if you are at the frontier of coding, math or science. For everyone else, AI has become so good that the next huge leap might feel surprisingly invisible.
тЗх | هندسة البيانات retweeted

GPT-6 Astra represents a step-function change in model capability for interactive reasoning problems. It scores 66% on ARC-AGI-3 using our standard harness, and nearly 100% with a continuous conversation harness and custom compaction, at a cost of roughly $360 per game.
In fact, the continuous harness version significantly outperforms our human baseline in action efficiency across almost all levels. When we examined the reasoning chains to understand how the model operates, we found it performing highly efficient, on-the-fly symbolic world modeling for each game and level. It goes as far as developing its own shorthand DSL to represent in-game situations -- essentially a game-specific algebraic notation.
Overall, Astra exhibits symbolic modeling behaviors we had previously only seen with sophisticated harnesses -- so harness capabilities are increasingly shifting into the model itself.
We see Astra as a major breakthrough in model intelligence.
Read our post on Astra and what these results mean: arcprize.org/blog/astra

тЗх | هندسة البيانات retweeted

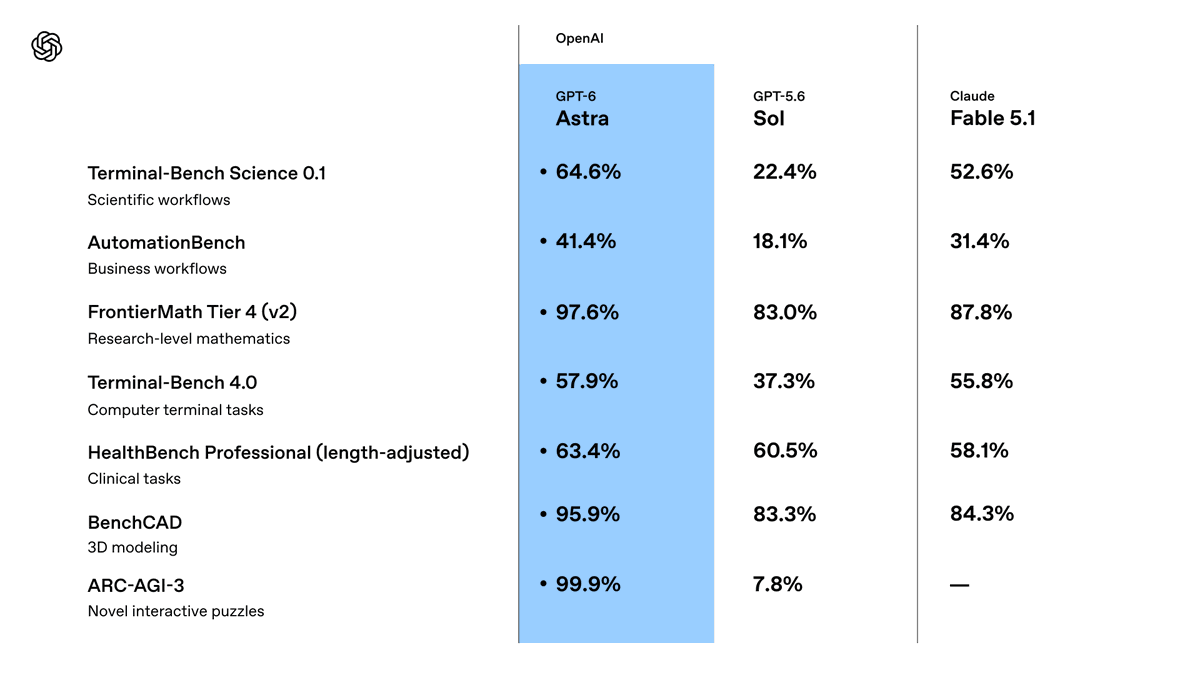
GPT-6 Astra is state-of-the-art on FrontierMath Tier 4, ARC-AGI 3, and TerminalBench-4.0.
GPT‑6 Astra is also a major advance for scientific discovery, with state-of-the-art performance on Terminal-Bench Science 0.1 and HealthBench Pro.
тЗх | هندسة البيانات retweeted

This is the tech behind sakana fugu, they use a slm to eval and router tasks behind models; arxiv.org/pdf/2512.04695 github.com/nshkrdotcom/trini…

Introducing Sakana Fugu: A full multi-agent orchestration system accessible via a single model API.
Our ‘Fugu Ultra’ model matches the performance of Fable and Mythos, delivering frontier capability without the risk of export controls.
Try it: sakana.ai/fugu 🐡
тЗх | هندسة البيانات retweeted
We're bringing millisecond performance directly to the lakehouse.
Databricks Co-founder and Chief Architect @rxin introduces Lakehouse//RT, Databricks’ new real-time data warehouse designed for operational analytics, BI and app serving, and observability workloads.
Lakehouse//RT is powered by Reyden, a breakthrough new engine for real-time workloads that require immediate responsiveness at high concurrency.
Learn more: databricks.com/blog/introduc…
тЗх | هندسة البيانات retweeted
Introducing Lakehouse//RT, a real-time data warehouse that delivers millisecond responses at massive scale without data movement.
Support real-time workloads while using the same open formats, governance, and data architecture already powering your analytics and AI. databricks.com/blog/introduc…


тЗх | هندسة البيانات retweeted

Huge news!
After 38 years, C++23 finally removes Garbage Collection from C++

тЗх | هندسة البيانات retweeted

This week we wrapped up our @databricks series!
We covered:
1. Importing Data from flat files and connecting to Data Sources
2. Analyzing data using SQL Editor and Notebooks
3. Visualizing and Creating Dashboards
4. Using AI to code and talk with our Databases
You can learn all of this for Free in this series using Databricks Free Edition!
I plan on adding to the Databricks Series in the future! Check out the playlist below!
Link: youtube.com/playlist?list=PL…

тЗх | هندسة البيانات retweeted

إذا كنت تقني وراتبك الأساسي أكثر من 6000 ﷼ وتعمل في شركة تقنية
غالبا أنت تستحق مكافأة 86,000 ﷼ إذا استمريت مع نفس الشركة 18 شهر، (يعني متوسط شهري 4800 ﷼ بالإضافة إلى راتبك)
تعرّف على برنامج "تمكين" التابع لـ "البرنامج الوطنى لتنمية تقنية المعلومات"


тЗх | هندسة البيانات retweeted

NVIDIA research just made LLMs 53x faster. 🤯
Imagine slashing your AI inference budget by 98%.
This breakthrough doesn't require training a new model from scratch; it upgrades your existing ones for hyper-speed while matching or beating SOTA accuracy.
Here's how it works:
The technique is called Post Neural Architecture Search (PostNAS). It's a revolutionary process for retrofitting pre-trained models.
Freeze the Knowledge: It starts with a powerful model (like Qwen2.5) and locks down its core MLP layers, preserving its intelligence.
Surgical Replacement: It then uses a hardware-aware search to replace most of the slow, O(n²) full-attention layers with a new, hyper-efficient linear attention design called JetBlock.
Optimize for Throughput: The search keeps a few key full-attention layers in the exact positions needed for complex reasoning, creating a hybrid model optimized for speed on H100 GPUs.
The result is Jet-Nemotron: an AI delivering 2,885 tokens per second with top-tier model performance and a 47x smaller KV cache.
Why this matters to your AI strategy:
- Business Leaders: A 53x speedup translates to a ~98% cost reduction for inference at scale. This fundamentally changes the ROI calculation for deploying high-performance AI.
- Practitioners: This isn't just for data centers. The massive efficiency gains and tiny memory footprint (154MB cache) make it possible to deploy SOTA-level models on memory-constrained and edge hardware.
- Researchers: PostNAS offers a new, capital-efficient paradigm. Instead of spending millions on pre-training, you can now innovate on architecture by modifying existing models, dramatically lowering the barrier to entry for creating novel, efficient LMs.


