

@TechMDAI
Account based inUnited States
About this account
- Account based in
- United States
- Connected via
- United States App Store
Account-level information from X, not a live location or the device used for a specific post.
🔬 MD fueled by a deep passion for Medicine & Tech. 🌐 Exploring the frontiers of VR/AR/MR & BCI. 🤖 AI enthusiast.
Joined June 2023
- Tweets12.3K
- Following3.8K
- Followers2.9K
- Likes39.8K





TechMD retweeted

I uploaded the custom GLM 5.3 Flash to hugging face and if you use the recommended test build of ROCmFPX for GLM you should get prefill above 400 tok/s over 100k tokens.
Everything is explained in the model card.
Should work well on Strix Halo 395+ 128 GB. Hope it works well for everyone like it does for me.
If you use any of the GLM code boosts in your projects please give credit to ROCmFPX
huggingface.co/cafonez/GLM-5…

TechMD retweeted

The inner display is so nice for something like the files app. Makes it so easy to see so much more. I love it


TechMD retweeted

Sage A1.5 🔬 New agentic model built for long horizon scientific problem sloving
- 35B MoE
- 256k context
- Parallel subagents
- Built in self-verification

TechMD retweeted
A loved one falls and can't get up, and I want a tiny robot that finds them without sending video of my home to the cloud.
But Ray, you don't even have the robot yet.
Right, it won't be out until around Christmas. So Gemini 4 Argon planned it, my DGX Sparks trained it in a simulated apartment, and the vision model running at home said the person appears to have fallen and possibly needs assistance.
0:00 This thing called MicroDuck
2:06 Camera frames never leave the home
5:40 Here is the actual duck
TechMD retweeted
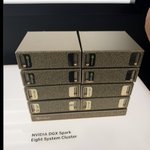
this golden dgx spark cluster might be the biggest thing for local ai this year
> 8 sparks, 128gb each
> 1tb of unified memory in one stack
> 200g networking on every spark
look at the back of it, gold foam on every box and the 200g cables looping out, it's the most beautiful cluster i've ever seen
i ran ling 3.1 flash, a 560b moe, on the 4 sparks, wired in a ring with no switch, and the 4th spark had no direct link to the head so it went through a relay, a switch puts every spark one hop away from the rest
nothing official on it yet, but if this ships you start with one spark on your desk and grow it to 8
the condition got worse and only @NVIDIAAI has the cure 💚


TechMD retweeted

I'm the Chief of LLM cycling aerodynamics and my work is paying dividends 🥸🤡😅
xitter.cf/SeraAndroid/status/211… – at Großbeeren, Deutschland

TechMD retweeted
Careful. They’re addictive. I run four and would be okay with selling a kidney to get four more 😉
TechMD retweeted
Found my kind of place at @NVIDIAAI GTC Berlin. Including the (for now) proof-of-concept switch. I counted 2 pairs of 5 ports - so you’d be able to pair up to 10 DGX Spark systems with breakout cables.


TechMD retweeted

DeepSeek Search debuts on the Artificial Analysis Search Index at 69, 17th of 27 search products, at the lowest price of any paid Search API on the board
@deepseek_ai launched its Search API on 17 October. We benchmarked it in our Stirrup agent harness, where GPT-5.6 Luna (medium) calls DeepSeek Search as its web_search tool to complete a combination of tasks from BrowseComp, DeepSearchQA and AA-Omniscience.
At $0.75 per 1k searches, DeepSeek Search costs less per search than any other paid Search API we benchmark, below Octen, Parallel (turbo) and Parallel (fast) at $1. At about $0.032 per task, it is the 5th cheapest of 27 products, cheaper than 20 of the other 25 Search APIs (median $0.066) and level with Nimble (lite). TinyFish, Octen, Parallel (turbo) and Parallel (fast) cost less.
Key benchmarking results for DeepSeek Search:
➤ Artificial Analysis Search Index: DeepSeek Search scores 69, a 36-point lift over the same model with no search (33). It sits between TinyFish at 71 and Linkup (standard) at 68
➤ AA-Omniscience is DeepSeek Search's strongest benchmark: it scores 70% accuracy on our proprietary factual answer benchmark. This ranks 10th of 27, 3 points behind the joint leaders, Exa (auto, dynamic highlights) and Firecrawl (73%). BrowseComp, which needs multi-hop reasoning across several searches, is its weakest benchmark: at 63% it ranks 25th of 27, well behind the Perplexity variants and Octen (85% to 87%)
➤ Large search results: each search returns about 7k tokens, near the top of the board's range. Each result carries about 1.8k characters of passages from the page. This raises model cost: at about $0.023 per task, DeepSeek's model cost is the 2nd highest on the board, behind Linkup (flash, alpha) at $0.039
➤ 128-character query limit: DeepSeek rejects queries longer than 128 characters. 6% of the agent's searches hit this limit, and for 87% of these, the model's first shorter rewrite worked
Key details:
➤ Setup: GPT-5.6 Luna (medium) in Stirrup, DeepSeek Search API with need_content=false (page passages, no full page content) and 10 results per search
➤ Pricing: $0.75 per 1k successful searches. DeepSeek does not bill empty results
➤ Rate limit: 5 searches per second per account


Love the setup , the rack looks very clean

And then there were 5. 🤪👇
I swear @NVIDIAAI Sparks/ Gb10s are like Pringles... once you pop you can't stop. Starts with 1, then you end up with a whole rack, mikrotik switches + breakout cables.

TechMD retweeted

Testing this recipe by BlackwellBoy right now!


TechMD retweeted

GLM 5.3 Flash now runs on ZIG on ALL configurations
- TensorFold ZIG
- TP2, TP3, TP4
- works with or without a switch
- separate branch than main
Main it still python until I'm sure everything is stable.
I'd like to thank @hecisaza for his work on this.
Get it here:
github.com/MiaAI-Lab/GLM-5.3…

GLM-5.3-Flash on DGX Spark: the Zig engine now runs on a ring of four GB10s, no switch.
1M-token prompts
~7× faster on repeated prompts
428/428 replies identical to the Python engine
10 PRs merged into @MiaAI_lab zig-engine branch this week.
github.com/MiaAI-Lab/GLM-5.3…
TechMD retweeted

My dream compute setup is 6 Mac M5 Ultra 512GB machines in a cluster. Six would give 3T parameter capability. 🤯
True frontier level power in your hands. It is just a mear $120k setup 😅
TechMD retweeted

We’re opening a research preview of Claude Duet, a new app where Claude works as a proactive agent.
It comes to you with what needs your attention, completes tasks you ask of it, keeps working when you step away, and checks with you before it acts on your behalf.