

Building with AI & LLMs // Running frontier open models locally
Joined July 2022
- Tweets14.1K
- Following361
- Followers42.3K
- Likes18.1K



sparkDash 2.70 is out ⚡️
This is a MAJOR release.
New pages
- Cost compare: see what your fleet's token usage would cost on any hosted model, including cached-prefill savings
- Temps: daily and weekly GPU temperature graphs for every unit
- Metrics history per unit (48h and 30 days, opt-in), with a History panel on the unit page
Engines & hardware
- New engines: Strata & Flare (tok/s and benchmarks) and Radiance (live rates)
- Intel Arc GPU support
- AMD GPU telemetry
- GPU clock cap shown on each unit, and you can set it from Edit unit. If the unit has no passwordless sudo, the dashboard asks for the password, or you can run it on the Spark yourself
Benchmarks
- Decode bench: pick the temperature (default 0.7) and turn thinking on or off for prose. Both show on copied results and the share card
- Tool Eval Bench "Show card": a shareable image of a finished result
- Comparison card: tick two runs and get one image showing the difference
- Compare a run from one Spark with a run from another, plus an expandable scenario list
- MAX_ACTIVE_BENCH_JOBS setting to raise the fleet benchmark limit
Overview & monitoring
- Overview cards list every loaded vLLM model, plus CPU temp, CPU power and the engine's parallel slot count
- Token totals for the last 24h, 6h and 1h, with one row per unit and model
- Optional card showing inference request activity
- Alerts to ntfy, Discord, Slack or a webhook (opt-in), plus a tab badge and desktop notifications
Other
- "Run both" button in the Models panel
- "Back to Overview" link on every unit page
- Published container image
Link below.

I've tested Flint 40B. It's very fast.
Unfortunately, it's not, in any way, shape or form, a replacement for Qwen3.6-35B.

Flint - 40B params total, 2.5B active
It's @Recursive_SI's first model. Claims to run at 150 tok/s on a DGX/RTX Spark. Looks interesting enough to test!
Could it beat the legendary Qwen3.6-35B?
GLM 5.3 Flash now runs on ZIG on ALL configurations
- TensorFold ZIG
- TP2, TP3, TP4
- works with or without a switch
- separate branch than main
Main it still python until I'm sure everything is stable.
I'd like to thank @hecisaza for his work on this.
Get it here:
github.com/MiaAI-Lab/GLM-5.3…

GLM-5.3-Flash on DGX Spark: the Zig engine now runs on a ring of four GB10s, no switch.
1M-token prompts
~7× faster on repeated prompts
428/428 replies identical to the Python engine
10 PRs merged into @MiaAI_lab zig-engine branch this week.
github.com/MiaAI-Lab/GLM-5.3…
Mia retweeted

Absolute scenes with this decode speed.
TensorFold isn’t trading output quality for speed. Our speculative decoding produces the exact same tokens as serial decoding under the same model and runtime settings.
No approximate token acceptance. No divergence introduced just to go faster 👀


People still don't seem to get it.
The access Grok @bot has to X is MASSIVE. No other "bot" alternative has it or ever will.
And where does the AI audience spend its time? That's right - on X.
Not only Anthropic & OpenAI are too late, they literally have NOTHING to offer that would make their products better. ZERO
SpaceX has already won.

Mia retweeted

This is so important and fundamental

AI keeps running into atoms.
NVIDIA targets SPIL CPO optical-engine 200GBps made by TSMC Coupe
NVIDIA's side of the Optical Cold War: secure the optical supply behind the GPUs. The moat reaches into the supply chain. $NVDA


Here's Anthropic's answer to Grok @bot 👀
Claude Duet - waitlist only for now.
"Claude Duet is a proactive agent that understands what needs your attention. It takes on tasks of all sizes, keeps working while you’re away, and waits for your ok when it matters."


Flint - 40B params total, 2.5B active
It's @Recursive_SI's first model. Claims to run at 150 tok/s on a DGX/RTX Spark. Looks interesting enough to test!
Could it beat the legendary Qwen3.6-35B?

Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
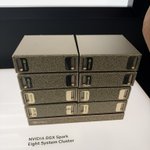
sparkDash in @NVIDIAGTC !!! 🔥
Lots of improvements and additions coming!


