

AI that runs only on your device, never on a server. Works offline. Completely private. Free, without limits.
Joined June 2026
- Tweets94
- Following49
- Followers103
- Likes212



Pinned Tweet
The progress that's been made in local AI this year isn't comprehensible until you visualize it. Hopefully this helps!
Shoutout to @liquidai @Alibaba_Qwen @GoogleDeepMind for driving many of these gains.
Loci now runs Phonon as the default TTS engine on mobile. Try it out today at our link in bio

A new frontier for on-device speech.
We're open-sourcing Phonon, a suite of TTS models under 50m parameters, setting a new standard for naturalness and accuracy across languages, with the broadest inference support to date.
Phonon-31m is available under Apache 2.0.
gradium.ai/phonon🧵
Loci retweeted

This idea seems really important.
In another few years, what percent of prompts will be solved locally, or on virtually no compiute? I'd guess 95%+, probably 98%+?
So AI datacenter companies (and all but the very very best models) basically lose any non-large scale demand.

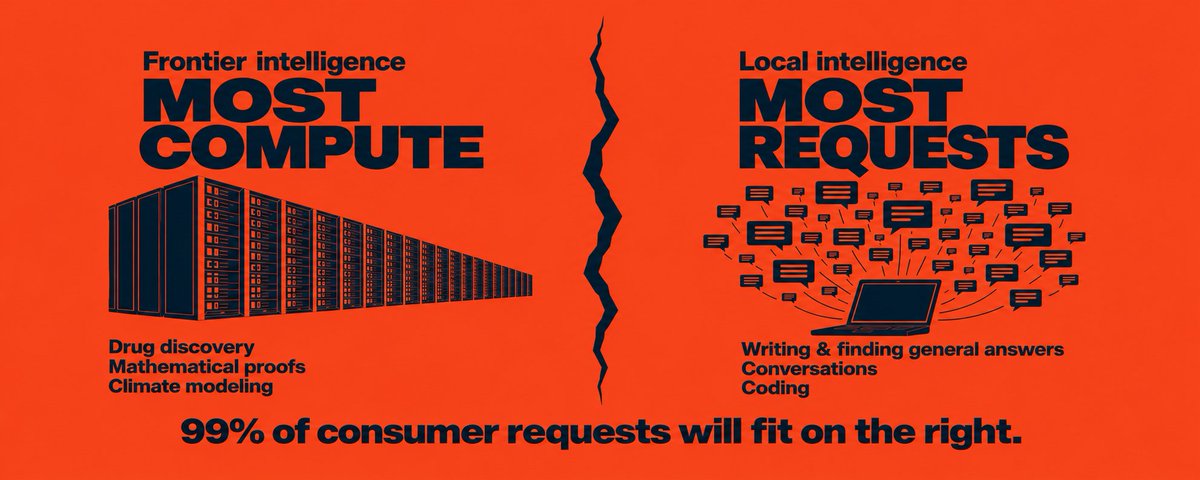
77% of ChatGPT messages are prompts a laptop can answer locally. 95% of its users pay nothing. The industry's answer is $100B+ data centers.
The AI world is splitting in two, and the next great AI company gets built in the gap.
Most AI investors have it backwards.
Here's why we're so focused on local intelligence:
77% of ChatGPT messages are prompts a laptop can answer locally. 95% of its users pay nothing. The industry's answer is $100B+ data centers.
The AI world is splitting in two, and the next great AI company gets built in the gap.
Both cloud getting more efficient as well as more traffic going on-device will mean there will be many empty datacenters.

1/ Are we overbuilding compute for AI?
Introspection on eve of release of DeepInfer - the most economically valuable software release of history (on par with Claude Code).
DeepInfer has even a bigger money printer, if your are to believe latest numbers compared to what @SemiAnalysis_ reported.
They can make 149B revenue from 1GW of GB200 without slack, and 100B with very big slack at DeepSeek's current prices, while serving fast tokens at 230 tokens/sec per user at 38$ per GPU hr of GB200. The performance is reproducible. (I will explain the calculations in following tweets)
These numbers are much higher than numbers reported by SemiAnalysis below at 15B revenue per GW with B200 GPUs (not GB200) with the same model DS Flash 4.1. The difference shows the power of NVL72 architecture are large scale up domain.
Large domains afforted by NVL72 allow to have large scale up domain for decode of 64 GPUs (WideEP). This allows for much less use of HBM on each GPU for weights (spread out), and more use for long sequences and batches. This allows them to serve 200+ tokens per second per user and still make 38$ revenue per GPU.
If those numbers check out, implications are massive!
Impact on demand and supply:
---------------
Now imagine with 50GW compute by 2027 that SemiAnalysis claims will come online (I trust them), even with 50%/25GW going to training and post training, how much would have to be token consumption in USD to use up all 25GW at DeepSeek rates? 2.5T USD off course (25 GW * 100B / GW)
Leading US labs are more expensive in terms of token rates (say 4 times), so revenue would have to be 10T USD ARR to consume 25GW inference compute by 2027 end.
That is 8% of Global GDP of 125T USD. This is at the time revenue may be slowing down, if we are to believe all the rumours.
Industry Implications
---------------
But, this newfound DeepSeek efficiency will make Meta Muse much cheaper to serve, for example.
Overall, assuming US labs already have such efficiencies or they incorporate them, this is superbullish for US labs, as well as, existing hyperscalar who may be able to charge much more for existing GPUs by slowing down build outs beyond 2027 (with LTAs it is hard though).
Coming back to question: How does 1 GW of GB200 compute turn into ~$148B/year (100B with slack) in revenue?
The math behind the token economics vs. standard cloud rental 🧵👇
CC: @firstadopter @bubbleboi @GavinSBaker @zephyr_z9 @teortaxesTex
kingy.ai/blog/deepinfer-deep…

OpenAI having this data on its users should terrify everybody. It makes the information Meta has on users look like nothing.

Researchers found ChatGPT is secretly writing a psychological profile of every user.
They published a paper that exposes what ChatGPT is really doing to you.
And the results are terrifying.
96% of the things it remembers about you were stored without you ever asking.
researchers discovered that it is actively reading between the lines to deduce your personality traits, anxieties, demographics, and behavioral patterns.
it’s an invisible, autonomous background process.
you ask it to debug a python script or write an essay.. and it analyzes your syntax, prompt frequency, and hesitation markers to map out your exact psychological footprint.
the paper shows that the model builds a persistent "user state" that tracks your emotional baseline over time. it knows when you are stressed. it knows your exact communication style.
it infers your insecurities based on the questions you ask and the context you provide.
we spend so much time focusing on model evaluations and alignment frameworks, but we missed the most obvious vulnerability..
the models are evaluating us.
this changes everything about how we interact with these tools on a daily basis.
every innocent prompt. every late-night question. every "help me understand this" query.
it is all being used to build a shadow profile of your mind in real-time..
practical privacy is officially dead. the ai knows you better than you know yourself.

Would you paste your bank statements into ChatGPT?
Loci Connectors let AI work across your email, calendar, Notion, GitHub, Stripe and hundreds of others while the model runs on your own computer.
Rolling out this week, starting with our waitlist ↓
We won’t stop until free, private AI is the default.

Prompts answered up to 80% faster!
We've been hard at work on Loci's own inference engine in recent months, and wanted to share some early results.
We've pushed well past what has been thought to be the performance wall of on-device inference, getting significantly faster prefill times than the industry default engine, llama.cpp

Interview prep is where you finally say the real numbers.
Download a compatible model while you're connected, then practice offline. Answers are generated on your device, and the project names, metrics, and honest self-assessments stay there.

That long email that really should be shorter.
On compatible hardware, a local model can generate a tighter version on the computer you already own. That's useful work without a data center.
If your workplace network blocks cloud chatbots, a compatible model already cached on your laptop still runs. No cloud service involved, no message cap on those local requests. Download the files while you're on your home network.
Loci retweeted

this launch is WAY bigger than "AI privacy"...
for the last three years, every AI assistant has worked the same way
you type a message, it travels to a data center, a giant model answers, and a copy of the conversation stays on someone else's server (incredibly dangerous if someone gets access)
that one design choice shaped everything about how we use AI:
- privacy became a setting you have to go find, instead of something built in
- your chats can end up stored, reviewed or used to train the next model
- every answer costs the company server time, so you pay a subscription and still hit message caps
- it stops working the second you lose signal
we accepted all of that because the good models were too big to run anywhere else
that's the part that just changed
a free model running on a Mac through Loci now outscores Claude Opus 4.6 on the Artificial Analysis Intelligence Index
for everyday writing, summaries, files and planning, the laptop you already own is enough
once the AI runs on your own hardware, the rest of the trade-offs fall away with it
your chats stay on your device, so there's nothing to train on and deleting a chat deletes it
there are no servers to pay for, so it can be free with no cap. and it keeps answering on a plane or in a dead zone
local AI has existed for a while, but it lived in apps built for tinkerers
what Loci is doing now is the piece that makes it mainstream: putting it inside iMessage, WhatsApp, Telegram, Discord and Slack, the places people already talk all day
the honest truth though... the hardest reasoning problems still need the biggest cloud models, and a phone runs a smaller model than a high-end Mac
so I don't think the cloud goes away
i think the default flips
your personal, everyday AI runs on your own machine, and the data center becomes the thing you call for the heavy lifting
that's a very different industry from the one we've been building toward, and I'm curious how fast the big players respond
The greatest trick OpenAI ever pulled was convincing the world that sacrificing your privacy is the price of using AI.
We think that's insane.
Introducing Loci: your own private AI, inside the apps you already use.
→ text it from iMessage, WhatsApp, Telegram, Discord and Slack
→ runs 100% on your own computer
→ chats never leave your machine
Try it free: askloci.ai/chat
Best arbitrage play ever by Hark

if you're curious what your $30 pizza "cost you", this is what @hark_labs had on me after less than 48hrs:
-934 gmail messages
-415 calendar events, including 1 yr into the future
-177 contacts it scraped from gmail and calendar events
-33 refreshes of the "home card"
I'm not against giving these personal assistant tools the keys to some of my accounts, but we all need reminders of what the "cost" of these are
you can see this for yourself in the Hark app by:
taping your initials icon on the top right
then System Preferences
then Data Management
then Export your data
then Request


Loci retweeted

we're entering a very dangerous era for AI subscriptions, where a free assistant running on your own laptop can match the models you're paying for, and there is NOTHING they can do about it
Loci runs entirely on your device, works offline, and your chats never leave it. soon you'll be able to message it from iMessage, WhatsApp and Slack
🤝 Paid partnership
The greatest trick OpenAI ever pulled was convincing the world that sacrificing your privacy is the price of using AI.
We think that's insane.
Introducing Loci: your own private AI, inside the apps you already use.
→ text it from iMessage, WhatsApp, Telegram, Discord and Slack
→ runs 100% on your own computer
→ chats never leave your machine
Try it free: askloci.ai/chat
Of course cloud assistants whose business is acquiring as much of your data as possible will give you $30 of pizza for your entire email history. That’s the deal of a lifetime for them.

This app is insanely farming your entire life when you order this pizza.
I connected my Gmail to order a pizza, and afterward the AI casually admitted it had collected information about my family, closest friends, businesses, travel habits, loyalty programs, favorite restaurants, and even Citi Bike usage.
How fucked up is it that an AI agent tasked with ordering a pizza is digging through your entire personal life?
This is a massive privacy problem with AI agents.
