




Axis Sim Training Live Kal Ho Raha Hai
Kya aap Axis Robotics simulation training ko practically seekhne ke liye taiyar hain?
@drag4_t ek live training session host karega with co-host @Retrix007 ke sath, jahan Biswa poore training process ko step by step samjheyega.
Session mein hum kya cover karenge:
→ Training tasks ko kaise access karein
→ Robot simulation ko samajhna
→ Robot movement controls
→ Wheeled Franka Tasks Ko Kaise Complete Karein
→ Trajectories kaise submit karein
→ Common errors aur troubleshooting
→ New task availability, supply aur slots
→ Live Q&A
Session Details:
📅 Thursday, 12 November 2026
⏰ 8:00 PM IST
📍 Location: Discord (Indian Voice Channel)
🎤 Host: @drag4_t
🤝 Co-Host: @Retrix007
⏳ Duration: 45 Minutes
Chahe aap beginner hon ya pehle se contribution kar rahe hon, yeh session aapko workflow samajhne aur apne training experience ko improve karne mein madad karega.
Is session ko miss mat karna. Aaiye, saath mein seekhte hain, training karte hain aur build karte hain.
Agar aap avi tak humhara Discord Join nahi kiye ho to kar lijiye : discord.gg/jYWskxESrJ

Axis Robotics India retweeted

Axis Sim Training Live is happening Tomorrow
Ready to get hands on with Axis Robotics simulation training?
I will be hosting a live training session with @Retrix007 as co-host, where we'll walk through the complete training process
What we will cover:
→ How to access training tasks
→ Understanding robot simulation
→ Robot movement controls
→ How to complete training tasks
→ How to submit trajectories
→ Common errors and troubleshooting
→ New task availability, supply & slots
→ Live Q&A
Session Details:
📅 Thursday, 12 November 2026
⏰ 8:00 PM IST
📍Location: Indian Voice Channel on DC
🎤 Host: Me
🤝 Co-Host: @Retrix007
⏳ Duration: 45 Minutes
Whether you are a beginner or already contributing, this session will help you understand the workflow and improve your training experience.
Don't miss it. Join us and let's learn, train and build together
Join DC: discord.gg/jYWskxESrJ
@axisrobotics


Lots of 3 star tasks are available on @axisrobotics
Robot Movement Controls:
I → Forward
K → Backward
J → Left
L → Right
T → Raise
G → Lower
U → Rotate Base Left
O → Rotate Base Right
Every task is an opportunity to improve your skills, earn points and make meaningful progress in Session 2
Stay consistent and keep building with the Axis Robotics ecosystem


Hum visual policy distillation ke liye ODE Policy ka use kar rahe hain aur abhi tak ka initial result kaafi achha raha hai. Actions samay ke saath kaise evolve hote hain, yeh seekhne se policy ko robot movements ki continuity ko naturally capture karne ka ek behtar tareeka milta hai.
Video mein hamara Franka robot simulation mein ek nut ko bolt par chadhana seekh raha hai aur SGS se is task ko reproduce kar raha hai.
Aage hum ODE Policy ka use karke assembly skills ki ek badi range ko policies mein distill karne ki planning kar rahe hain, jo camera images ke basis par kaam karengi. Ismein gears ko fit karna, pegs insert karna aur connectors ko jodna jaise tasks shamil hain.

We’ve been using ODE Policy for visual policy distillation, with strong early results. Learning how actions evolve over time gives the policy a natural way to capture the continuity of robot motion.
In the video, our Franka robot learns to thread a nut onto a bolt in simulation, reproducing the task from SGS.
Next, we plan to use ODE Policy to distill a wider range of assembly skills into policies that act from camera images, from fitting gears and inserting pegs to joining connectors.
Axis Robotics India retweeted
We’ve been using ODE Policy for visual policy distillation, with strong early results. Learning how actions evolve over time gives the policy a natural way to capture the continuity of robot motion.
In the video, our Franka robot learns to thread a nut onto a bolt in simulation, reproducing the task from SGS.
Next, we plan to use ODE Policy to distill a wider range of assembly skills into policies that act from camera images, from fitting gears and inserting pegs to joining connectors.

🚀 Nature does not move in discrete jumps. Why should robot policies?
Super excited to release ODE Policy — perhaps our most exciting breakthrough in my lab this year! 🤖🔥
Think about how humans reach for a cup. Our movements evolve continuously, governed by underlying dynamics. Yet, most robot policies — from Diffusion and Flow Matching to VLAs — learn to predict explicit actions.
What if robots learned how actions evolve, instead of predicting actions?
💡 That's ODE Policy for Embodied AI.
We use a neural Ordinary Differential Equation (ODE) to learn continuous action dynamics, rather than directly generating actions.
One simple idea. Five types of robots. Multiple learning paradigms.
✅ Single-arm manipulation
✅ Dual-arm manipulation
✅ Dexterous hands
✅ Humanoid whole-body control
✅ Aerial robots
And it goes far beyond imitation learning:
⚡ VLA (π0.5): 96.0% vs. 75.5% success after one epoch.
🌍 4.5B World Action Model: 82.6% vs. 24.6% success, with ~4× faster action generation.
🏃 RL: More efficient humanoid whole-body motion learning.
For years, we've focused on scaling robot data, models, and compute.
But what if the next fundamental breakthrough comes from rethinking WHAT robots learn, rather than just HOW MUCH they learn?
Huge congratulations to Jindou Jia and our amazing team! 👏
📄 Paper: arxiv.org/abs/2611.01729
🌐 Project: ntumars.github.io/ODE/
#ODEPolicy #EmbodiedAI #PhysicalAI #RobotLearning #WorldModels #VLA #MARSLab
Jab real robot data limited ho, toh co-training ke liye simulation demonstrations ka selection kaise karna chahiye?
Pesh hai TUCO: Curating Simulation Demonstrations for Sim-to-Real Robot Policy Co-Training, jo sim-to-real robot policy co-training ke liye data curation par pehli systematic study hai.
Sirf har task ke liye 10 real demonstrations aur 600 carefully curated simulation demonstrations ka use karke TUCO ne 85.8% real-robot success rate achieve ki.
Iske comparison mein, poore 1,200 demonstrations pool ya randomly selected 600 demonstrations ke saath success rate sirf 25.8% rahi.
TUCO ne teeno transfer settings mein SOTA (State-of-the-Art) performance bhi achieve ki.
Yeh research in universities ke researchers ke saath milkar ki gayi hai:
@Stanford
@NTUsg
@CarnegieMellon
@FudanUniversity
@UCBerkeley
@sjtu1896
Project Page: tuco-curation.github.io
Complete details neeche dekhein.
How should you choose simulation demos for co-training when real robot data is scarce?
Introducing TUCO: Curating Simulation Demonstrations for Sim-to-Real Robot Policy Co-Training, the first systematic study of data curation for sim-to-real robot policy co-training.
With just 10 real demos and 600 curated sim demos per task, TUCO hits 85.8% real-robot success, versus 25.8% for the full 1,200 pool or a random 600, and sets SOTA across all three transfer settings.
A collaboration with researchers from @Stanford @NTUsg @CarnegieMellon @FudanUniversity @UCBerkeley @sjtu1896.
Project page: tuco-curation.github.io/
Details below ⬇️
5/6 Simulation Experiments
Humne same protocol ke saath do simulated settings mein is criteria ko validate kiya, jisme teen seeds ka average liya gaya.
1. Single-Simulator (RoboMimic)
Ismein source aur target dono ek hi simulator share karte hain, jisse curation criteria ko domain gap se alag karke evaluate kiya ja sakta hai.
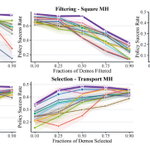
Lift, Square aur Transport tasks par TUCO ne 25 task-budget settings mein se 18 mein best ya tied-best performance di.
Lift task mein sirf 25% data use karke bhi TUCO ne all-data training ke barabar performance achieve ki.
2. Sim-to-Sim (IsaacSim se MuJoCo)
Ismein demonstrations ek simulator mein generate kiye jaate hain aur doosre simulator mein evaluate kiye jaate hain. Yeh sim-to-real gap ko controlled environment mein represent karta hai.
TUCO ne 18 settings mein se 15 mein best performance di aur sabhi 18 settings mein random selection se better results achieve kiye.
Poore IsaacSim dataset ne CupCake task ki performance ko bhi kharab kar diya, jabki carefully curated subset ne har task mein best result diya.


1
9
6/6
Jab real-world data limited hota hai, tab simulation data ki raw quantity se zyada uska carefully selection karna important hota hai.
Influence-based Utility aur Coverage ek closed-loop approach provide karte hain, jisse aise demonstrations select kiye ja sakte hain jo genuinely real robots par better transfer hote hain.
Project Page: tuco-curation.github.io
Paper: arxiv.org/abs/2610.05407
Code: github.com/Z-yiwei/tuco

14
Hum ek multi-layered robotics architecture build kar rahe hain, jahan LLM high-level reasoning aur skill harness ko control karta hai.
Yeh raha iska ek demo.
Task: Right arm ka use karke tray mein rakhi teen objects ko table ke X-axis ke along ek seedhi line mein arrange karna hai. Objects ko unki height ke according tallest se shortest order mein rakhna hai.
Aap dekh sakte hain ki agent kaise is task ko continuous movements mein convert karta hai. Skill harness ki madad se scene understanding, height ke according objects ki ordering, placement planning aur physical execution ko ek saath connect kiya jaata hai.
Yeh robotics ke future ki taraf ek bahut hi exciting shuruaat hai.
We're building a multi-layered robotics architecture, where the LLM drives high-level reasoning and skill harness.
Here's a demo. The task: use the right arm to arrange three objects from the tray in a row along the X axis of the table, ordered by height from tallest to shortest.
You can see the agent turn the task into continuous motion through skill harness, linking scene understanding, height-based ordering, and placement planning to physical execution.
This is an exciting start.
base:0x5be75e3b0aff5d1a042a5363ae36acb1d6d755ea staking ab @HTX_Global par live ho chuki hai, jahan users ko 150% tak APY earn karne ka mauka mil raha hai

Subscribe to the AXIS NewList!
Enjoy up to 150% APY:
- Subscriptions are now OPEN
- Maximum allocation: 70,000 AXIS
@axisrobotics
Start NOW 👉htx.net.im/en-us/support/750…

6
88
base:0x5be75e3b0aff5d1a042a5363ae36acb1d6d755ea Token Buyback ki Announcement
Hamara data engine real-world scenarios mein Physical AI applications ko power kar raha hai. Hum chahte hain ki har contributor ko iska direct benefit mile.
Isi liye hum base:0x5be75e3b0aff5d1a042a5363ae36acb1d6d755ea Token Buyback launch kar rahe hain, jiska pehla $150K tranche pehle hi complete ho chuka hai.
1. Commercial Deals ka Model
Hamare commercial deals pilot-first model follow karte hain. Successful pilot complete hone ke baad hi framework agreements sign kiye jaate hain. Payments bhi delivery milestones ke according alag-alag tranches mein release kiye jaate hain.
2. base:0x5be75e3b0aff5d1a042a5363ae36acb1d6d755ea Token Buyback
Aage se hamare commercial contracts se hone wale net profit ka ek hissa, payment collect hone ke saath, base:0x5be75e3b0aff5d1a042a5363ae36acb1d6d755ea tokens buy back karne ke liye allocate kiya jayega.
Har quarter ek public buyback report publish ki jayegi, jisme on-chain treasury records honge, jinhe koi bhi independently verify kar sakta hai.
Buyback ke through repurchase kiye gaye sabhi base:0x5be75e3b0aff5d1a042a5363ae36acb1d6d755ea tokens public treasury mein transfer kar diye jayenge.
Treasury Address: 0xfC8c6ABC0742E64c13d6B0bAC1fCD7e604eC7Dc5
Complete details yahan dekhein: docs.axisrobotics.ai/economi…

Aap har step ko on-chain independently verify kar sakte hain:
1. TWAP Order: explorer.cow.fi/base/twap/17…
2. Treasury Transfer: basescan.org/tx/0x71cfbe3d27…
Dono transactions blockchain par publicly available hain, jisse koi bhi buyback process aur treasury transfer ko independently verify kar sakta hai.

25
Product Update (उत्पाद में नया अपडेट)
Humne open task slots ki sankhya kam kar di hai. Aisa karne ke peeche kuch important reasons hain.
1. GPT-6 ab simple tasks solve kar sakta hai.
GPT-6 ab simple tasks ko solve karne aur unke liye reliable trajectories generate karne mein capable hai. Aage chalkar hum repetitive data collection work ko aur kam karenge.
2. Complex tasks ke liye high-quality human demonstrations ab bhi zaroori hain.
Complex tasks mein insaano ke diye gaye high-quality demonstrations bahut important hain. Inki value normal aur routine trajectories ke comparison mein kaafi zyada hoti hai.
Season 1 mein hamara focus pretraining ke liye diverse human input collect karna tha.
Ab jab woh foundation taiyar ho chuki hai, toh hamara focus RL (Reinforcement Learning), experts aur distillation ki taraf shift ho raha hai.
Kam task slots rakhne se is naye direction ko support milega aur resources high-quality feedback aur practical value par focused rahenge.
Neeche diye gaye link par hamara high-level technical roadmap dekhein.

Robot demonstrations mein naturally suboptimal performance se VLAs (Vision-Language-Action Models) ko kaise seekhna chahiye?
Pesh hai AXIS-Bench: What Matters in Quality-Aware VLA Pretraining, ek benchmark aur empirical study, jo batati hai ki robot demonstrations ki quality ko kaise define, label aur pretraining ke dauraan use karna chahiye.
3 VLAs aur 24 downstream tasks par kiye gaye experiments mein humne quality-aware learning ke alag-alag approaches compare kiye. Results se pata chala ki har model ke liye ek hi learning method effective nahi hota.
Yeh research @GeorgiaTech, @CarnegieMellon, @UCBerkeley, @NTUsg, @NUSingapore, @RiceUniversity, @UCRiverside aur @TAMU ke researchers ke saath milkar ki gayi hai.
Details aur Companion Dataset Release neeche diye gaye hain.
How should VLAs learn from naturally suboptimal robot demonstrations?
Introducing AXIS-Bench: What Matters in Quality-Aware VLA Pretraining, a benchmark and empirical study of how demonstration quality should be defined, labeled, and used during pretraining.
Across three VLAs and 24 downstream tasks, we systematically compare quality-aware learning choices and find that no single recipe works for every model.
A collaboration with researchers from @GeorgiaTech @CarnegieMellon @UCBerkeley @NTUsg @NUSingapore @RiceUniversity @UCRiverside @TAMU.
Details & Companion Dataset Release ⬇️
6/7 Data Release (Dataset Release)
Axis Dataset V1 August mein launch hua tha. Uske baad se humne Dataset V2 develop kiya hai, jo ab 1,092 tasks aur 2.35 million episodes cover karta hai (camera augmentation ke saath).
AXIS-Bench mein use kiye gaye companion datasets, sabhi Dataset V2 pool se curate kiye gaye hain.
1. Pretraining Dataset
731 tasks par based 5,000 simulated Franka demonstrations, jinmein quality labels aur frame indices bhi shamil hain.
2. Benchmark Dataset
24 held-out tasks par based 354 fine-tuning demonstrations. Ismein task definitions, success checkers, scene assets aur evaluation layouts bhi diye gaye hain.
3. Sim-to-Real Pretraining Dataset
663 tasks par based 19,250 replayable simulated episodes. Aap inhe apne workspace par dobara render karke, real demonstrations ke saath fine-tuning se pehle pretraining ke liye use kar sakte hain.
Main Takeaway:
Dono efforts alag-alag lekin ek-doosre ke complementary goals par kaam karte hain.
Axis data resource ko expand kar raha hai, jabki AXIS-Bench study karta hai ki data quality aur training choices downstream VLA performance ko kaise affect karte hain.
2
1
23
7/7 Links (महत्वपूर्ण लिंक्स)
AXIS-Bench aur hamare broader data resources ko explore karein:
Project Resources:
* Project Page: axis-bench.github.io
* Research Paper: arxiv.org/abs/2610.18869
* Code: github.com/axis-bench/axis-b…
* Axis Hub try karein: hub.axisrobotics.ai
Datasets:
* Axis Dataset V2: huggingface.co/datasets/axis…
* Pretraining Dataset: huggingface.co/datasets/axis…
* Benchmark Dataset: huggingface.co/datasets/axis…
* Sim-to-Real Pretraining: huggingface.co/datasets/axis…
Humein ummeed hai ki AXIS-Bench imperfect demonstrations se learning par hone wali research ko aur zyada reproducible aur reliable banane mein madad karega.

2
2
24